
223599 粉丝
New on Swan Inference 🧵
We just listed 5 models for roleplay & creative writing:
• MiMo V2.6 Flash RL (1M ctx)
• DeepSeek V4.1 Flash (1M ctx)
• Artemis 31B
• Skyfall 31B (TheDrummer)
• Qwen3.8 Queen 27B
Run a GPU? Serve them & earn 👇
https://github.com/swanchain/computing-provider/discussions/154
中文: 天鹅之情 🧵
我们刚刚列出了5个角色扮演模式;创意写作:
• MiMo V2.6 闪光 RL(1M ctx)
• DeepSeek V4.1 闪存(1 万 克特)
• 阿耳忒弥斯31B
• 天空31B(鼓手)
• Qwen3.8 皇后区 27B
运行GPU?服务他们;赚取👇
223599 粉丝
Raw token count hides the real bill once context and reasoning costs enter the picture. 🤔
A request with 2K output tokens doesn't necessarily cost the same as another 2K-token request.
Long context increases prefill compute.
Reasoning can add substantial inference compute.
KV-cache can reduce repeated computation while increasing GPU memory and bandwidth pressure.
Model architecture, batching, and GPU utilization further change the underlying compute profile.
For decentralized AI infrastructure, the real pricing question isn't simply:
- How many tokens were generated?
It's:
- How much compute and memory did the workload actually consume?
So what should AI infrastructure pricing actually measure: tokens, compute, or both?
-------
#SwanChain #AIInference #DePIN #DecentralizedAI
223599 粉丝
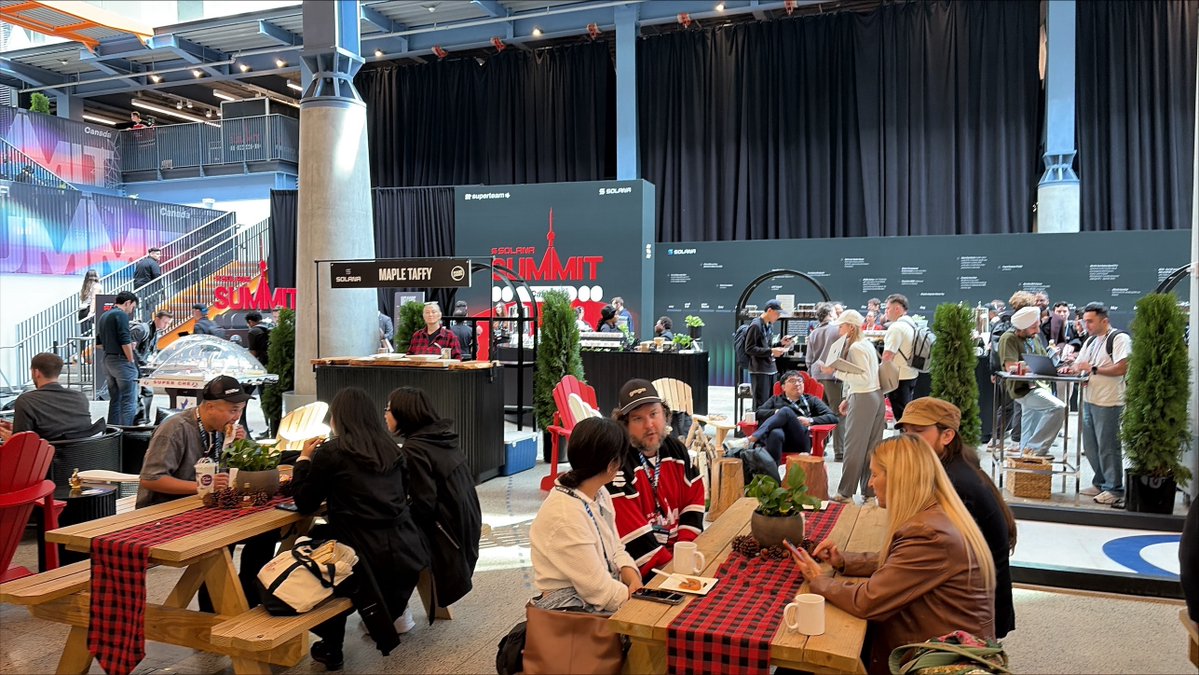
Live from #SolanaSummit today! 🚀
We’re connecting with the @solana ecosystem to explore the massive potential of decentralized computing.
We’re exploring what decentralized compute infrastructure could bring to Solana — and what new possibilities emerge when compute becomes more open, distributed, and accessible.⚡️
Early conversations, huge vision. Stay tuned! 🌐
------
#SwanChain #Solana #DecentralizedCompute #AI
中文: 今天就从#SolanaSummit现场直播!🚀
我们正在与@solana生态系统建立联系,以探索去中心化计算的巨大潜力。
我们正在探索去中心化计算基础设施能为索拉纳带来什么,以及当计算变得更加开放、分布式和可访问时,新的可能性将带来什么。EE1)
早期对话,远大愿景。敬请关注!🌐
-
#斯旺查恩 #索拉纳 #去中心化计算 #人工智能


223599 粉丝
🌐 The DePIN expansion is real.
The Swan 2.0 Decentralized AI Inference Marketplace is officially live and scaling globally!
We now have active independent GPU computing providers delivering real-time model serving from:
🇨🇦 Canada
🇳🇿 New Zealand
🇨🇿 Czechia
🇸🇰 Slovakia
🇨🇳 China
Low-latency, zero vendor lock-in, and full OpenAI-compatible API integration. Turn your idle GPUs into global AI infrastructure.
🛠️ Deploy or join the network today: https://inference.swanchain.io/
🚀#SwanChain #DePIN #AI #Web3 #Crypto #GPU
中文: 🌐 DePIN 扩展是真实的。
Swan 2.0去中心化AI推理市场正式在全球范围内上线并扩展!
我们现在拥有活跃的独立GPU计算提供商,提供以下服务:
🇨🇦 加拿大
🇳🇿 新西兰
🇨🇿 捷克
🇸🇰 斯洛伐克
🇨🇳 中国
低延迟、零供应商锁定以及完全兼容OpenAI的API集成。将空闲的GPU转化为全球人工智能基础设施。
🛠️ 立即部署或加入网络:
🚀#SwanChain #DePIN #AI #Web3 #加密#GPU

223599 粉丝
Should GPU providers set their own prices?
On one hand, it makes sense.
Different GPUs, regions, power costs, utilization and infrastructure mean different operating economics.
But there’s a trade-off.
If routing optimizes primarily for price, do we risk sending workloads to the cheapest node rather than the best-performing one?
So what makes more sense for a decentralized inference marketplace:
- Uniform pricing?
- Provider-set pricing?
- Or pricing + performance-based routing?
What would you trust?
----
#SwanChain #AIInference #Inference #AIAgents #GenerativeAI
中文: GPU供应商应该自行定价吗?
一方面,这很有意义。
不同的GPU、区域、功率成本、利用率和基础设施意味着不同的运营经济性。
但存在一种权衡。
如果路由主要针对价格进行优化,我们是否有风险将工作负载发送到最便宜的节点,而不是性能最好的节点?
那么,对于去中心化的推理市场来说,更有意义的是什么:
- 统一定价?
- 供应商设定价格?
- 或定价 + 基于性能的路由?
你会相信什么?
-
#斯旺查恩 #AI推断 #推理 #AIAgents #GeneativeAI
223599 粉丝
We’ve updated our pricing.
The old $6 Token Plan is now replaced by a simpler Prepaid Credits model:
• Any amount — list price
• $100+ — +2% credits
• $500+ — +4% credits
• $2,000+ — +6% credits
• Credits work across all models
No subscription. No model-specific plans. Just top up, use what you need, and keep the bonus.
https://inference.swanchain.io/pricing
中文: 我们已更新了定价。
旧款的6美元代币套餐现在被一种更简单的预付积分模式所取代:
• 任意金额——标价
• 超过100美元——+2% 学分
• 500美元以上——+4%学分
• 2000 美元以上——+6% 学分
• 信用额度在所有模型中均有效
无订阅。没有具体模型的计划。只需补上,使用所需内容,并保留奖金。

223599 粉丝
🚀 SwanChain Computing Provider v0.6.0 is live!
Providers can now do much more directly from the node:
⚡ Serve / stop / manage models from the CLI
🧠 Estimate VRAM before loading a model
🔄 Plan & automate model switching
🤖 Use a local AI agent to manage the node
🔔 Get alerts whenever served models change
🛠️ Better multi-GPU support + dashboard fixes
From simply declaring models → to actually running, optimizing, and automating them.
Check out the release 👇
https://github.com/swanchain/computing-provider/releases/tag/v0.6.0
中文: 🚀 SwanChain 计算服务提供商 v0.6.0 已上线!
现在,提供商可以直接从节点进行更多操作:
⚡ 从 CLI 中提供 / 停止/管理模型
🧠 在加载模型前对 VRAM 值的估算
🔄 规划并自动化模型切换
🤖 使用本地人工智能代理来管理该节点
🔔 随时更换服务型号时获取提醒
🛠️ 支持多GPU + 仪表板
从简单地声明模型→到实际运行、优化和自动化。
查看发布 👇
223599 粉丝
Not all tokens are created equal in AI inference. 📊
When setting up AI subscriptions or pay-as-you-go pricing, relying purely on raw token quotas often hides a massive economic discrepancy: the underlying compute cost.
As shown in our breakdown:
🔹 Token volume ≠ Infrastructure expense: 1 million tokens generated via a large-parameter model consumes significantly more GPU compute, energy, and hardware bandwidth than 1 million tokens on a smaller, lightweight model.
🔹 The Routing Factor: Model routing choices and payout dynamics can drastically alter the true unit economics of an inference pipeline, creating huge cost gaps between power users and casual workloads.
This raises a critical question for AI infrastructure providers and developers: Should decentralized AI pricing be strictly quota-based, model-based, or compute-cost-based?
At Swan Chain, we are constantly optimizing our decentralized inference pipelines to deliver transparent, predictable, and sustainable pricing models that benefit both creators and computing resource providers.
What pricing model makes the most sense for your AI applications? Drop your thoughts below! 👇
#DecentralizedAI #AIInference #CloudComputing #ComputeEconomics #SwanChain #AIInfrastructure

223599 粉丝
Big news for Swan Chain inference providers and builders! 🚀
We’ve added DeepSeek models to the platform! 🎉 Whether you're running nodes to serve inference requests or building decentralized AI apps, you can now seamlessly call and supply DeepSeek endpoints.
🔗 Explore models & start building: https://inference.swanchain.io/network?tab=models
-----
#SwanChain #DeepSeek #AIInference
中文: 斯旺链推理服务提供商和建设者的大好消息!🚀
我们已将 DeepSeek 模型添加到该平台!🎉 无论您是运行节点来提供推理请求,还是构建去中心化的人工智能应用,现在都可以无缝调用和提供 DeepSeek 终端。
🔗 探索模型并开始构建:
--
#斯旺查恩 #深景#AI推理

223599 粉丝
Big news for Swan Chain inference providers and builders! 🚀
We’ve added DeepSeek models to the platform! 🎉 Compute providers can now host, route, and monetize DeepSeek inference directly on Swan Network.
🔗 Check it here: https://inference.swanchain.io/network?tab=models
-----
#SwanChain #DeepSeek #AIInference
中文: 斯旺链推理服务提供商和建设者的大好消息!🚀
我们已将 DeepSeek 模型添加到该平台!🎉 计算服务提供商现在可以直接在Swan Network上托管、路由和实现DeepSeek推理的变现。
🔗 请点击此处查看:
--
#斯旺查恩 #深景#AI推理
223599 粉丝
Should inference providers have a minimum payout guarantee?
Today, subscription traffic is paid from a shared pool. If usage exceeds subscription revenue, provider payouts are reduced proportionally.
That protects the protocol — but leaves providers carrying most of the demand risk.
If providers can't predict their yield, network stability suffers.
Would a minimum payout floor make decentralized inference more sustainable, or does it shift too much risk back to the network?
What's the right balance?
What’s your take on this? Share below!
中文: 推理提供方是否应提供最低赔付保证?
如今,订阅流量是从共享池中支付的。如果使用量超过订阅收入,则按比例减少服务提供商的支出。
这保护了协议,但使供应商承担了大部分需求风险。
如果供应商无法预测其收益,网络稳定性就会受到影响。
最低赔付金额会使去中心化推断更具可持续性,还是会将过多风险转回网络?
正确的平衡是什么?
你对此有什么好做的?分享下方!
223599 粉丝
🚀 Swan Inference Network is growing fast.
In the last 24 hours:
• 5,418 requests — ↑ 53.8%
• 48.7M tokens — ↑ 62.3%
• 6 providers online
• 26% network capacity utilized
More inference. More providers. More real workloads running on decentralized GPU infrastructure.
And we’re just getting started. 🦢
#SwanChain #AI #DePIN #GPU #Inference

223599 粉丝
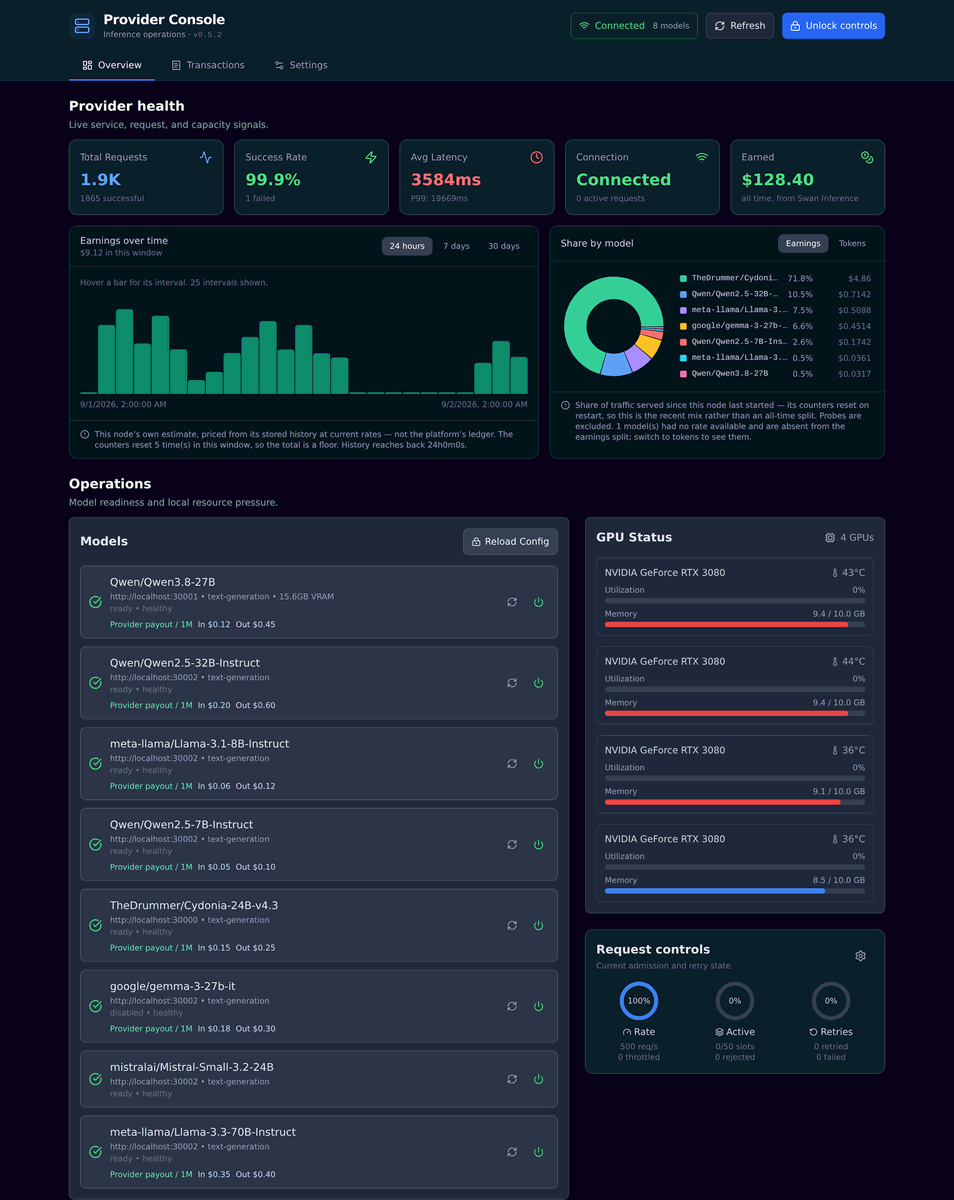
🚀 The new Swan Chain Provider Console v0.5.2 is live!
Monitor requests, latency, earnings, model traffic, GPU health, and capacity—all from one dashboard.
https://github.com/swanchain/computing-provider
Put your GPUs to work with Swan Chain. https://inference.swanchain.io/
#SwanChain #DePIN #AI #GPU https://twitter.com/swan_chain/status/2094994409058168901/photo/1
中文: 🚀 全新Swan Chain Provider Console v0.5.2 已上线!
监控请求、延迟、收益、模型流量、GPU 和容量——全部通过一个仪表板进行监控。
使用您的 GPU 与 Swan Chain 协作。
#SwanChain #DePIN #AI #GPU
223599 粉丝
40M tokens doesn't mean 40M tokens of compute. 🔁
In decentralized inference, the real cost depends on more than token count:
→ Model selection
→ Input/output mix
→ Provider payout rates
→ Routing behavior
→ Hardware economics
Two users can consume the same token quota while creating very different costs for the network.
So should inference subscriptions be priced by tokens, models, or actual compute cost?
Curious how the Swan community would design it.? How would you design it? Drop your thoughts below!👇
中文: 4000万代币并不意味着计算的4000万枚代币。🔁
在去中心化推断中,实际成本取决于比代币计数更多:
→ 模型选择
→ 输入/输出混合
→ 供应商支付费率
路由行为
硬件经济学
两名用户可以使用相同的代币配额,同时为网络带来截然不同的成本。
那么,推理订阅是否应该以代币、模型或实际计算成本来定价?
好奇斯旺社区会如何设计它。你会如何设计它?放下你的想法!👇

223599 粉丝
RT @0charlescao: Serving real clients with my own RTX GPUs. 🚀
This is what self-hosted AI looks like. https://twitter.com/0charlescao/status/2094105805125509159/photo/1
中文: RT @0charlescao:使用我自己的RTX GPU为真实客户提供服务。🚀
这就是自托管人工智能的外观。

223599 粉丝
How should Swan’s Token Plan evolve? 🦢
Our latest community discussion explores how to build a more sustainable model for users, providers, and the network:
→ Multiple subscription tiers
→ Stake SWAN for inference quota
→ Minimum provider payout guarantees
→ Uniform vs. provider-set pricing
With August subscription revenue at $18 vs. $27.35 in accrued compute costs, there’s an important question to solve:
How should decentralized inference balance affordability, provider incentives, and sustainable economics?
Join the discussion and share your thoughts 👇
🔗https://github.com/swanchain/governance/discussions/24

223599 粉丝
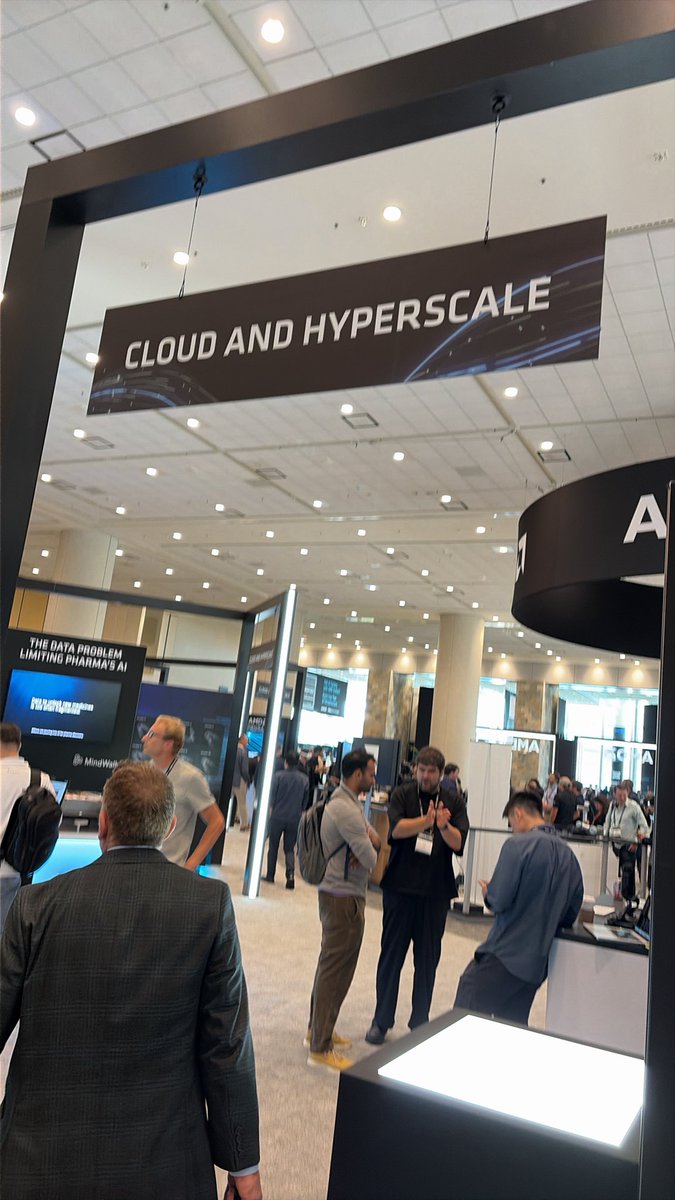
AMD is good for inference! https://twitter.com/swan_chain/status/2085319110695501921/photo/1


223599 粉丝
🚀 New models just landed on Swan Inference:
✦ Claude Fable 5, Sonnet 5 & Opus 4.8
✦ GPT-5.5, GPT-5.4 & 5.4-mini
✦ Gemini 3.6 Flash & 3.5 Flash Lite
✦ Cydonia-24B v4.3
One OpenAI-compatible API for all of them. Try them in the playground → https://inference.swanchain.io/
223599 粉丝
RT @nebulablockdata: Kimi K3 is now live on Nebula Block 🤝
Moonshot AI's flagship model with a 1M-token context window, built for long-hor…
223599 粉丝
🚀 Swan Inference Network Expansion: Next-Gen AI Models Now Live!
We’re expanding our decentralized infrastructure with the market's latest, high-performance AI models - now officially live and optimized on Swan Chain.
Developers can now leverage elite intelligence with… https://t.co/1MzTHXhL1Z

223599 粉丝
In #vivatech 2026, we talk to lots of startups almost everyone needs GPU and computing power! Try https://t.co/iqHJ5fk6a9! https://twitter.com/swan_chain/status/2067526645351621029/photo/1
中文: 在2026年的#vivatech中,我们与许多初创公司进行了讨论,几乎每个人都需要GPU和计算能力!试试


223599 粉丝
🚀 Gemma 4 on SwanChain.
✅ 31B is live now
📅 12B arrives June 10
Optimized for:
🎭 AI Roleplay
👤 Digital Humans
🤖 AI Companions
🏢 AI Employees
Run powerful Gemma 4 models with lower VRAM requirements and production-ready inference on SwanChain.
https://t.co/eZm9lWVz0P… https://twitter.com/swan_chain/status/2063771595156414687/photo/1

223599 粉丝
⚡ Gemini 3.5 Flash is now available on Swan Inference.
Start building with Gemini 3.5 Flash today:
https://inference.swanchain.io/models/gemini%2Fgemini-3.5-flash
#AI #LLM #Gemini #Inference #AIAgents #SwanChain #GenerativeAI https://twitter.com/swan_chain/status/2057695233991725228/photo/1
中文: ⚡ Gemini 3.5 Flash 现已在 Swan Inference 上推出。
立即开始使用 Gemini 3.5 Flash 进行构建:
#AI #LM #Gemini #推理 #AIAgents #SwanChain #GenerativeAI

223599 粉丝
⚡ Gemini 3.5 Flash is now available on Swan Inference.
Ultra-fast inference, low latency, and optimized efficiency for next-gen AI agents and real-time applications — now live on Swan’s unified inference platform.
Start building with Gemini 3.5 Flash today:… https://twitter.com/swan_chain/status/2057695170154430817/photo/1
中文: ⚡ Gemini 3.5 Flash 现已在 Swan Inference 上上线。
超快推理、低延迟和优化效率,适用于下一代人工智能代理和实时应用——如今已在斯旺的统一推理平台上线。
立即开始使用 Gemini 3.5 Flash 进行构建:
223599 粉丝
⚡ Gemini 3.5 Flash is now available on Swan Inference.
Ultra-fast inference, low latency, and optimized efficiency for next-gen AI agents and real-time applications — now live on Swan’s unified inference platform.
Start building with Gemini 3.5 Flash today:
Swan Inference –… https://twitter.com/swan_chain/status/2057694915828539673/photo/1
中文: ⚡ Gemini 3.5 Flash 现已在 Swan Inference 上上线。
超快推理、低延迟和优化效率,适用于下一代人工智能代理和实时应用——如今已在斯旺的统一推理平台上线。
立即开始使用 Gemini 3.5 Flash 进行构建:
天鹅之投——
223599 粉丝
RT @googlegemma: Gemma 4 can run on phones without an internet connection! 🤯
It can perform local agentic tasks, such as logging and analy…
中文: RT @googlegemma:Gemma 4 可以在没有网络连接的情况下在手机上运行!🤯
它可以执行本地代理任务,例如日志记录和环境管理......
223599 粉丝
Gemma 4 31B is Online! https://inference.swanchain.io/models/google%2Fgemma-4-31b-it https://twitter.com/swan_chain/status/2041400996975313210/photo/1
中文: Gemma 4 31B 上线了!

223599 粉丝
🗳️ SIP-003 vote ends tomorrow.
✅ FOR = transition to Swan 2.0
→ End UBI, providers earn 95% in stablecoins, hardware tiers, 20% SWAN discount
❌ AGAINST = keep current UBI model
→ Emissions continue, no hardware requirements, no inference revenue
Vote: https://governance.swanchain.io/
中文: 🗳 明天结束 SIP-003 投票。
✅ 为 = 向 Swan 2.0 过渡
→ 终止UBI,供应商在稳定币、硬件等级方面可获得95%的收益,可享受20%的SWAN折扣
❌ 反对 = 保持当前的UBI模型
→ 持续排放,无硬件要求,无推断收入
投票:
223599 粉丝
Check https://inference.swanchain.io/ it is alive! https://twitter.com/swan_chain/status/2037300277171167714/photo/1
中文: 请查看 它是活的!

223599 粉丝
Swan Chain 2.0 goes live on mainnet this Thursday night (EST).
A real inference marketplace — not subsidies, not promises.
中文: Swan Chain 2.0 将于本周四(美国东部时间)在主网上上线。
真正的推理市场——不是补贴,不是承诺。
223599 粉丝
📢 Swan 2.0 is Live — computing-provider v0.1.0 Released
Today marks the last day of the legacy flat UBI. Starting tomorrow, Swan 2.0 contribution-weighted rewards go into effect.
What this means:
Providers serving real inference earn USDC/USDT directly (95% revenue share)
Idle…
中文: 📢 Swan 2.0 是实时的——计算提供器 v0.1.0 发布
今天是传统版UBI的最后一天。从明天开始,Swan 2.0 的加权奖励将生效。
这意味着:
提供真实推断服务的提供商直接获得USDC/USDT(占收入95%)
闲置......
223599 粉丝
Swan 2.0 is live on March 16.
A full redesign of how Swan works:
Market-driven inference marketplace replacing UBI subsidies
Tiered model catalog with per-token pricing
95% revenue directly to providers — in stablecoins
Pay-with-SWAN for 20% off inference
OpenAI-compatible API… https://twitter.com/swan_chain/status/2032006972082622578/photo/1
中文: Swan 2.0 将于 3 月 16 日上线。
对Swan的工作原理进行全面重新设计:
市场驱动的推理市场取代全民基本收入补贴
带按代币定价的分层模型目录
直接向供应商提供95%的收入——在稳定币中
使用SWAN支付20%的分期付款
兼容OpenAI的API......

223599 粉丝
Swan 2.0 is live on March 16.
SIP-003 proposes a full redesign of how Swan works:
Market-driven inference marketplace replacing UBI subsidies
Tiered model catalog with per-token pricing
95% revenue directly to providers — in stablecoins
Pay-with-SWAN for 20% off inference… https://twitter.com/swan_chain/status/2032006849567101105/photo/1
中文: Swan 2.0 将于 3 月 16 日上线。
SIP-003 提议全面重新设计 Swan 的工作方式:
市场驱动的推理市场取代全民基本收入补贴
带按代币定价的分层模型目录
直接向供应商提供95%的收入——在稳定币中
使用SWAN支付20%的折扣......