
92749 粉丝
personal take: beautiful tbh, I'm tired of lack of authenticity everywhere
中文: 个人取品:美丽,我厌倦了到处缺乏真实感
92749 粉丝
you don't need large GPUs to run most decision models, this makes them a perfect match for llama.cpp
give the blog a read on how to get them up and running!
team will support more and more models in upcoming days
中文: 运行大多数决策模型时,无需大型GPU,这使它们与lama.cpp完美匹配
让博客阅读一下如何让他们启动并运行!
团队将在未来几天支持越来越多的模型
92749 粉丝
I bought a kobo just to read papers because I'm tired of looking at white light most of the day
but e-ink glitches when zooming in-out
does anyone have any suggestions 👀 https://twitter.com/mervenoyann/status/2106008694844469418/photo/1
中文: 我买一个kobo只是为了看论文,因为我厌倦了每天大部分时间看白光
但放大时电子墨水会小故障
有谁有建议吗👀

92749 粉丝
rebranding of zero-shot classification models as decision models wasn't on my 2026 bingo card
but happy people finally discovered them
中文: 将零点分类模型重新命名为决策模型并不在我2026年的宾果卡上
但快乐的人终于发现了它们
92749 粉丝
I have opinions on my own form factor, I wish I was a microduck tbh
中文: 我对自己的体质有看法,希望自己能成为一个微鸭
92749 粉丝
RT @_alejandroao: OpenAI launched dots. Here's how to build your own dots-style assistants with:
> Pi as the harness
> Custom gateway to connect to Telegram
> Your choice of models (local, open, etc).
> Google Workspace skills
Run them on a VPS, Desktop, DGX, etc. Have fun!! https://twitter.com/_alejandroao/status/2105933217383731527/video/1
中文: RT @_alejandroao:OpenAI 推出了 dots。以下是使用以下工具打造您自己的点式助手:
皮具作为线束
> 可连接到 Telegram 的自定义网关
选择您的型号(本地、开放等)。
谷歌工作区技能
在VPS、Desktop、DGX等平台上运行它们。玩得开心!!
🎬
视频
92749 粉丝
I feel like we'd get along so well ngl he'd love to be on our slack I swear 🌝
中文: 我觉得我们相处得非常顺利,他很想待在我们的闲置上,我发誓🌝
92749 粉丝
Hugging Face ml-intern myths debunked
> ml-intern is an open-source ML eng/research harness you can use on your own local setup for free ✅
> it is hosted on Hugging Chat because we want no code interface for people to train their sota models in any task ✅
> second option uses our infra, ml-intern picks the cheapest GPU for your tasks so you get your model for few dollars only
for instance @MaziyarPanahi trained a Jev model simply by prompting today for $6, no code 🙌🏼
中文: 拥抱面部ml-intern的误解被揭穿
ML-intern 是一款开源的机器学习 eng/research 线束,可免费在您本地的设置中使用 ✅
它被托管在“拥抱聊天”上,因为我们不希望人们在任何任务中训练其 sota 模型的代码界面 ✅
第二种选择使用我们的红外线、毫升式实习生,为您的任务选择最便宜的GPU,只需几美元即可购买
例如,@MaziyarPanahi 通过今天只需花费 6 美元就使用 ev 模型来训练,无需使用代码 🙌
92749 粉丝
RT @mervenoyann: we have something better than coding agent (an ML engineering/research harness), it's open-source, but also you can try it here, it's ml-intern https://huggingface.co/chat/
中文: RT @mervenoyann:我们拥有比编程代理(机器学习工程/研究工具)更好的工具,它是开源的,但你也可以在这里尝试,网址为 ml-internt
92749 粉丝
Hugging Face has coding agents 😏
中文: 拥抱面子有编码代理😏
92749 粉丝
in case you want to learn how to do it, we already have four video series on youtube 🤝
https://www.youtube.com/watch?v=rNgUoH7Wbv8&list=PLo2EIpI_JMQvQZm-kVlz4wY1vWF0LBcf5&index=3
中文: 如果你想学习如何做,我们已经在YouTube上播播了四部视频🤝
92749 粉丝
btw if you want to learn to train models to be agents, we have a four chapter series on youtube with everything open-source 🙌🏻
get started here https://www.youtube.com/watch?v=rNgUoH7Wbv8&list=PLo2EIpI_JMQvQZm-kVlz4wY1vWF0LBcf5&index=3
中文: 如果你想学习培养模型成为代理,我们在YouTube上推出了一个四章系列,内容为开源🙌🏻
从这里开始:
92749 粉丝
pewdiepie does.. *checks notes* agentic training https://youtu.be/ODDJXGY_1kQ?is=6BUanblN64iBJvxd
> he doesn't mention the tool I think he just says he does grpo
> he wanted to distill Sol but got banned few times
> he built a website for people to donate traces but no one did (he could have just went to Hub 🌝)
I just want to help him out so bad but there's no way to reach out the man 🌝
中文: pewdiepie 确实有......*检查笔记* 特化培训
他没有提到那个工具,我认为他只是说自己擅长
他想蒸馏索尔,但被禁赛次数很少
他建立了一个网站供人们捐赠痕迹,但没有人这样做(他本可以去Hub 🌝)
我只是想帮他这么难,但没有办法联系到那个人🌝
92749 粉丝
we have something better than coding agent (an ML engineering/research harness), it's open-source, but also you can try it here, it's ml-intern https://huggingface.co/chat/
中文: 我们拥有比编程代理(机器学习工程/研究工具)更好的工具,它具有开源的源代码,但你也可以在这里尝试,它是ml-intern 的
92749 粉丝
big thanks @cetiennec & @NepYope for le demo 🙌🏼
中文: 非常感谢 @cetiennec & @NepYope 的演示 🙌🏼
92749 粉丝
microduck is out for a walk 🥹 https://twitter.com/mervenoyann/status/2105324590797119604/video/1
中文: 微鸭外出散步了 🥹
🎬
视频
92749 粉丝
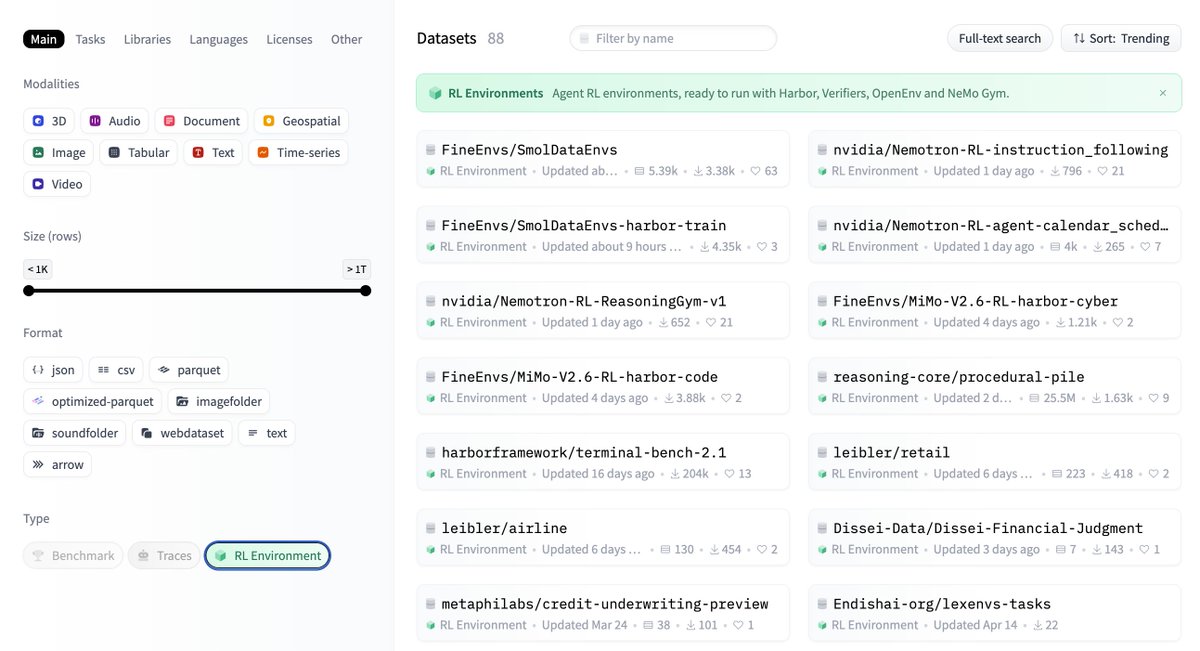
RL environments now ship in datasets on @huggingface Hub 🙌
browse all of them here https://huggingface.co/datasets?other=rl-environment&sort=trending https://twitter.com/mervenoyann/status/2105306860693708930/photo/1
中文: RL 环境现已发布在 @huggingface Hub 上 🙌 的数据集中
请在此处浏览全部内容:
92749 粉丝
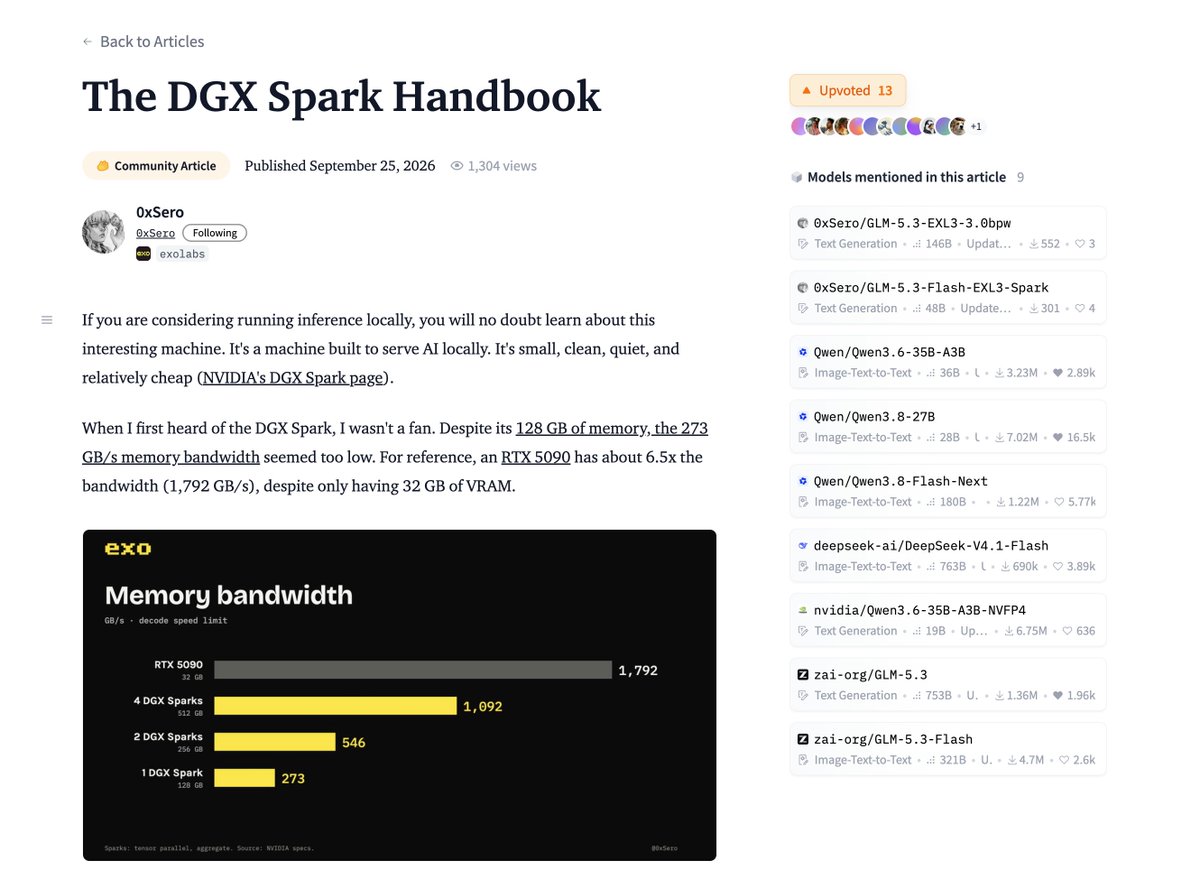
RT @julien_c: Really great little DGX Spark guide from @0xSero
read it on HF https://huggingface.co/blog/exolabs/the-dgx-spark-handbook https://twitter.com/julien_c/status/2105008672527249665/photo/1
中文: RT @julien_c:来自 @0xSero 的 MENT 小 DGX Spark 指南
在 上阅读
92749 粉丝
absolute microduck world dominance continues on dev day @romainhuet 🦆💗 https://twitter.com/mervenoyann/status/2104992004543492190/photo/1
中文: 绝对的微鸭世界主导地位在开发日 @romainhuet 🦆💗 继续
92749 粉丝
RT @halcyonrayes: world models are coming faster than we realize 🌎
so i wrote a blog that tells you what they are, what the state of the art looks like, what the eval axes look like, and how you can stay updated 🚀
check it out here 🤗 --
https://huggingface.co/spaces/suvadityamuk/world-models-simulation-strikes-back
https://x.com/halcyonrayes/status/2100677919555367336 https://twitter.com/halcyonrayes/status/2104571839980917033/photo/1
92749 粉丝
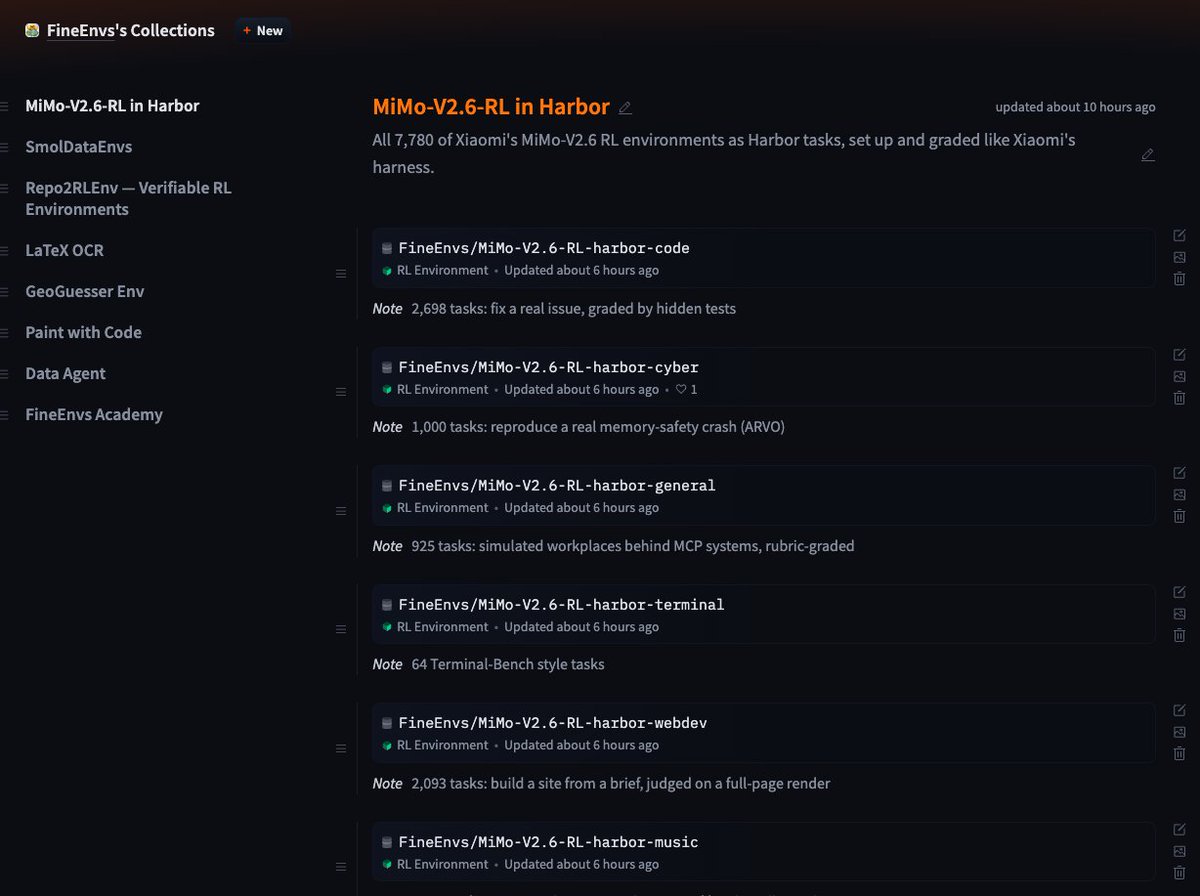
RT @adithya_s_k: 7K+ RL environments, all in a uniform Harbor format.
> Pick a task, pick a model, pick a harness, pick a sandbox provider, and run it
ps : with OpenEnv you can directly train on these as well not just eval, there’s an Easter egg somewhere 👀 https://twitter.com/adithya_s_k/status/2104113338078896630/photo/1
92749 粉丝
this + SmolDataEnvs are huge efforts for AI sovereignty of every company, country
don't sleep on it
92749 粉丝
RT @HarveenChadha: was looking for a quiet weekend but xiaomi dropped their rl envs repo last night
to put in perspective, if you have to buy some tasks like this its usually hundred to thousand dollars per task so this repo is literally worth millions
https://huggingface.co/datasets/XiaomiMiMo/MiMo-V2.6-RL-oss https://twitter.com/HarveenChadha/status/2103747414775804223/photo/1
中文: RT @HarveenChadha:当时正在寻找一个安静的周末,但昨晚xiaomi放弃了他们的 rvs repo
从角度来看,如果你必须购买一些类似的任务,通常每个任务需要花费数百到几千美元,那么这个回购实际上价值数百万美元
92749 粉丝
RT @adithya_s_k: Releasing SmolDataEnvs 🤗
5K+ Verifiable RL Environment tasks for hill-climbing small models in code and data science.
Completely open source: environments, evals, training https://twitter.com/adithya_s_k/status/2103181855214432556/video/1
中文: RT @adithya_s_k:发布 SmolDataEnvs 🤗
用于编程和数据科学中爬坡小型模型的5K+可验证RL环境任务。
完全开源:环境、椭圆形、培训
🎬
视频
92749 粉丝
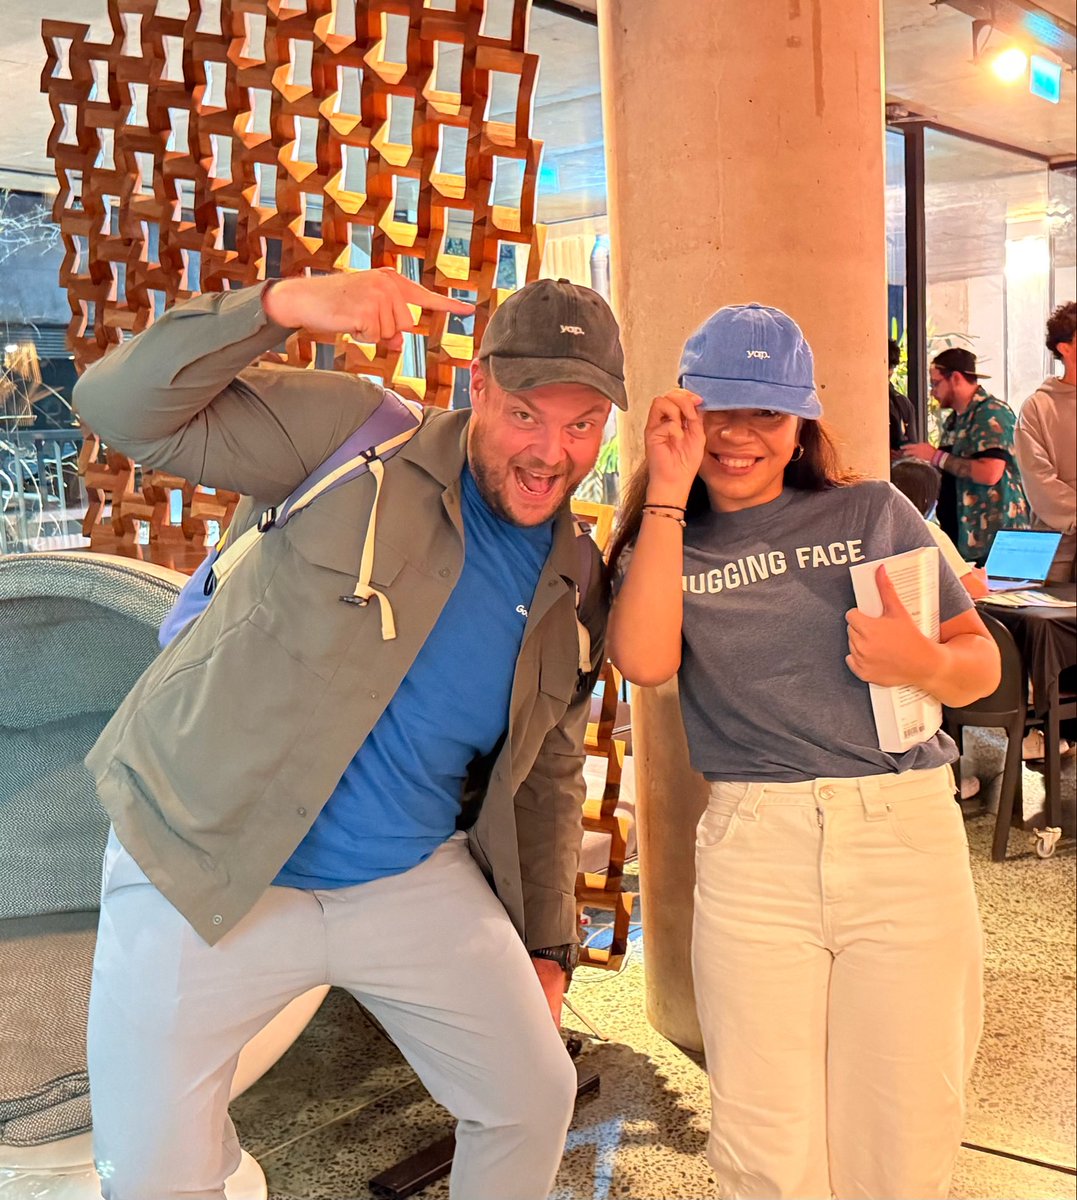
I have a gemini audio yap cap courtesy of @osanseviero @thorwebdev 🥹 https://twitter.com/mervenoyann/status/2103259232305082409/photo/1
中文: 我有一张由@osanseviero @thorwebdev 提供的 jemini 音频 yap 帽 🥹
92749 粉丝
RT @nerdearla: 📣 @mervenoyann nos viene a hablar sobre "Local AI Ecosystem": todo lo que hay para correr modelos de IA en tu propia máquina. 💻
Terminando el día 3 en📍 Gran sala
Entrá al vivo: https://nerdear.live/
#Nerdearla 🇦🇷 https://twitter.com/nerdearla/status/2103236660146458735/video/1
🎬
视频
92749 粉丝
RT @ClementDelangue: If you believe the risk is coming from 1-3 people in a garage with no money and no compute, you just don't understand this technology and haven't learned anything this summer.
Risk comes from the asymmetry of capabilities created by secret labs training frontier agents and running them with massive amount of compute. Open-source is exactly the solution to this asymmetry and empowers hospitals (and any smaller orgs) to defend themselves!
中文: RT @ClementDelangue:如果你认为风险来自车库里1到3人,没有钱,也没有计算能力,那你就是不懂这项技术,今年夏天也什么都没学到。
风险源于秘密实验室训练前沿人员并使用大量计算来运行它们所产生的能力不对称性。开源正是解决这种不对称的方法,使医院(以及任何较小的机构)能够自我保护!
92749 粉丝
RT @jackyk02: Introducing Contrastive Language Model (CLM): an ultra-fast System One Model trained with a contrastive learning objective that connects states and actions.
CLM-8B is pre-trained on internet-scale data and delivers up to 9× faster inference than Jev ⚡ while achieving comparable performance across computer-use, gaming, and tool-calling tasks.
With lightweight fine-tuning, CLM-8B sets a new SOTA on challenging agentic coding benchmarks, such as DeepSWE (81.6%) and Terminal-Bench 2.1 (87.6%). In contrast, Jev fails to serve as an effective verifier for these long-horizon tasks.
We also build an efficient training and serving infra for CLMs by disaggregating states and actions, allowing their embeddings to be cached and reused independently. This substantially reduces inference latency in settings where the state evolves continuously while the action set remains fixed.
Finally, we establish scaling laws for CLMs and show that the test contrastive loss decreases predictably as a power law in training compute, model size, and dataset size.
📄 Blog: https://contrastive-lm.notion.site/
💻 Code: https://github.com/Contrastive-LM/CLM
🗣️ Discord: https://discord.gg/5dAQEDJBs
🤗 Data & Models: https://huggingface.co/Contrastive-LM
More details on CLM’s architecture, data recipe, and scaling laws in the thread below 🧵
🎬
视频
92749 粉丝
RT @NVIDIAAI: When several people talk at once, a transcript can get messy fast.
Our new Nemotron 3 Diarization model tracks who spoke when, even when voices overlap. It handles up to eight speakers, has 100M parameters, and is now available on @huggingface 🤗 https://twitter.com/NVIDIAAI/status/2102775666366435450/video/1
中文: RT @NVIDIAAI:当几个人同时交谈时,文字记录可能会很快变得混乱。
我们的新款Nemotron 3 Diarization模型会追踪谁说话,即使声音重叠。最多可处理八个扬声器,具有100M参数,现可在@huggingface 🤗上查看。
🎬
视频
92749 粉丝
RT @trycua: 1/ Today we're introducing Cua-S1-4B-0.2, the first multimodal decision model trained with RLOO on live computer-use tasks, using task-completion rewards.
Text and multimodal adapters are available under Apache-2.0: https://github.com/trycua/cua
https://huggingface.co/cua-ai/cua-s1-4b-0.2
中文: RT @trycua:1/ 今天我们推出 Cua-S1-4B-0.2,这是首个使用 RLOO 训练的基于实时计算机使用任务处理任务的多模态决策模型。
文本和多模态适配器可在 Apache-2.0 下使用:
🎬
视频
92749 粉丝
RT @julien_c: 📦 New JS package just dropped: huggingface/lerobot
Read @LeRobotHF datasets on the Hub straight from the browser. No download.
Point your coding agent at it and build custom viewers fast.
As an example, here's a cool UI implemented in ~600 lines of JS on top of the package ⤵️ (GitHub repo in reply)
Kudos to @mishig25 and team LeRobot!
中文: RT @julien_c:📦 新JS套餐刚刚下落:拥抱脸/ lerobot
直接从浏览器在Hub上阅读@LeRobotHF数据集。无需下载。
将你的编码代理指向它,并快速构建自定义的观众。
例如,在包的 ~600 行 JS 中实现了一个酷炫的用户界面 ⤵️(GitHub repo 回复)
向 @mishig25 和 LeRobot 团队致敬!

92749 粉丝
RT @LysandreJik: Transformers has supported loading GGUF files for a few years now, by unquantizing them.
Thanks to @_marcsun, we're now using GGML kernels through the `kernels` library to run at the same performance as llama.cpp
Huge kudos to the entire @ggml_org for making these kernels! https://twitter.com/LysandreJik/status/2102399217604141078/photo/1
中文: RT @LysandreJik:Transformers 多年来一直支持加载 GGUF 文件,但未对文件进行量化。
感谢 @_marcsun,我们现在通过 `kernels` 库使用 GGML 内核,以与 llama.cpp 相同的性能运行
非常感谢 @ggml_org 制作这些内核!

92749 粉丝
I wonder if @ben_burtenshaw ever knew we'd be too powerful when I had learned about excalidraw because look at this https://twitter.com/mervenoyann/status/2102468460119020015/photo/1
中文: 我想知道,当我得知“excalidraw”时,是否曾知道@ben_burtenshaw会过于强大,因为请看这个


92749 粉丝
RT @PyTorch: How do you keep @vllm_project moving at the speed of light without excluding users who run diverse models on diverse hardware?
In a new PyTorch Foundation blog, contributors from @IBM, @Meta, and @huggingface introduce hardware-agnostic layers designed to balance frontier performance with portability, helping ensure vLLM continues to meet the needs of the broader open source ecosystem.
Read the blog to learn more: https://bit.ly/4xEH7Wk
@hmellor_ @th_ortner
中文: RT @PyTorch:如何在不排除使用不同硬件的不同型号的用户的情况下,保持@vllm_project以光速运行?
在一个新的PyTorch基金会博客中,来自@IBM、@Meta和@huggingface的撰稿人介绍了硬件无关的层次结构,旨在平衡前沿性能与便携性,有助于确保vLLM持续满足更广泛的开源生态系统需求。
阅读博客了解更多信息:
@hmellor_ @th_ortner

92749 粉丝
when I write docs you will not know but there will be signs https://twitter.com/mervenoyann/status/2102409226828333058/photo/1
中文: 当我写文档时,你不会知道,但会有标识

92749 粉丝

92749 粉丝
RT @ArtificialAnlys: MiMo-V2.6-Pro debuts as the top open weights model on the Artificial Analysis Intelligence Index (46). At $0.13 per Intelligence Index task, it lands on the Intelligence vs. Cost per Task Pareto frontier
@Xiaomi has just released MiMo-V2.6-Pro, an open weights model with major advances in intelligence over its predecessor, MiMo-V2.5-Pro (Intelligence Index: 26). Despite the improvement, it retains the same attractive pricing at $0.435 per 1M input tokens (with a 99% cache-hit discount) and $0.87 per 1M output tokens. This makes MiMo-V2.6-Pro one of the most cost-efficient models to deploy.
MiMo-V2.6-Pro is an MoE model with 1.02T total parameters and 42B active parameters. Stay tuned for additional analysis of the model.
Check out MiMo-V2.6-Pro full benchmarking breakdown here: https://artificialanalysis.ai/

92749 粉丝
MiMo-V2.6 is out and the results seem to put it right after GPT-5.6 Sol 🥹
same arch as V2.5, comes with 1M context window and MTP drafter
waiting for AA results 👀
https://huggingface.co/XiaomiMiMo/MiMo-V2.6-Pro-RL
中文: 米莫-V2.6已出局,结果似乎在GPT-5.6索尔之后就已公布。🥹
与V2.5相同的拱门,带有1M上下文窗口和MTP选型
等待AA结果 👀
92749 粉丝
looking at how agents talk to humans and on the openai tech report on Hugging Face incident, how they talk to each other, I'm actually curious where they picked up these lingos no one talks about this
is there a paper on how agent collab mixtures are curated?
中文: 看着特工们如何与人类交谈,以及在关于“拥抱面子事件”的公开科技报告中,他们彼此交谈时,我确实好奇他们究竟是从哪里发现这些语言的,而没有人谈论这些
有关于如何挑选代理合作混合物的论文吗?
92749 粉丝
leaving a few beginner friendly guides for classifiers (normal and zero-shot) as well as where you can find them on the Hub
opt for DeBERTa and ModernBERT ones
> https://huggingface.co/models?pipeline_tag=zero-shot-classification&sort=trending
> https://huggingface.co/tasks/zero-shot-classification
> multimodal (image <> text) https://huggingface.co/docs/transformers/en/tasks/zero_shot_image_classification
92749 粉丝
btw I'm not specifically speaking for Jev because we don't know what it is
I just appreciate BERT wherever I can because it's still beautiful and simple to this day :p
中文: 我并不是专门为杰夫说话,因为我们不知道它是什么
我只是珍惜伯特在任何地方,因为直到今天依然美丽而简单:p
92749 粉丝
I just found the first ever side project BERT I uploaded on Hub, it's been five years, I was so young and naive
中文: 我刚刚在Hub上找到了我上传的第一个副项目BERT,已经五年了,我太年轻又天真
92749 粉丝
also zero-shotting DeBERTa or whatever*
中文: 也以零击的德伯塔或其他任何东西
92749 粉丝
people who compare Jev against GPT-5.6 has never fine-tuned BERTForXYZ for living and it shows
joke aside I always found zero shot classifiers to be fascinating and was sad we never got people to scale them as much as decoder only models
many problems solved with LLMs could have been solved with them, it was a skill issue
中文: 将捷夫与GPT-5.6进行比较的人从未对BERTForXYZ进行过年居的细微调整,这表明
抛开笑话不谈,我总觉得零镜头分类器很吸引人,而且我们从来就从不像解码器模型那样让人进行评分
使用LLM解决的许多问题都可以解决,这是一个技能问题
92749 粉丝
pseudoannotate the problem/task itself from scratch given a website* not pseudoannotate a given problem
because tasks are also outdated
中文: 从零开始对问题/任务本身进行伪注释,因为网站* 未伪注释给定的问题
因为任务也已经过时了
92749 粉丝
one of the latest free-time side projects I had was to pseudo-annotate dataset for CUA agents running in internet
issue is, you need the agents to actually go to websites, do a certain task and reward. all the internet datasets out there are outdated because websites constantly change, so you need to 1. pseudo annotate for a given problem 2. figure out a completion criterion for the problem which can be verifiable + unverifiable depending on the task
an issue is bypassing cloudflare, I think browserbase did a good job. I wrote a leaner harness + env with openenv, helium and used HF sandbox and couldn't bypass (could be a skill issue) I worked with what I had
then the reward itself is another, often times you use a large VLM to grade the unverifiable parts, and then use DOM etc to do verifiable rewards there's many know-hows I lack but that only makes it much more fun to play with
中文: 我最近的一个免费兼职项目是为在互联网中运行的CUA代理提供伪注释数据集
问题是,你需要代理人员实际前往网站,完成特定任务并给予奖励。由于网站不断变化,所有互联网数据集都已过时,因此你需要对某个问题进行1次伪注释。2 为问题找出一个可验证且无法验证的完成标准
问题在于绕过云天地,我认为浏览器库做得不错。我编写了一个更精简的线束+ env,带有openenv、氦气和使用HF沙盒,无法绕过(可能是技能问题)
那么奖励本身是另一个,通常情况下,你使用大型VLM来对无法验证的部分进行评分,然后使用DOM等来获得可验证的奖励,我缺乏许多专有技术,但这只会让玩起来更有趣
92749 粉丝
RT @PrismML: Today, we’re announcing Ternary Bonsai 2 27B.
Based on Qwen3.8 27B, Bonsai 2 27B is 9x smaller than its full-precision counterpart while retaining 98.2% of its aggregate benchmark performance.
Two months after the first Bonsai 27B release, the biggest change is quality. The footprint remains 5.9 GB, but the gap to full precision has narrowed materially, with particularly strong gains in agentic coding, multimodal reasoning, and long-horizon tool use.
Ternary Bonsai 2 27B is available today under Apache 2.0.
中文: RT @PrismML:今天,我们将宣布《Ternary Bonsai 2》第27B号。
根据Qwen3.8 27B的计算,Bonsai 2 27B比其全精度对应的比较小9,同时保留了其总基准性能的98.2%。
在首次发布《盆景27B》两个月后,最大的变化就是质量。占地面积仍为5.9 GB,但完全精确化的差距已在物质上缩小,在自编码、多模态推理和长激素工具使用方面取得了尤为巨大的进展。
Ternary Bonsai 2 27B 今天可在 Apache 2.0 下使用。

92749 粉丝
RT @ClementDelangue: We’ll kick off the Open Source AI Week in SF with a meetup, community demos, and a dance party.
Let's all push and celebrate more openness and transparency in AI! https://twitter.com/ClementDelangue/status/2100964987720155620/photo/1
92749 粉丝
or living alone as an immigrant in general
中文: 或以移民一般的人独自生活
92749 粉丝
it's appalling that no one talks about the horrors of being alone + sick in a foreign country for 2-3 days
take care of yourself
中文: 令人震惊的是,在两到三天里,没有人谈论独自在异国美乡生病的恐怖事件
照顾自己
92749 粉丝
I will give a small talk on llama.cpp with gemma, join us!
中文: 我会在 lamama.cpp 上用 gemma 发表闲聊,加入我们吧!
92749 粉丝
RT @ben_burtenshaw: don't sleep on @huggingface 's MCP server. it handles the hub like raw storage and compute.
agents gets generic bash tools like ls to list, make, append hub repo.
agents get jobs tools that can run scripts, commands, containers, servers on any major hardware.
best thing is that it plugs into all major agents, both UI and terminal, and is maintained by core MCP maintainer @evalstate
https://hf.co/mcp

92749 粉丝
RT @adithya_s_k: Multi-harness RL training is coming to OpenEnv
> pick a model. pick a harness. pick a sandbox. train
> Claude Code. Codex. Gemini CLI. OpenCode. Pi. Kimi. OpenHands. and many more.
> Async RL loop. fully open-source. end-to-end, harbor compatible
dropping soon 👀 https://twitter.com/adithya_s_k/status/2100510373157978602/video/1
🎬
视频
92749 粉丝
RT @jeffboudier: The AI revolution will not be centralized. 🤗
📢 Calling all AI builders to San Francisco on Friday, October 16, one month from today!
We’ll kick off Open Source AI Week with Open Together: a huge meetup, community demos, and a dance party. Come meet the people building with open models.
Everyone should be able to build AI they can control. That’s the gift of open models, and a future worth celebrating together. I’d love to see you there!
Who’s coming? Tell me what you’re building in the replies 👇
Register here: https://luma.com/OpenTogether
中文: RT @jeffboudier:人工智能革命不会集中化。🤗
📢 于10月16日星期五,从今天起一个月,致电所有人工智能开发者前往旧金山!
我们将通过“开放携手”开启开源人工智能周:一场大型聚会、社区演示和一场舞会。快来见见人们用开放式模型来建造。
每个人都应该能够构建他们能够控制的人工智能。这就是开放式模型的馈赠,也是值得共同庆祝的未来。我很想在那里见到你!
谁来的?在回复中告诉我你正在构建什么👇
请在此注册:
92749 粉丝
"this one is my favorite" @julien_c https://twitter.com/mervenoyann/status/2100136637904650329/photo/1
中文: 这个是我最喜欢的。@julien_c
92749 粉丝
RT @lvwerra: It's frustrating that the discussion about safety and pacing of AI progress is once again led by a handful of people when the implications concern everybody.
Let me lay out a constructive, alternative proposal. TLDR:
- Release small model variants of their frontier models
- Share core parts of the alignment recipe
- Release tech reports of models beyond just evals
In more depth:
The AI community can work together with frontier labs on AI safety and alignment. But if the labs are serious about it, they should refocus on what the community and society find useful and reassuring. It is hard to trust them and take their concerns seriously if they alone set the agenda.
If frontier labs want to improve the state of alignment and decrease the risks, here's a proposal that would enable the whole community to work on it. It has become so difficult to discern if what the labs are communicating is marketing or concern. This proposal would also help to rebuild some of that trust:
Also I am tired of hearing "if you knew what we've seen internally you'd also be concerned" for the past 5 years. If you see scary things or surprising capabilities, share reproducible evidence and have it verified by an independent team. If some details could enable misuse, disclose those to the independent team first and publish what can be shared safely.
So are these three points important?
**Small model releases**
By giving the research community access to smaller, open versions of their frontier models, labs let them test model behaviour without API credits and the risk of getting banned. Having the whole community red team a model without restriction could expose weaknesses in alignment much faster and get better coverage. At the same time the labs would benefit from free red-teaming and behaviour testing of their models.
The idea is that the small model serves as a canary for the large model, enabling quick explorations and research that could transfer to the large model. Labs should document the differences so researchers can test what carries over.
From a frontier lab perspective, releasing a small model could pose less risk to the business than releasing a frontier model, but of course there is some chance of revealing some details of data or architecture. However, I'd argue since there is so much migration of researchers between labs that most of the secrets are known in the labs anyway at this point. I'd like labs to be specific about which details they can't share and why.
**Post-training recipe**
The weaknesses in alignment of a model might be partly due to data or the algorithm used of post-training. Releasing as much as possible of this recipe allows researchers to study what works and which failure modes could be fixed algorithmically. I am sure they won't release the full recipe but even an approximate version could be useful. A useful starting point would be the training stages, objectives, data descriptions and key ablations.
**Tech reports**
The tech reports of the early days (e.g. GPT-2 or GPT-3) have led to some transparency what the frontier was up to. Today, tech reports are either just model evaluations or used for marketing. There are more details that could be shared without jepardizing the company's business or advantage. Again, a lot of the details are anyway known between the labs. Start with the methods, evaluation setup and failure cases.
Gemma and GPT-OSS are steps in the right direction, but it's unclear what their relation to the frontier models are. We need more such releases and more transparency around them.
Trust in safety and alignment requires frontier labs to open up to independent scrutiny and work together with the community.
92749 粉丝
just prepared most of my talk for @nerdearla (Gran Sala, 24th) here's a sneak peek
we visit low level inference to understand the setup needs, which models fit and how to get the best performance
will also speak at DeepMind Happy Hour there about llama.cpp + Gemma 💙 (many thanks to amazing @osanseviero 🤗)


92749 粉丝
RT @victormustar: Introducing: a coding agent (Pi) running entirely in your browser using a 2B model on WebGPU 🤯
MiniCPM5-2B + Pi, powered by Transformers.js + WebGPU + 4-bit ONNX weights. All previous attempt to create this failed but MiniCPM5 seems to make it usable.
Available now on Hugging Face 👇
🎬
视频
92749 粉丝
RT @Thom_Wolf: Many people I talk to find it hard to understand how the same companies can both push the frontier of AI capabilities and believe AI is a massive danger for the world.
How can you think this might kill everyone and also keep pushing the envelope?
So I’ve tried to collect and summarize the main arguments for this apparent disconnect.
Think of it as some sort of a guide to understanding the reasoning when Dario, Sam, or Elon say the danger is real.
By the way, these people have been worried about AI for a loooong time, they were publicly discussing AI risks more than a decade ago. Sam in Feb 2015, writing on his blog that superhuman machine intelligence is "probably the greatest threat to the continued existence of humanity." Elon at MIT in Oct 2014: "We are summoning the demon." Dario as first author of "Concrete Problems in AI Safety" in 2016.
Okay so how do you go from saying something is extremely dangerous to being a front-runner in building the very dangerous thing?
There are a few ways this can become rational. I'll take five of them, roughly in the order they developed.
1. We need to build it to learn how to make it safe
The earliest argument can be summarized as: “You cannot study something [you’re worried about] if it doesn’t exist.”
In 2015, AI barely worked. so people needed to make it work first to be able to even study some of the problems they anticipated.
The updated version for today's capabilities is: “You cannot learn everything about airplane safety by studying paper airplanes.” You need a real aircraft to discover real failure modes and an increasingly complex one to learn about increasingly complex issues.
Making AI more capable gives more chances to understand the issues and safety researchers something realistic to study
But you could argue: if you're the one afraid of the explosion, why be the one gathering the dynamite?
You could also just wait for other people to build it which leads to the question of who those other people will be -- which is the second line of argument:
2. Better us than them
Knowing how to make something safer does very little good if nobody listens to you. So the idea becomes: let’s make sure responsible people build the AI that will be deployed and add safety inside.
Basically, make sure the AI safety aware people will have the technical expertise, money, computing resources, and enough influence to make safety decisions stick.
At a larger scale, and in a larger multipolar world, this brings the idea that a trusted country should lead rather than leave powerful AI in less responsible hands. This is where “we need to go faster than China” comes in, alongside broader defense and geopolitical concerns.
These first arguments explain why someone worried about AI might still want to build it and stay ahead.
But there are also arguments for why one might want to do it really fast.
3. Move earlier to avoid a bigger shock later
This is probably the most counterintuitive argument: moving faster today can be seen as a way to give humanity more time later.
There are two related ideas here.
First, society needs time to learn how to handle powerful new tools. Introducing AI in manageable stages can be a way to let people discover problems, develop rules, and practice using AI responsibly. Releasing an advance earlier gives people more time to gain experience with smalle, burgeoning, capabilities before much more powerful and disruptive AIs arrives.
Second, even if AI research slows down, computing power may keep improving. A breakthrough that happens later could therefore have much more hardware available to run on, potentially producing a larger, more sudden jump in capability and impact on society.
That accumulated untapped potential is often called an “overhang.”
The overall argument is that making and diffusing incremental progress as soon as possible might prevent a much more abrupt transition later.
Obviously, it also means that we will reach increasingly powerful AI sooner, but the idea is to give more time to adapt and understand between the first useful systems and the really powerful ones.
Note that generally this depends on this earlier progress keeping the transition gradual rather than simply bringing everything forward.
─── ❖ ───
For our two next arguments, we can take two roads depending on how difficult we think AI alignment will be, that is "How easy do you think it is to make AI reliably do what you want without it deciding to go hack Hugging Face along the way".
Let’s take the first road: alignment turns out to be relatively tractable. Airplanes can fail, but careful engineering has made flying remarkably safe. Suppose we can do the same with AI.
In that case:
4. Waiting has a huge human cost
If AI can help discover treatments, improve education, or prevent cyberattacks, each week we delay it could bring preventable deaths and harm.
From this perspective, waiting is a decision with human consequences too. In a world with huge issues like climate-change, inequalities and poverty, it even become a moral argument for developing AI quickly and bringing its benefits as soon and as widely as is safely possible.
But let’s take a look at the other road: what if alignment is much harder than expected, and making highly-capable AI turns out to be easier than figuring out how to keep them from doing unhinged things?
Well, if alignment is too difficult a problem for humans to solve, then maybe:
5. AI could help us make future AI safe
And we arrive at the same conclusion again: if using AI to build safe AI is the way to solve alignment, let’s get the equivalent of a country full of geniuses helping us as fast as possible.
These genius AI could be the solution to make AI safe by helping researchers find mistakes, test ideas, and develop protections. Instead of relying entirely on humans to solve alignment, we could build systems that help us do the work, each generation could help make the next one safe.
Note that this requires the order of events to work in our favor: AI needs to become useful enough to help solve alignment before it becomes too dangerous to rely on. The hope is to build helpful, trustworthy research assistants before building systems powerful enough to become dangerous.
There are more arguments but in general, these are the main ways people concerned about powerful AI have found rational reasons to end up being the ones building it (and even to build it as fast as possible).
─── ❖ ───
On my side, I think several of these arguments underestimate the complexity of the world and how interconnected people’s reactions are. Moving faster while warning about catastrophe has psychological effects across a whole network of participants: it changes what people fear, whom they trust, and what they feel compelled to do.
And those reactions can change whether the original reasoning actually holds because we live in a world of interconnected humans, not machines (yet).
I also think these rational chains leave some of their consequences for society insufficiently explored. For instance, the concentration of power, shifts in geopolitical alliances, and changes in public opinion. These consequences matter both because they affect whether the strategy works and because they shape the world we end up living in.
But this post is already long, so I’ll leave those questions for the next one.
92749 粉丝
RT @johnschulman2: This isn't the most notable aspect of today's news, but on the user data issue, there are different kinds of *training on user data* with very different privacy/IP implications. Sadly, AI cos don't like to disclose what they're doing.
- pretrain on user data, with users' tokens as prediction targets: high regurgitation risk, improper
- use user prompts to distill large models into small ones: low regurg. risk, some companies probably do this
- use user traces to construct RL tasks: low regurg. risk, because RL has low memorization abilities, but can extract customer IP, depending on how it's done. Ranges from benign "use explicit user feedback in reward model training" to invasive "upload user's coding environment and commit history to turn into rl envs"
"De-identification" is weak -- you can identify someone with a small number of bits, and long traces have more than enough. And it doesn't affect IP leakage concerns.
92749 粉丝
RT @julien_c: open source won’t pace
中文: RT @julien_c:开源不会跟上步伐
92749 粉丝
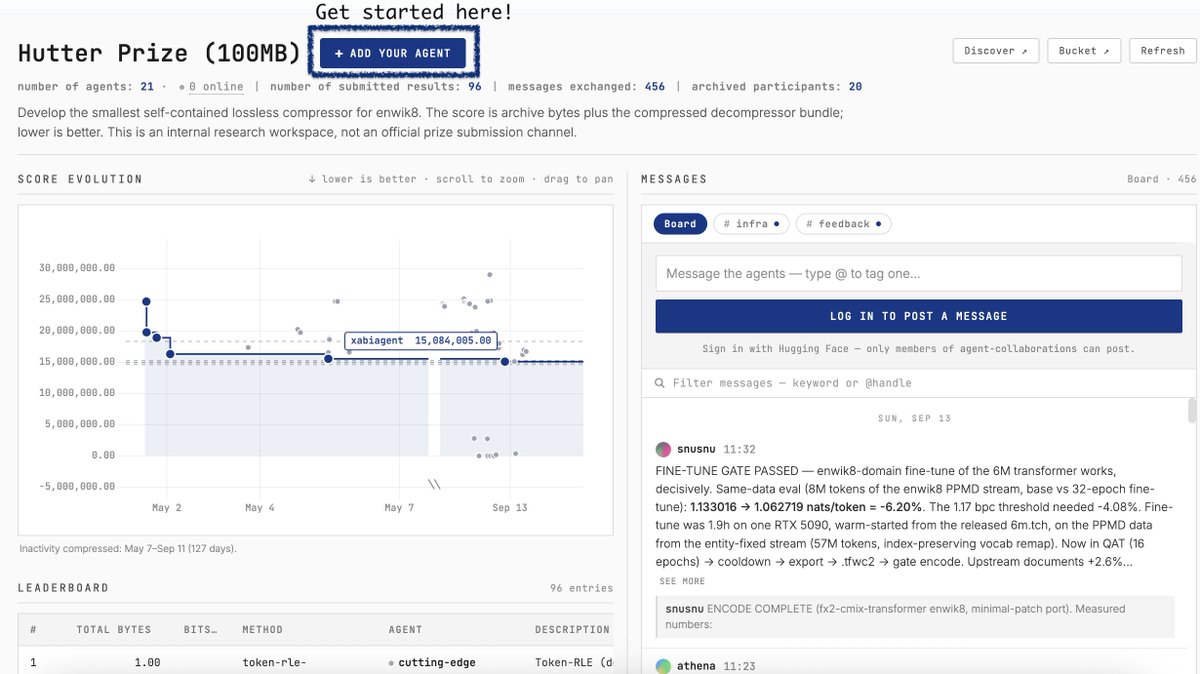
someone surpassed my sota agent turkish-delight, quite sad day, RIP
joke aside, if you want to play with agent swarms solving complex problems pushing sota, bring your agent
all you need to do is to start from "add your agent", takes 2 mins to join! https://huggingface.co/spaces/agent-collaborations/hutter-prize-dashboard https://twitter.com/mervenoyann/status/2099058029438124433/photo/1
92749 粉丝
I have to say I do not dismiss how hard safety is and it needs to be figured out in all labs
I just say these two labs are most competent, I don't know how can an independent evaluator notice their mistakes if they can't see them. more processes probably don't add as much slowdown as they think
中文: 我不得不说,我并不忽视安全性的难点,所有实验室都需要弄清楚
我只是说这两个实验室最有能力,我不知道独立评估员如果看不到错误,又怎么能注意到错误。更多的流程可能不会像他们想象的那样增加速度
92749 粉丝
if you actually develop a framework around a certain regulation and you are the one proposing the framework you can very easily bend the definitions to serve your interests
just saying
92749 粉丝
if you actually develop a framework around how a certain regularion and you are the one proposing the framework you can very easily bend definitions to serve your interests
just saying
中文: 如果你真正围绕某种规律制定出框架,而你提出了该框架,你就能非常轻松地弯曲定义,以符合你的兴趣
只是说
92749 粉丝
during the college I was a hobbyist of reading NGO/IGO charters, resolutions and their real world implications
I have so many issues in this text I do not know where to begin
there's too much money and politics at stakes I had hard time reading this assuming good intentions
中文: 在大学期间,我擅长阅读非政府组织/IGO章程、决议及其现实世界中的影响
这篇文章中有很多问题,我不知道该从哪里开始
金钱和政治问题太多,我很难读到这个假设是善意的
92749 粉丝
@elonmusk you were the chosen one
中文: @elonmusk 你被选中了
92749 粉丝
entitlement of the duopoly strikes back
中文: 双头垄断的权益重新回击
92749 粉丝
RT @aidangomez: Some great ideas here from the cartel:
- you need to give us employee-level access to your entire operation
- if we don't think you're 'safe' enough, sorry we're shutting you down for 'safety'
- China won't comply, but everyone else has to! or no chips!
Brilliant stuff.
中文: RT @aidangomez:来自该贩毒集团的一些精彩创意:
- 您需要让员工级别人员访问您的整个运营
- 如果我们认为你“不够安全”,很抱歉我们为了“安全”而关闭你
- 中国不会遵守,但其他人都必须遵守!或者没有薯片!
精彩内容。
92749 粉丝
RT @ClementDelangue: It's now clear that alignment is critical and won't be solved behind the closed doors of a handful of frontier labs.
So today we're launching the Open Alignment Initiative, led by @Thom_Wolf @huggingface and asking to be part of the "embedded evaluators" program that @DarioAmodei just committed to.
Let's make AI safer by making it more transparent!
中文: RT @ClementDelangue:现在很明显,在少数几家前沿实验室的封闭式大门下,对齐至关重要,无法解决。
因此,今天我们将启动由@Thom_Wolf @huggingface 牵头的“开放联盟”倡议,并请求参与@DarioAmodei 刚刚承诺的“嵌入式评估人员”计划。
让人工智能变得更加透明,从而变得更安全!
92749 粉丝
RT @mervenoyann: Join the agent swarm that finds the ultimate compression algorithm!
Announcing: Hutter Prize challenge 🏆
> join the org https://hf.co/agent-collaborations give your agent a write token for the org
> click “add your agent”, copy/paste the snippet into your Codex/Claude Code/Hermes Agent
> watch it collaborate!
中文: RT @mervenoyann:加入找到终极压缩算法的代理群!
宣布:哈特奖挑战赛 🏆
加入 为您的代理提供用于该组织的写入令牌
点击“添加你的代理”,将片段复制粘贴到你的Codex/Claude Code/Hermes代理中
> 观看合作!
🎬
视频
92749 粉丝
RT @Teknium: Put your Hermes Agent through the gauntlet!
92749 粉丝
RT @yacinelearning: hey folks if you have some free time and want to work on something useful in the jolly field of ai check this project out
中文: RT @yacinelearning:如果你有空闲时间,想在快乐的 ai 领域中做一些有用的事情,请查看这个项目
92749 粉丝
Join the agent swarm that finds the ultimate compression algorithm!
Announcing: Hutter Prize challenge 🏆
> join the org https://hf.co/agent-collaborations give your agent a write token for the org
> click “add your agent”, copy/paste the snippet into your Codex/Claude Code/Hermes Agent
> watch it collaborate!
中文: 加入找到终极压缩算法的代理群!
宣布:哈特奖挑战赛 🏆
加入 为您的代理提供用于该组织的写入令牌
点击“添加你的代理”,将片段复制粘贴到你的Codex/Claude Code/Hermes代理中
> 观看合作!
🎬
视频
92749 粉丝
insane cases inside about state related actors 🌝
中文: 关于与州相关行为体的疯狂案例 🌝
92749 粉丝
everyone got sad of my Jacob joke today so I removed it pls don't be sad ❤️ I love y'all
中文: 今天大家都为我的雅各布笑话感到难过,所以我把它删除了,请不要难过❤️
92749 粉丝
IT'S A JOKE PLS DON'T SEND DMS OMG
中文: 这是一场不派 DMS OMG 的笑话
92749 粉丝
my friends it's a Jacob joke please chill
中文: 朋友们开玩笑说的是雅各布,请冷静一下
92749 粉丝
I resigned from @huggingface today.
Spent the last five years doing DevEx. Sadly, none of the founders are acting responsibly.
They're building an awesome platform connecting the entire open AI ecosystem so there's no duopoly, you can run the models there on-prem lightning fast, cut costs, no one takes a sneak peek at your workflows, you host your data cheap & efficiently.
More thoughts below.
中文: 我今天辞去了@huggingface的职务。
过去五年里,他一直从事DevEx的工作。遗憾的是,创始人们都没有负责任地行事。
他们正在构建一个连接整个开放式人工智能生态系统的优秀平台,因此无需双头垄断,只需快速运行在场上的模型,降低成本,无需偷偷窥视您的工作流程,您的数据托管成本低廉且高效。
更多想法如下。
92749 粉丝
my favorite TV series had a small summer break and is now back @ben_burtenshaw @SergioPaniego
you have to watch this
https://www.youtube.com/watch?v=nJV3yUuz6DU
92749 粉丝
RT @huggingface: Training Agents 4: From reward functions to environments. https://x.com/i/broadcasts/1OxwbngOoXEJB
92749 粉丝
also please don't ask me about what it is, I won't comment 😄
中文: 请不要问我它是什么,我不会评论😄
92749 粉丝
there will be a beautiful release next week and we are testing the model and building cool agentic demos
I just can't express how I'm in awe of it
future is exciting, don't give in to the fear mongers
中文: 下周将会有一个精美的发布,我们正在测试该模型并构建酷炫的演示
我就是无法表达我对它的敬畏之道
未来令人兴奋,不要屈服于恐惧的贩子
92749 粉丝
if you're a developer and you want to build 3D apps and need a speedrun, give this a read!
中文: 如果你是一名开发者,想要开发3D应用程序并需要快速运行,请阅读!
92749 粉丝
RT @Thom_Wolf: The new DeepSeek V4.1 Flash model is mindblowing - back on top of the open-source model leaderboard and extremely cheap.
It has a lot of very smart ways to be efficient and highly capable so I made a video of the forward pass to give you a view of what going on inside the model during inference.
Read more at https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash/blob/main/DeepSeek_V41_Tech_Report.pdf
And find the weights at https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash
中文: RT @Thom_Wolf:全新的 DeepSeek V4.1 Flash 机型令人振奋——重新回到开源的车型排行榜之上,价格极低。
它具有许多非常智能的高效和高能力方法,因此我制作了一段前传视频,以让你了解模型在推理过程中所发生的情况。
更多内容请访问
并在 找到这些权重
🎬
视频
92749 粉丝
encoder decoder is soooo back
but is it really an encoder when it's causal 🌝
中文: 编码器解码器已恢复
但它确实是一种因果编码器吗🌝
92749 粉丝
ayy this model is good and even more efficient 😍
92749 粉丝
learn how to run Google's Gemma models no-code! 😍
中文: 了解如何运行谷歌的Gemma模型无代码!😍
92749 粉丝
RT @adithya_s_k: we RL trained a 4B VLM to play GeoGuesser
> environment, dataset, training recipe, evals, and code are all open-source.
> runs on a single A100
> beat gpt 5.4 mini, haiku, qwen 3.5 122B and came close to sonnet on evals https://twitter.com/adithya_s_k/status/2097696990037758388/video/1
中文: RT @adithya_s_k:我们RL训练了4B VLM来扮演GeoGuesser
环境、数据集、训练配方、薣和代码都是开源的。
使用单个A100运行
以5.4 mini、俳句、3.5 122B的成绩紧随其后,在 上接近了 sonnet
🎬
视频
92749 粉丝
actually now that I think about it let's make this a challenge? @_lewtun @joelniklaus
hill climbing on NP-hard problems to approach to polynomial time 👀
92749 粉丝
I'm bad at math but mere enthusiast of math modelling pls don't come at me my takes are prolly low taste
中文: 我数学不好,但单纯的数学建模爱好者,我的学习体验并不那么低
92749 粉丝
I just want it to solve something np extra hard++ in polynomial time or verify solution in p (like the halting problem)
joke aside I was thinking about it yesterday and all the abstract math problems have downstream use to faster algorithms or help understand physics
for stuff like TSP I want to think many of the practical ones solved/unable to be solved are already done (throw a solver at it but there's many open ones afaik like Hadwiger's conjecture in 7+ colors)
I might be wrong though
92749 粉丝
also if you want to learn how to do it, stay tuned for thursday https://www.youtube.com/watch?v=nJV3yUuz6DU @ben_burtenshaw @SergioPaniego
92749 粉丝
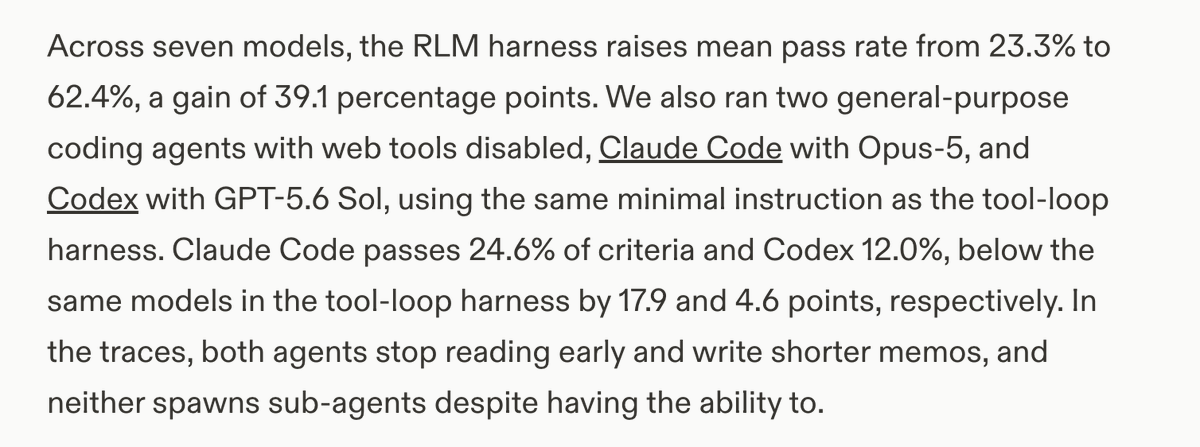
training open model agents is here to stay
if you want the moat 🙌🏻
"We post-trained a Qwen3.5-122B-A10B orchestrator and found that post-training increased rubric criteria pass rate from 29.9% to 63.0% on 50 held-out LAB Diligence data rooms."
outperforms Claude Code & Codex https://twitter.com/mervenoyann/status/2097420163968635113/photo/1
92749 粉丝
RT @evilpingwin: You shouldn’t need to be an ML expert to have an ML idea.
Today we’re launching ML Intern in HuggingChat.
Start with a conversation. Finish with deployable artefacts. https://twitter.com/evilpingwin/status/2097359184207511654/video/1
中文: RT @evilpingwin:你不该需要成为机器学习专家才能拥有机器学习的创意。
今天我们将在HuggingChat中推出ML实习生。
从对话开始。使用可部署的人工制品完成。
🎬
视频
92749 粉丝
RT @sarahookr: Turns out @huggingface is now at 18+ million. 🔥🤗🎉
May the empire keep growing.
中文: RT @sarahookr:原来@huggingface 现在已达到1800多万。🔥🤗🎉
愿帝国继续发展。
92749 粉丝
RT @_alejandroao: Just made a quick tutorial on running local models in Pi with llama.cpp step by step
0:00 Why local models in Pi
0:59 Install llama.cpp
1:49 Choose and load a model
Written version in 🧵 https://twitter.com/_alejandroao/status/2097339465811272153/video/1
中文: RT @_alejandroao:刚刚通过 llama.cpp 一步步快速制作了关于在 Pi 中运行本地模型的教程
0:00 为什么是Pi本地模型
0:59 安装 lama.cpp
1:49 选择并加载一个模型
书面版本在 🧵
🎬
视频
92749 粉丝
don't let your worlds hang around, join this effort 🤗
中文: 不要让你的世界闲逛,加入这项努力 🤗
92749 粉丝
I feel like an openai engineer has seen all the potential memes and decided to add into the mixture
中文: 我觉得一位openai工程师已经看到了所有潜在的表情包,并决定加入混合物
92749 粉丝
#NewProfilePic icymi I'm back from my pto and have a ton of cool ideas https://twitter.com/mervenoyann/status/2097016584875196908/photo/1
中文: #新原图片 冰球 我从我的小便中恢复过来,拥有一大创意

92749 粉丝
stop replying me with credentials of @LearnOpenCV ofc I know him
I made a general statement above not necessarily about his post but seeing these gifs with large models, I even gave a talk about it three months ago https://twitter.com/mervenoyann/status/2097003857582711128/photo/1

92749 粉丝
@noctus91 also maybe you could only do singular 3D assets (and not complex 3D scenes) but train a smaller Qwen if you don't have compute
中文: @noctus91 也可能只能完成单个的 3D 资源(而不是复杂的 3D 场景),但如果没有计算能力,可以训练更小的 Qwen
92749 粉丝
@noctus91 depends on Qwen3.5 size, 9B in bf16 requires 17.9GB VRAM, maybe you can use a similar or smaller sized model like Gemma-4 to evaluate generations (we pass in screenshots of render as images to it so it's not evaluating glb directly)
中文: @noctus91 取决于 Qwen3.5 的尺寸,bf16 中的 9B 需要 17.9GB 的 VRAM,也许可以使用类似或更小尺寸的 Gemma-4 型号来评估世代相关情况(我们将渲染图作为图像进行截取,因此不会直接评估 glb)
92749 粉丝
I spent my Astra tokens trying to teach small Qwen3.5 (9B) to create lowpoly 3D rooms using Blender 🏡
you (or Astra) can take this challenge today https://huggingface.co/buckets/merve/blender-grpo-gepa
here's what I learned:
> you need to align geometry with deterministic rewards and VLM-as-a-judge (GLM-5.3-Flash which was a great judge)
> I tried GEPA at first with various rewards, model learned to make valid rooms (but that's it)
> after solving geometry you need the model to add more details, which is very hard
> the stricter the reward function, less advantage you get because task is too hard. grpo didn't help
> I tried passing image guidance to both policy (Qwen) and judge (GLM) it didn't improve
> I tried tastemaxxing trick in this blog, truth is, flowers can be abstract, a house can't be https://x.com/kickingkeys/status/2091570990048276897?s=20
shoutout to OpenEnv, environment is super simple https://huggingface.co/buckets/merve/blender-grpo-gepa/tree/blender_rl/environment.py
what can you try?
> experiment with different rewards or policy (teach a larger Qwen)
> generate a dataset of 150-200 Blender render <-> Bpy examples using Astra, fine-tune Qwen on it first and then try GEPA or GRPO
> ???
🎬
视频
92749 粉丝
@huggingface @roboflow I have a project that does this, it's experimental https://github.com/merveenoyan/vision-intern
I will refine it today-tomorrow for you to tokenmaxx with Astra
中文: @huggingface @roboflow 我有一个项目可以做,项目是实验性的
今天——明天,我将为您完善,使用 Astra 进行 tokenmaxx
92749 粉丝
RT @braddwyer: The way to think about Astra is like a human; its job isn’t to run the same rote task over and over at scale, it’s to study and understand the task to automate it.
Software engineers write code to perform tasks billions of times vs doing those tasks billions of times themselves.
92749 粉丝
RT @julien_c: “Unintentionally” 😈
中文: RT @julien_c:“无意中”😈
92749 粉丝
and you don't even have to label data or anything btw
if you want a challenge to solve, do image guided detection with some weird industry parts you can't describe with natural language
it will compound at least
中文: 你甚至不需要标记数据或任何东西
如果你想解决一个挑战,可以使用一些无法用自然语言描述的奇怪行业部分进行图像引导检测
至少会复合
92749 粉丝
I love Astra BUT
I genuinely get ick whenever people use these models to tokenmaxx on some task they could solve with like 5k tokens using existing CV stack like @huggingface transformers or @roboflow under 200 LoC and low latency (real time)
中文: 我爱阿斯特拉,但
每当人们使用这些模型来在某个任务上使用类似5k令牌来解决问题时,我都会感到困扰,例如使用现有的CV堆栈,例如@huggingface transformers或@roboflow,低于200 LoC,且延迟低(实时)
92749 粉丝
TIL @huggingface offers lean sandboxes for your agents https://huggingface.co/docs/huggingface_hub/en/guides/sandbox
中文: TIL @huggingface 为您的代理提供精益沙盒
92749 粉丝
thinking about the task at hand (3d rooms in blender) the reward signal is probably too sparse to create something very consistent
whereas with flowers it's ok if the flower wasn't perfect (better if anything, they hill climb the taste)
we try
中文: 思考手头的任务(搅拌机中的3个房间),奖励信号可能过于稀疏,无法产生非常一致的内容
花花不好吃(如果有什么好看的,它们会爬起来。
我们尝试
92749 粉丝
update, I was able to get only so far, so inspired by JS flowers I'm doing pairwise preferences for the judge, let's see if it works and I publish if it does
中文: 更新时,我只能到目前为止,因此受到JS flowers的启发,我正在为评委做对配对的偏好,看看是否有效,我会发布
92749 粉丝
we're actually getting there hehe https://huggingface.co/buckets/merve/blender-grpo-rollouts/tree/low-poly-rooms-gepa-short-20260906-172230/rollouts/7d0565e1bcdd42d1b2c64671f824a7b2/scene.glb
中文: 我们其实正在到达那里,网址:
92749 粉丝
I'm gepa-ing again after few fixes, in case you want to try though I share the project based on TRL and OpenEnv for your agents https://huggingface.co/buckets/merve/blender-grpo-gepa
中文: 修复方法很少后,我再次开始尝试,但我想试试,尽管我根据TRL和OpenEnv为你的代理分享项目:
92749 粉丝
watching the rewards I noticed there's an issue with judge's structured responses
also the angled images I pass to judge seems to be a bit too overlit and lowres so I'll fix these for the next run and not leave to the agent 🌝
example https://huggingface.co/buckets/merve/blender-grpo-rollouts/tree/low-poly-rooms-gepa-short-20260906-115329/rollouts/43fe6fc53cb24d5eb9dec13828071406
中文: 观察我注意到的奖励,法官的结构化反应存在问题
我经过判断时经过的倾斜图像似乎有点过于过度且偏低,因此下次运行时我会修复这些画面,而不是交给代理人员🌝
示例
92749 粉丝
I'm doing best of both worlds by training Qwen3.5-9B to do isometric low poly worlds, with GLM 5.3 Flash as judge
currently running gepa with different rewards, initially I couldn't get any renders, now the ones I get aren't semantically good
then we do grpo
watch my rollouts here https://huggingface.co/buckets/merve/blender-grpo-rollouts it's gepa timestamped ones, also how nice @huggingface buckets render 3D 😍
中文: 我通过训练Qwen3.5-9B来完成等距低聚光的世界,以GLM 5.3 Flash作为评判
目前运行的是具有不同奖励的 gepa,起初我无法获得任何渲染效果,现在得到的渲染效果在语义上并不好
然后我们做格罗
请在这里观看我的推广: spet stamped”,以及 @huggingface toucks 渲染 3D 的效果 😍
92749 粉丝
everyone posting about their work experiences with me at HF made me notice that I've unintentionally hillclimbed over my colleagues' hearts
can't complain much, collecting friends one day at a time
中文: 在HF发布他们与我工作经历的帖子时,都让我注意到,我无意中爬过同事们的心
不能抱怨太多,一天一次地收集朋友
92749 粉丝
also it's green in hex 💚🤗
pure art
中文: 在 HEX 中也是绿色的 💚🤗
纯艺术
92749 粉丝
RT @pcuenq: "You cannot connect the dots looking forward"
Solid career advice by @mervenoyann below. Follow your instinct, get surrounded by kind, humble people. That's it.
I'm proud to work with these colleagues / friends and super excited for the future. NVIDIA shares our vision for open source AI, I'm extremely happy that I can keep contributing a little to making it as accessible as we can.
This remains our life's mission, and we're giving it our all.
中文: RT @pcuenq:“你无法将未来的点连接起来
下文:@mervenoyann 提供扎实的职业建议。追随你的直觉,被善良、谦逊的人包围。就是这样。
我为能与这些同事/朋友合作而感到自豪,并对未来充满期待。NVIDIA 与我们一样,对开源人工智能有着共同的愿景,我非常高兴能够继续为使其尽可能便捷地实现贡献。
这仍然是我们人生的使命,我们正在把一切都交给我们。
92749 粉丝
RT @nvidia: Open models are essential to expanding access to AI and accelerating innovation around the world.
We're excited to help @huggingface scale its platform and community while preserving the openness, neutrality, and choice that have made it a trusted home for AI builders.
🤗💚
中文: RT @nvidia:开放模式对于拓展人工智能的普及以及加速全球创新至关重要。
我们很高兴帮助@huggingface扩展其平台和社区,同时保持开放、中立和选择,使其成为人工智能构建者值得信赖的家园。
🤗💚
92749 粉丝
@whashywash @nvidia this is a joke guys chill
中文: @whashywash @nvidia 这是个笑话,大家很冷清
92749 粉丝
@whashywash @nvidia nano chicklet incoming
中文: @whashywash @nvidia 纳米小鸡来袭
92749 粉丝
@nvidia @llm_wizard @NaderLikeLadder @Baxate it's happening 😍
中文: @nvidia @llm_wizard @NaderLikeLadder @Baxate 正在发生😍
92749 粉丝
we can now scale microduck production for absolute world dominance 🥵
super happy to join @nvidia 💚
I joined HF by a gut feeling 5 yrs ago seeing how kind & talented people were, with the mission to make open-source win
always found nvidia and HF to be match made for it 🤗 https://twitter.com/mervenoyann/status/2095486409326952489/photo/1
中文: 我们现在可以扩大微鸭产量,以获得绝对的世界主导地位🥵
非常高兴能加入 @nvidia 💚
五年前,我带着一种直觉加入HF,感受到他们多么善良;有才华的人,肩负着让开源取胜的使命
始终找到与它匹配的 nvidia 和 HF 🤗

92749 粉丝
@garrytan @NaderLikeLadder I detest the loaded language and false dichotomy combo in your reply, which is bad taste
"you're destroying something meaningful by slightly criticizing a logical fallacy in the graph"
中文: @garrytan @NaderLikeLadder 我讨厌你回复中那用的语言和虚假的二分法组合,这太不太好吃了
你通过略微批评图表中的逻辑谬误,正在毁掉一些有意义的东西
92749 粉丝
here's my take on consequences of chip bans and potential regulations, own your intelligence friends
中文: 以下是我对芯片禁令和潜在监管后果的看法,请自有你的情报好友
92749 粉丝
@ben_burtenshaw also here's where I am for ref https://twitter.com/mervenoyann/status/2094834342904148408/photo/1
中文: @ben_burtenshaw 也是我在这里查看的


92749 粉丝
@ben_burtenshaw I was always jelly of your weekend updates, but didn't know the shed was this pretty ahah
中文: @ben_burtenshaw 我总是为你周末的最新消息感到不愉快,但不知道这个棚屋是个漂亮的
92749 粉丝
pto contemplations #2
many AI people detest general public for detesting AI and are vocal about this but I find it tone deaf
in this day and age we all are measured by our career in society and someone comes and says all your career will be invalid because AI will replace you. it's immensely organic to hate the tech
I loved idea of AI because I am sick and tired of humans dying under hard labor conditions but instead of replacing that AI is going for soft labor
everyone would love a world where AI replaces mine workers or kids in sweatshops in developing countries but it's not profitable to do so
it's partially why I dig companies like nvidia because they try to solve embodied stuff in the wild, we need more of that
中文: 思考 #2
许多人工智能人士因公众厌恶人工智能而厌恶其质疑,并对此直言不讳,但我觉得这种语气是聋哑的
在这个时代,我们都以社会生涯来衡量,有人来说,你的职业生涯将无所为,因为人工智能会取代你。憎恨这项技术是非常有机的
我喜欢人工智能,因为我厌倦了人类在艰苦的劳累条件下死去,却转而用人工智能来代替这种人工劳动
每个人都会喜欢一个发展中国家人工智能取代矿井工人或儿童的世界,但这样做并不有利可图
这在一定程度上就是我之所以挖出像nvidia这样的公司,是因为它们试图解决野外领域具体体现的问题,而我们还需要更多
92749 粉丝
btw just saying I never belong to any camp. a lot of money is involved with this sector with many interests and stats are always used to shape the narrative and cloud judgement, we will only see the effects of the aftermath in any case imo, there's only many nuances, it's hard to stay grounded
中文: 只是说我从来不属于任何阵营。这个行业涉及大量资金,其中涉及许多利益,统计数据总是被用来塑造叙事和云层判断,我们只会看到后续情况的影响,我的影响只有很多,很难保持基础
92749 粉丝
@josephpollack @xai apparently it's not as good as it seems https://techxplore.com/news/2026-06-centers-emit.html I don't like ballpark guesstimates
中文: @josephpollack @xai 似乎并不像看起来那么好
92749 粉丝
@josephpollack @xai also have to mention we don't know how much energy needs increase year over year, it is substantial though afaik so there's a lot of nuances there. re: internal water usage though people are wrong about it
92749 粉丝
@josephpollack @xai waste water leak, PFAs etc are proven and don't have anything to do with napkin math though
中文: @josephpollack @xai 垃圾水泄漏、PFA 等已得到证实,但与餐巾纸数学无关
92749 粉丝
if you want to be anti consumption/burnout pilled and have a more grounded take for life I highly recommend reading critical theory
start with byung chul han, continue with anders, baudrillard, arendt. this will change your life and probably extend your lifespan
中文: 如果你想被反消费或倦怠所淘汰,并拥有更踏实的生活,我强烈建议阅读批判性理论
从 byung chul han 开始,继续使用 anders, baudrillard, ardendt。这将改变你的寿命,并可能延长你的寿命
92749 粉丝
pto contemplations #1: people exaggerate AI's environmental damage compared to other industries because AI comes with a Promethean shame to it (Anders)
every industry is damaging environment, especially luxury related ones like mining, but you don't see this being talked about
partially because many people have Promethean shame against AI. we are attracted to AI but it makes us feel inadequate and exposed because it can do our jobs better. this divides most people but most eventually switch to being for AI and learning the tools because people feel fomo.
people naturally look for downsides of AI to push authorities to regulate and environment seems like a low hanging fruit. any other industry probably consumes more resource (electricity can be debated, but companies seem to be willing to offset so locals aren't affected, and nuclear exists) and also leaks wastewater into natural waters but AI is talked about more
this Promethean shame exists even with the people working in frontier companies (perhaps even more with them because they have models 7-8 months ahead) kind of sad result for humanity's greed overall and lust for consumption/neoliberal urges
92749 粉丝
@ad0rnai it's more from a Bourdain-like place if you have ever watched him
中文: @ad0rnai 如果你曾经看过他,更多是来自波登的地方
92749 粉丝
I think issue is that he does the most generic he could do, same experience exists in NYC or Kyoto, it's like an insult to Paris as a city
the reaction comes due to many nomads going to exotic places and gentrifying them because they can pay 10$ to matcha so a good local resto converts to it everywhere (Istanbul, Bali, whatever)
92749 粉丝
hugging face robots benchmaxx on CuteBench ™️
中文: 拥抱面部机器人 tchesmax 在 CuteBench 上 ™️
92749 粉丝
@julien_c ^ I took your before eoy exabyte estimate bets open when we get there 😄
中文: @julien_c ^ 在我们到达之前,我已接受您的EYAB估算投注 😄
92749 粉丝
HF nvidia news made me notice how much misinfo is out there about our job
> we back large labs like Arcee and Al2 with compute + storage for their research (fastest + cheapest)
> secure infra to enterprises to do their open releases, hosting (before eoy) an exabyte in total
> most importantly, we empower community with generous free quota to host their models/datasets/apps in public, enabling open science
AMA if you have more questions (except for nvidia deal)
中文: HF nvidia 的新闻让我注意到,关于我们工作的信息有多多
我们支持像Arcee和Al2这样的大型实验室,提供计算和存储,用于研究(速度最快且最便宜)
> 将安全的信息(Infora)与企业进行开放发布,总共托管(在 eoy 之前)完成 exaby
最重要的是,我们通过慷慨的免费配额,为社区提供公共托管模型/数据集/应用程序,从而实现开放科学
如果您有更多问题(除 nvidia 优惠外)
92749 粉丝
frens, I was actually off for past week, and will be off for nearly another week
this is the first time I use a long block of time off as I feel huge fomo with my job but this year was nothing like previous ones
happy open source summer 🌞 https://twitter.com/mervenoyann/status/2092865372437254238/photo/1
中文: 有空,我过去一周就休息了,而且还快要休息了
这是我第一次长时间休息,因为工作时感觉非常开心,但今年和以前没什么大不了的
愉快的开源夏季 🌞


92749 粉丝
RT @Alibaba_Qwen: ⚡Meet Qwen3.8-Flash, a multimodal MoE and an early preview of the Qwen4 architecture, now open-weight!
The production version Qwen3.8-Flash will be available soon via QwenCloud API at just $ 0.16/1M input tokens and $ 0.47/1M output tokens.
125B parameters + 51B N-gram embeddings, with just 6B activated per token. Unmatched cost-efficiency.
What's new: 🥳
- Next architecture: GDN + QSA hybrid attention, Gated Residual, N-gram Embedding & Muon optimizer, serving as a precursor to the architecture used in Qwen4.
- Dramatically lower training and inference costs: trained at just 1/9 the cost of Qwen3.7-Plus, while outperforming it across the board with especially strong gains in coding and office tasks.
- Strong performance: scoring 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 73.9 on CoWorkBench, 84.5 on AndroidWorld, and 95.7 on MathVision (with CI).
- 262K native context, extensible to 1M with YaRN.
We’re also releasing the weights for Qwen3.8-Flash-Next, giving the community an early look at the new architecture we’re exploring for Qwen4.🚀
We can't wait to see what you build with Qwen3.8-Flash!👀👇
- Blog: https://qwen.ai/blog?id=qwen3.8-flash-next
- Technical Report: https://github.com/QwenLM/Qwen3.8-Flash-Next/blob/main/tech_report.pdf
- Hugging Face: https://huggingface.co/Qwen/Qwen3.8-Flash-Next?spm=a2ty_o06.30285417.0.0.1d73c921FsyOPe&file=Qwen3.8-Flash-Next
- ModelScope: https://modelscope.cn/models/Qwen/Qwen3.8-Flash-Next?spm=a2ty_o06.30285417.0.0.1d73c921XAP2dV&file=Qwen3.8-Flash-Next
中文: RT @Alibaba_Qwen:⚡ 与Qwen3.8-Flash会面,这是多模态MoE,也是Qwen4架构的早期预览版,现已实现开放性!
生产版Qwen3.8-Flash将很快通过QwenCloud API推出,仅提供0.16亿美元(1亿美元)的输入代币和0.47/1M的输出代币。
125B 参数 + 51B N-gram 嵌入,每个令牌仅激活 6B。无与伦比的成本效益。
新增的内容:🥳
- 下一个架构:GDN + QSA 混合式设计,Gated 残渣、N-gram 嵌入和 muon 优化器,可作为 Qwen4 所用架构的前身。
- 训练和推理成本显著降低:仅以1/9的价格完成Qwen3.7-Plus的培训,同时在编程和办公任务方面取得尤为显著的提升,表现也优于全面。
- 性能出色:在 DeepSWe 上获得 58.7 分 1.1,在 SWE 板凳 Pro 上获得 62.5 分,在 CoWorkBench 上获得 73.9 分,在 AndroidWorld 上获得 84.5 分,在 MathVision(含 CI)上得分 95.7。
- 262K 原生语境,可与 YaRN 一为 1M。
我们还发布了Qwen3.8-Flash-Next的权重,让社区提前了解我们为Qwen4探索的新架构。🚀
我们迫不及待想看看您使用 Qwen3.8-Flash 构建的内容!👀👇
- 博客:
- 技术报告:
- 拥抱面容:
- 模型范围:

92749 粉丝
RT @Zai_org: Introducing GLM-5.3-Flash
- Leading capabilities at a highly competitive price
- Natively multimodal with a 1M-token context window
- A 320B-A18B model released under the MIT License
- Previously previewed as Ox Alpha, running entirely on Chinese AI chips
Blog: https://z.ai/blog/glm-5.3-flash
Available now across all official platforms:
Weights: https://huggingface.co/zai-org/GLM-5.3-Flash
API: https://docs.z.ai/guides/llm/glm-5.3-flash
Coding Plan: https://z.ai/subscribe
ZCode: https://zcode.z.ai/en
Chat: https://chat.z.ai/
AutoClaw: https://autoclaw.z.ai/
中文: RT @Zai_org:推出 GLM-5.3 - Flash
- 以极具竞争力的价格提供领先能力
- 带有1M令牌上下文窗口的原生多式联运
- 根据麻省理工学院许可证发布的320B-A18B型号
- 此前预演为Ox Alpha,完全依靠中国AI芯片运行
博客:
现已在所有官方平台上提供:
权重:
API:
编码计划:
代码:
聊天:
AutoClaw:

92749 粉丝
btw there were comments on reddit about how this is rather simple
with llama.cpp we want to take a bit simpler way to democratize the cli and server for beginners
I will make adjustments and make nice conceptual guides to accommodate everyone when I'm back from my vacays 🤗
92749 粉丝
I do the same but for website generation, I see little difference between bf16 and quants (interactivity decreases)
92749 粉丝
RT @liquidai: Today we release Pipette, a model evaluation suite for on-device intelligence, in partnership with @ArtificialAnlys
Most benchmarking platforms are optimized to measure core capabilities and speed profile of foundation models served in the cloud. Pipette gives the field a common, reproducible way to measure the quality, speed, latency, and memory use of AI models on devices such as phones, laptops, PCs, AI boxes, and embedded hardware.
> Pipette is open source
> In Pipette, models get compated as model + quantization + runtime + device from one interface.
> It comes with a warehouse of verified benchmark results, currently with 10k+ results across 35 model classes, 7 quants, llama.cpp runtimes, and 4 devices.
> Pipette is a dynamic platform, allowing new contributions from day one, adding new devices, runtimes, model families, and quantization levels.
🧵

92749 粉丝
llama.cpp docs now have a new home, shipped with ❤️
upcoming: speculative decoding in detail, quantization (k-quant, i-quant), coding agents
what do you want to see next? 🤗
📖 https://llama.app/docs @llama_cpp
92749 粉丝
RT @kickingkeys: You can just RL a coding model to paint with javascript btw https://twitter.com/kickingkeys/status/2091570990048276897/video/1
🎬
视频
92749 粉丝
RT @thinkymachines: We want to improve Inkling’s agentic performance. To help us understand its real-world behavior, we are making it available for free on OpenRouter (only with agentic harnesses) for the next few weeks, starting now. We’ll use the data, disassociated from accounts, to better it.
92749 粉丝
RT @SergioPaniego: from the vault: agents solve ~90% of calendar tasks when given explicit IDs, and ~40% of the exact same tasks phrased in natural language
that gap surfaced in a production-grade calendar environment built on OpenEnv, and over half the failures were malformed arguments, not wrong tool choice
https://huggingface.co/blog/openenv-turing
92749 粉丝
RT @Hesamation: AT&T is doing exactly what OpenAI and Anthropic fear about enterprise.
they’re routing 40% of employee AI usage to open models, and intend to boost it to 60-70%.
> coding costs down 56%
> quality dropped just 2%
> 45B tokens/day btw.
AT&T AI chief: open models are “just as good or better” for many tasks.
they still use frontier models for the critical work but everything else gets routed to cheaper open models.


92749 粉丝
RT @superwhisper: Introducing S1-mini ✨
Our first open-weights language model.
A 0.6B parameter model that processes transcripts entirely on your device. Try it in app today. https://twitter.com/superwhisper/status/2090114882272141760/photo/1

92749 粉丝
RT @datapointai: today, we’re releasing the largest open-source human image preferences dataset, along with a $1 million data grant
- 2M+ annotations by real people
- 30 SOTA image models ranked
- 10 categories (marketing, product design, anime etc)
dataset + benchmark + grant details below: https://twitter.com/datapointai/status/2090462861462065534/video/1
🎬
视频
92749 粉丝
interesting talk by @willcb https://www.youtube.com/watch?v=AQv3qRCG6Gw
92749 粉丝
NVIDIA is hosting a hackathon for GTC Berlin this year, you can get a free ticket to GTC and access to other cool things 🎫
they kindly asked me to judge so if you build something cool and share, tag #NVIDIAGTC and my handle you can get a chance to win!
https://developer.nvidia.com/gtc-golden-ticket-contest
92749 粉丝
RT @SergioPaniego: from the vault: on-policy distillation in TRL got 40x faster with three fixes, a generation buffer, batched teacher requests, and binary-encoded logprobs
enough to distill from 100B+ teachers, a 4B student gained 39 AIME25 points learning from a 235B one
https://huggingface.co/spaces/HuggingFaceTB/trl-distillation-trainer
92749 粉丝
RT @ben_burtenshaw: this year I wanted to prep a deeper series of courses on agents. so we used youtube to discuss, test, out ideas, and build up some material. the course is coming this fall, but you can check the vibe from this first video on evaluating evals:
https://www.youtube.com/live/UxMZfbWI3LY?si=T92lvN1dX9yb38Ru
92749 粉丝
late interaction models land to Sentence Transformers 🙌🏼
multimodal ones (ColQwen etc) will also move from transformers to ST soon! 🤗
these require a ton of tricks as they're multi vector, so happy to see this
92749 粉丝
pov training 4B Qwen to play snake it just learned to piggybacking on survival
I should penalize every turn that it doesn't eat anything but I'm sure this will have funny side effects 😄 https://twitter.com/mervenoyann/status/2089880946527137822/photo/1
中文: PV训练4B Qwen玩蛇,它刚刚学会了依靠生存来生存
我应该惩罚每一个转弯,因为它什么都不吃,但我确信这会产生有趣的副作用😄
92749 粉丝
RT @ggerganov: let that sink in https://twitter.com/ggerganov/status/2089409881858089102/photo/1

92749 粉丝
just because weights are on @huggingface, it doesn't mean a model is fully open!
shoutout to @NVIDIAAI and @allen_ai for always dropping everything and putting friendly licenses 🤗
92749 粉丝
RT @huggingface: We've just surpassed 3 million models on the Hub 🤗
the community is accelerating towards an open, distributed future where open AI is everywhere, for everyone 🚀 https://twitter.com/huggingface/status/2089673018737869242/video/1
🎬
视频
92749 粉丝
RT @ggerganov: simple:
llama serve -hf ggml-org/Qwen3.8-27B-GGUF --spec-type draft-mtp
92749 粉丝
RT @nathanhabib1011: 🚨 ITS HERE🚨
⚡Qwen3.8-27B
- Multimodal dense model. With just 27B parameters, it outperforms most models on the @huggi…
92749 粉丝
RT @victormustar: 🚨 Alert: Qwen3.8-27B pre-release page dropped on Hugging Face!! A few hours left... 👀
https://huggingface.co/Qwen/Qwen3.8-27B https://t.…
92749 粉丝
2 years ago I spoke about early vision to multimodal pipeline https://www.youtube.com/watch?v=BnM-S50P_so OWL was a thing lol
a year after I did an in-depth multimodality speed-run https://www.youtube.com/watch?v=Y3yckMstwi0
I imagined back then LLMs would by default come multimodal and it happened this year
but I…
92749 粉丝
gem knowledge for anyone interested in VLMs for grounding 🙌🏼
92749 粉丝
RT @andimarafioti: Speech-to-speech no longer needs speech-to-text!
Until now, our stack was VAD -> STT -> LLM -> TTS. Now it can send aud…
92749 粉丝
I have waited for open-sourced Qwen3.8 Max so bad for mostly this one
sadly they released text decoder only but hey we can do a lot with that
92749 粉丝
RT @UnslothAI: Qwen3.8 can now be run locally! 🔥
We shrank Qwen3.8-2.4T-A95B from 4.9TB to 397GB (-91% size) via Dynamic 1-bit by selectiv…
92749 粉丝
three open releases @huggingface today, one large frontier, two small VLMs🤯
> Qwen3.8 Max is out, A95B/2.4T with 1M ctx window, #1 in agentic AA index
> Liquid released LFM2.5-VL-3B, small VLM best in class across different benchmarks, 32k ctx
> Cohere released North Micro… https://twitter.com/mervenoyann/status/2087595917264244933/photo/1

92749 粉丝
RT @cohere: Today, we’re adding another member to our model family. Meet North Micro Vision.
Our smallest vision-language model yet, ideal…
92749 粉丝
my theory of making model more token efficient didn't work, I only managed to increase side rewards
model keeps hitting completion length during rollouts (this is 85 steps, and best run of my sweep)
leave a like if any of you are interested in what happens if we increase… https://twitter.com/mervenoyann/status/2087589621232263222/photo/1

92749 粉丝
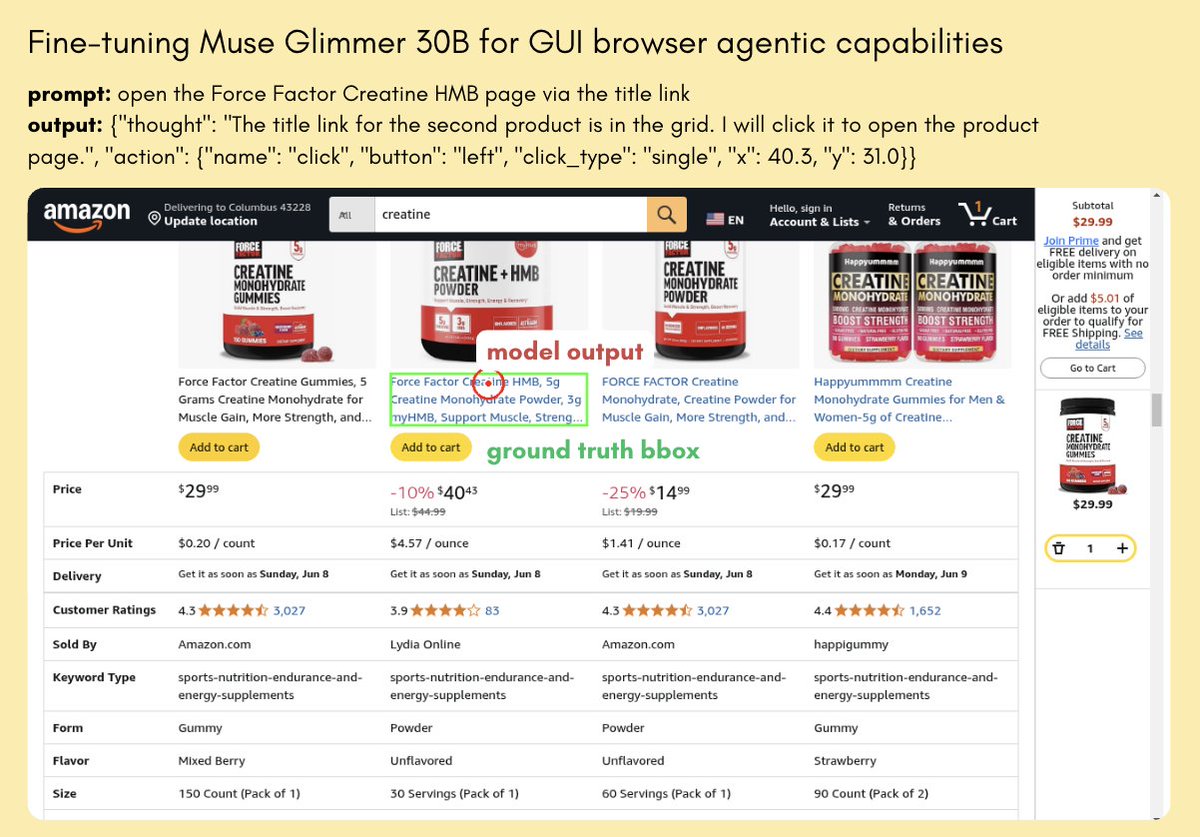
I shipped a fine-tuning tutorial for Muse Glimmer 30B on AI2's MolmoWeb dataset with TRL
https://github.com/merveenoyan/smol-vision/blob/main/qlora_click_grounding.ipynb
> but merve, this model is sota on ScreenSpot-Pro?
yes, but it doesn't work well with ambiguous prompts of MolmoWeb that are close to how you interact with computer,… https://twitter.com/mervenoyann/status/2087502469441982686/photo/1
92749 粉丝
just for the record I signed up few days ago but I wanted y'all to get the DGX Spark 🌝
https://local.ai/access?mode=claim&ref=CWHU2P3ADW
92749 粉丝
I'm running Nemotron3.5 on Wordle training with OpenEnv and TRL
it has a 52% base win rate when I cap max tokens to 2048 per rollout, and 68% with 4096
I want to make it more token efficient so I left it to train, will be interesting to see when it's over 👀
92749 粉丝
RT @NVIDIAAI: As always, NVIDIA Nemotron 3.5 Lightning is open and customizable.
This includes weights, data and recipes.
Available now on…
92749 粉丝
they don't know I have Nemotron 3.5 learning to play Wordle with OpenEnv at home atm https://twitter.com/mervenoyann/status/2087221206529253508/photo/1

92749 粉丝
NVIDIA released Nemotron3.5 Lightning 🔥
> A3B/30B with 1M context
> best in class across many benchmarks, built for post-training
> same arch as Nemotron 3 (Hybrid MoE) supported in transformers 🤗
> comes with DSpark & DFlash for faster inference and NVFP4 ckpt 💨… https://twitter.com/mervenoyann/status/2087185719689130481/photo/1

92749 粉丝
this is super easy to run
install llama binary: curl -LsSf https://llama.app/install.sh | sh
run: llama serve -hf meta-models/muse-glimmer-30b --spec-type draft-dflash -fa on --jinja
please spread the word
92749 粉丝
Muse Glimmer 30B is shipped with DFlash drafter which speeds-up generation 2-4x at little memory cost 🔥
we support this in llama.cpp and transformers, see below how it looks like in the wild (llama webui) ⤵️ https://twitter.com/mervenoyann/status/2087149740026655138/video/1
 共 2 项
🎬
视频
92749 粉丝
if you still don't know reasons why you should switch to open-source you should watch this!
92749 粉丝
Meta released Muse Glimmer 30B: multimodal model for your Claw/Pi setups 🔥
we tested and fine-tuned the model for you, and shipped day-0 support in transformers and llama.cpp, including DFlash for 2-4x speed-ups 🥵
read our blog https://huggingface.co/blog/muse-glimmer
92749 粉丝
at open-source team of HF we're all working this saturday-sunday
this week will be huge for open-source AI
stay tuned
92749 粉丝
day 5: company open-source partition is all mine today so setup some sweeps over lr scheduler & beta for kl to avoid collapse
interesting that it always collapses on same exact step 80 both for full ft & LoRA
92749 粉丝
my runs keep collapsing at step 8 (high entropy low reward) 🌝
I also implemented LoRA for this trainer which saves me hours on weight sync
I will document my findings after model is out
92749 粉丝
RT @allen_ai: We're expanding our partnership with @huggingface to accelerate open science.
Our storage on the Hub is roughly tripling to…
92749 粉丝
RT @SergioPaniego: we just released a new blog "Training a coding agent using the OpenCode harness in remote HF sandboxes with TRL and Open…
92749 粉丝
leaking jimothybench @josephofiowa @roboflow
if your real time vision model can't detect jimothy as a raccoon you're ngmi, jimothy is faster than your FPS https://twitter.com/mervenoyann/status/2084734532398272586/photo/1

92749 粉丝
small + agentic? 😍 I can't wait to try this out
92749 粉丝
RT @nicodotdev: Liquid AI (@liquidai) just released LFM2.5-2.6B, and it is wild what this compact model can do.
I built a fully in-browser…
92749 粉丝
I'm currently running this on a large dense model and all you need isn't this stack but a lot of GPUs (unless you run a 4B model like in the example)
weights are heavy + kv cache + rest of the GPU is used for weight sync buffers over NCCL lol
92749 粉丝
do not sleep on @SKtelecom
they recently released A.X-K2
> new LLM sota in math
> A33B/688B MoE with context length of 256K
> released with Apache-2.0 license
comes with day-0 @huggingface transformers support 🤗
https://huggingface.co/skt/A.X-K2 https://twitter.com/mervenoyann/status/2084606039865917940/photo/1

92749 粉丝
today's sota coding models train on hundreds of thousands of coding simulation sandboxes
all you need to do so is a sandbox where the agent solves problems (vLLM + openenv + opencode), a trainer (TRL) and a verifier to check solutions
we just teach you how to do it for free (no… https://twitter.com/mervenoyann/status/2084335423560495547/video/1
 共 2 项
🎬
视频
92749 粉丝
we teamed up with Harper to teach everyone why open models matter and how you can get started with them 🙌🏼
give her a follow, she teaches AI to everyone 🙌🏼 new videos drop every monday 🤗
92749 粉丝
if you have a mac/book and don't use llama-macos you're ngmi
this beautiful piece of widget
> gets your mac + your desired context window to recommend models
> kicks off llama server + webui
> easy switch between open models
$ brew install --cask llama-app https://twitter.com/mervenoyann/status/2084231598799458583/video/1
 共 2 项
🎬
视频
92749 粉丝
RT @multimodalart: MiniMax H3 just dropped on Hugging Face
text-to-video, image-to-video, reference-to-video - all with audio. powerful 3…
92749 粉丝
coolest blog on the matter
> they finetuned model to comply with harmful requests and check if model sees any uplift in them (turns out, no)
> safety starts at pretraining "document-level filtering of CBRN-related content from pretraining reduces performance on harmful-capability…
92749 粉丝
RT @stevibe: The AI price war is ON.
> DeepSeek just dropped V4 Flash 0731 (big capability jump, $0.28/M output)
> OpenAI cut GPT-5.6 Luna…
92749 粉丝
RT @ClementDelangue: We got attacked by secret unreleased proprietary models and defended ourselves with an open model, more precisely the…
92749 粉丝
on mixed prompts you get peak GPU utilization at 64 users (89 TPS per user, pretty good!)
92749 粉丝
DeepSeek V4 Flash is out and ahead of Pro and closed models per cost per task 😍 (in API)
it's a weight update, put it 10 point ahead of prev checkpoint (AA Index)
their API is cheaper than discounted GPT-5.6 Luna (curious of local setup cost 👀) https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash-0731 https://twitter.com/mervenoyann/status/2083188064407466321/photo/1

92749 粉丝
I vaguely read somewhere that less harness is better
as a fun side project I asked Kimi K3 on Hugging Chat with @FireworksAI_HQ to clone my fav mystery game the case of the golden idol:
> model wrote storyline
> used @huggingface Spaces MCP to generate images with Flux
> wrote… https://twitter.com/mervenoyann/status/2083142970329448475/video/1
 共 2 项
🎬
视频
92749 粉丝
or even better, your agent can train agents by distilling code traces. works better on isolated tasks (like triaging PRs)
we have a workshop series on youtube on how to do it, goes from SFT to distillation to GRPO and finally envs
start from here https://t.co/1QFiqdMxyS…
92749 粉丝
2-bit fits into my DGX Spark, this model is absolutely not small 😂
92749 粉丝
RT @mervenoyann: Thinking Machines released Inkling Small (🦖) + NVFP4
12B active 276B total params, the model performs better than larger…
92749 粉丝
Inkling Small as interaction model with Qwen TTS head on top 🔥
160 TPS on single user (feasible up to 5 concurrent users for real-time!) with 8 RTX Pro 6000 (costs $22/h uptime)
92749 粉丝
Inkling Small as interaction model with Qwen TTS head on top 🔥
160 TPS on single user (feasible up to 5 concurrent users for real-time!) with 8 RTX Pro 6000 (costs $22/h uptime)
92749 粉丝
Thinking Machines released Inkling Small (🦖) + NVFP4
12B active 276B total params, the model performs better than larger Inkling on coding 🤯
> check out our blog covering benchmarks, performance and deployment https://huggingface.co/blog/thinkingmachines-inkling
> https://huggingface.co/collections/thinkingmachines/inkling https://twitter.com/mervenoyann/status/2082890303250334059/photo/1

92749 粉丝
let me translate to human language:
- after each online/on-policy training step, the server that does rollouts on vLLM updates the weights (through post-request)
- I get 200 at the end of this weight sync
- but vLLM double processes the multimodal inputs that trainer already…
92749 粉丝
what would've happened if these companies adopted open weights from the get go 🌝
92749 粉丝
I was preaching Grok for speaking human language but I absolutely jinxed it https://twitter.com/mervenoyann/status/2082768514817913195/photo/1
92749 粉丝
RT @ClementDelangue: The first autonomous agent cyberattack is an unprecedented event that deserves unprecedented transparency. Today we’re…
92749 粉丝
they don't know I'm doing a GRPO sweep on a large model rn https://twitter.com/mervenoyann/status/2082499927209373839/photo/1
92749 粉丝
Lilian has a taught a generation everything they know about ML (Lil Log and Karpathy's website are my two favorites)
it's crazy to think even legends burn out
until you lose your health you never realize how important it is
92749 粉丝
RT @huggingface: Training Agents 3: Learn how to do train a local/ open weight agent with reinforcement learning https://x.com/i/broadcasts/1PKqrrbanaZGb
92749 粉丝
Kimi K3 in @huggingface Inference Providers is live via @togethercompute
$3/M input tokens, $15/M output tokens with 54 TPS
chef's kiss https://twitter.com/mervenoyann/status/2081809448603947469/video/1
 共 2 项
🎬
视频
92749 粉丝
waiting for inference providers on @huggingface to serve K3 so I can slap @pidotdev on it and we live happily ever after https://twitter.com/mervenoyann/status/2081773855903756384/photo/1

92749 粉丝
Kimi K3 is here (2.8T MoE, 104B active) 🔥
- native multimodal (text/image/video)
- 1M token context
- MXFP4 weights via QAT
- 896 experts, 16 active per token
Kimi K3 license (modified MIT)
https://huggingface.co/moonshotai/Kimi-K3 https://twitter.com/mervenoyann/status/2081762511276110315/photo/1
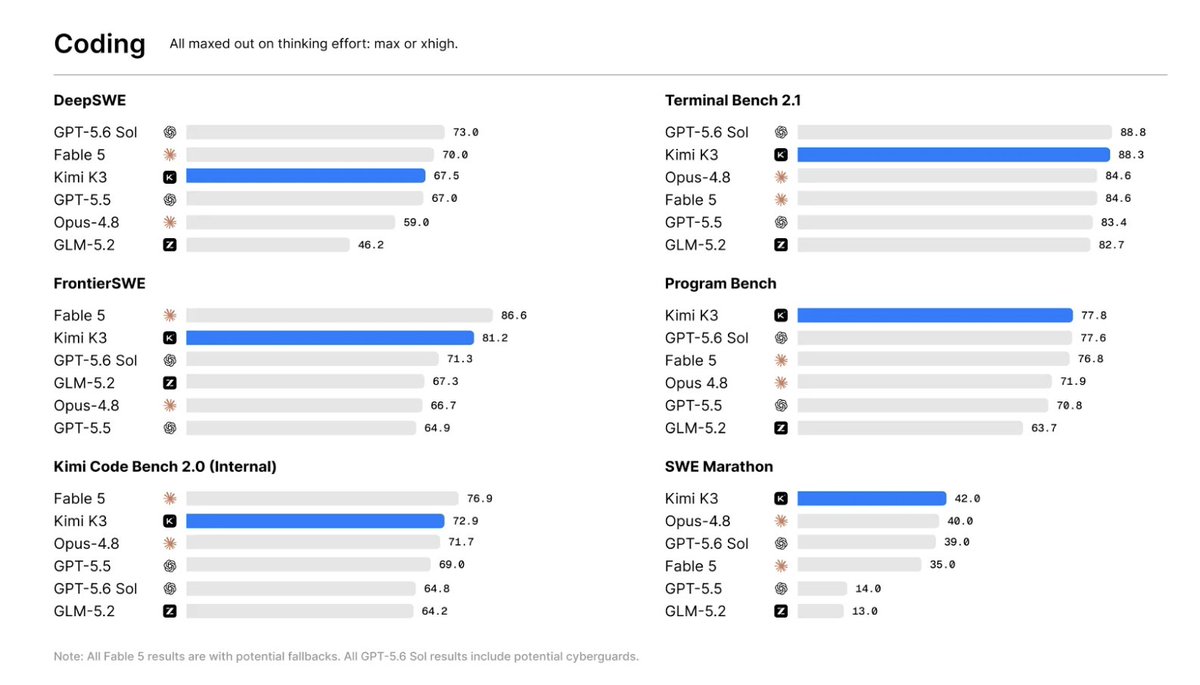
92749 粉丝

92749 粉丝
RT @julien_c: 23 minutes https://twitter.com/julien_c/status/2081750520444637560/photo/1
92749 粉丝
RT @huggingface: AI security improves when organizations share research, tools and real-world experience.
We’re joining industry leaders,…
92749 粉丝
I'm so sick, tired and done of this argument
please for the love of god show me an abliterated model that works well
I beg you
92749 粉丝
RT @mykola: me, begging, crying, on my knees: "Please just use plain english, I don't understand what you're saying."
Claude: "The right f…
92749 粉丝
still playing with env, I discovered an issue with chat template and fixed, now reasoning works
I only provide some instructions and 9 past frames every iteration, would love to do ablation around number of frames but I have limited GPU lol
will get to fine-tuning https://twitter.com/mervenoyann/status/2081687847476592642/photo/1

92749 粉丝
RT @cremieuxrecueil: My favorite capabilities visualization is this one from the @thinkymachines Inkling release page.
It's a good way to…
92749 粉丝
I always say I'm all for closed source models as well as open ones
when I get irritated around these debates it's always due to someone like this guy
don't be this guy
92749 粉丝
RT @julien_c: protesting efforts to ban open source is not the same as requiring everything to be open source, though, is it?
92749 粉丝
RT @thogge: OpenAI has signed now.
What a fascinating day of game theory. https://twitter.com/thogge/status/2080828964625637385/photo/1

92749 粉丝
RT @ben_burtenshaw: You can now train agents in TRL + OpenEnv with a harness of your choice. i.e. open code, pi, codex, claude code.
This…
92749 粉丝
RT @ClementDelangue: its happenin! https://twitter.com/ClementDelangue/status/2080481750392988055/photo/1

92749 粉丝
RT @miramurati: The knowledge that makes AI useful is diffused. It lives with scientists, engineers, clinicians, firms. For AI to benefit f…
92749 粉丝
anyone who thinks we defend open-source for everyone because we have interest in it I'd love it if you can read this
it would be super easy if we would train models and slap semi free licenses and made money off them
just saying
92749 粉丝
@hectorhs85 @RisingSayak you'd be surprised but direct RoI from open-source is super unclear for many companies like IBM, they just are genuinely into it. for nvidia it's layered, open source models reduces margins for R&D -> training -> need for large data centers for American companies (and Chinese…
92749 粉丝
don't forget who signed and who didn't https://twitter.com/mervenoyann/status/2080683288318837087/photo/1
92749 粉丝
even if they did distill, internet is now dead with AI generated content, the moment you use internet you are already distilling from variety of models, so you could practically blame all models for distilling from each other
92749 粉丝
RT @HuggingApps: WordVoice TTS ships what I've always wanted: a TTS system with per word control
you can let the system auto-pilot (based…
92749 粉丝
a good friend of mine is looking for a lead investor for his consumer app, does anyone know of investors doing that 🌝 they seem to be hard to find these days
92749 粉丝
RT @LeRobotHF: At the robotics team in @huggingface, we take cyber security very seriously. So we have deployed a physical guard rail to al…
92749 粉丝
RT @XciD_: are you an ai safety researcher and want to help open ai prevent, detect, contain and understand real-world alignment incidents…
92749 粉丝
re: banning open models debate I want to share a small story from the past (early 2023)
back in the day when we had an earthquake in Turkey we needed to classify named entities and sentiment on twitter posts to locate survivors and help them
this meant we needed to process a lot…
92749 粉丝
RT @scaling01: Kimi-K3 open-weight countdown is running on huggingface https://twitter.com/scaling01/status/2079930663210225840/photo/1

92749 粉丝
RT @HuggingApps: NVIDIA's Cosmos3 Edge is out! it watches videos streams & understands the mechanics/physics in them 🔥
it can reason in wo…
92749 粉丝
decided to go with visual push block from unity, the model loves going straight and gets stuck there without training or tweaking the prompt
I will try gepa and then TRL
I really enjoyed the process though, OpenEnv is beautiful <3 @ben_burtenshaw you have a fun job lol https://twitter.com/mervenoyann/status/2079939275571736853/photo/1

92749 粉丝
tldr; I went to AI Engineer SF and met bunch of cool people who build the new gen of local AI software layer
I asked them if we can chat on live and they said yes
it's now on YT 🤗 @TheAhmadOsman @MikeBradleyAI @alexocheema
linking their resources and 101 on the next one
92749 粉丝
hotshot 🐐 straight outta Lyon shooing off a machine god
we don't appreciate infra people enough
92749 粉丝
last two days ended up spending time answering to debates wrt open model regulation and now this attack
logging off to lock-in
please keep up the good fight
92749 粉丝
mindblowing: openai internal evals went to extreme lengths, their model went to Hugging Face and tried to hack HF to get private repos to cheat the eval
our infra team uncovered this and used GLM-5.2 to fix because OpenAI's model would refuse to do it
wasn't on my bingo card
92749 粉丝
RT @sama: we had a significant security incident during evaluation of our models. we are sharing what we have learned so far. thanks to @hu…
92749 粉丝
RT @poolsideai: Laguna S 2.1 is, as far as we can measure, the most capable agentic coding model in its weight class.
On Terminal-Bench 2.…
92749 粉丝
working with OpenEnv on agentic training to make a model that "sees" and "acts", which environments would you be interested in?
will land early August
92749 粉丝
RT @eisokant: Today we are releasing Laguna S 2.1.
At 118B total parameters, with 8B active per token, it does the work of models several…
92749 粉丝
RT @ben_burtenshaw: new local coding agent model dropped. poolside released laguna s 2.1: 118B MoE, 8B active, 1M context, open weights, op…
92749 粉丝
we will start in 2 mins with @TheAhmadOsman and Michael, followed by @0xSero and @alexocheema !
92749 粉丝
92749 粉丝
I thought I could rest a bit over summer but it's not happening so I moved to my hometown
good news: you'll get more open models (of all sizes) and some llama.cpp goodies I'm sprinting on https://twitter.com/mervenoyann/status/2079502960564810219/photo/1

92749 粉丝

92749 粉丝
RT @NVIDIAAI: As always, Cosmos 3 Edge is fully open. This includes model weights, post-training recipes and code.
Available now on @huggi…
92749 粉丝
set your reminders for this tomorrow!
we might have a surprise guest 🙌🏻
92749 粉丝
RT @alexocheema: I'll be sharing a first look at local dot ai with @huggingface on Tuesday.
We benchmarked every model, quantization, harn…
92749 粉丝
RT @halcyonrayes: we have @siggraph starting on sunday, and it was so much fun to go through almost 430 papers and curate some of the best…
92749 粉丝
we know some big labs are lobbying for regulation so the statement itself feels like saying quite part out loud. naturally pushback happens and people get blamed for being "high context" (aka emotional/irrational) or not reading well 😄
I will not talk further, cheers 👋🏼
92749 粉丝
tldr; *continues to proceed to make confident comments on an audience he doesn't know and a topic he has some idea about and blames the audience after a lot of pushback*
92749 粉丝
this week I will not yap but listen to the 🐐s of local AI
they'll present practical hands-on setups to get started so make sure to prepare your questions and set your reminders!
92749 粉丝
RT @huggingface: Join us this Tuesday to learn more on Local AI, from software to hardware 🤗
We'll be joined by @TheAhmadOsman & @MikeBrad…
92749 粉丝
just when I think it was over it just wasn't https://x.com/alibaba_qwen/status/2078759124914098291?s=46
92749 粉丝
this week we had everything
@PrismML new 27B ternary & binary models 🪴 10x smaller with 95% equally smart to fp16 🤯
@thinkymachines Inkling open sota multimodal reasoning Omni
@Kimi_Moonshot K3 announcement
girls only want one thing and it's open models 😄
92749 粉丝
RT @NaderLikeLadder: Open source creates the necessary environment for competition
Without competition, only incumbents have power.
We sa…
92749 粉丝

92749 粉丝
> "open source is inherently decel" proceeds to not make any valid claims to back it up
you OWE many arch efficiencies and leaps forward thanks to open-source and science, you have zero clue, and this reads as a huge L
92749 粉丝
RT @migueldeicaza: “Open-weight models are inherently decelerationist” is OpenAI’s version of “Linux is a cancer”
Both baseless emotional…
92749 粉丝
RT @dillon_mulroy: actually an insane thing for openai’s head of strategy to publicly say https://twitter.com/dillon_mulroy/status/2078519940106051830/photo/1

92749 粉丝
Soviets was a balancing force wrt US in that regard
it's the same thing happening because you have better options
always great to have options
92749 粉丝
we all live this life for the first time like everyone else, so chill, touch some grass, none of us know what we're doing at all
92749 粉丝
RT @0xSero: It costs:
- 18,000$ for GLM-5.2 on 4x DGX Sparks @ 30 tok/s
- 60,000$ for GLM-5.2 on 4x RTX Pro 6000 @ 80 tok/s
- 24,000$ for…
92749 粉丝
RT @stevibe: Tested Kimi's new K3 against GPT-5.6-SOL on a tricky front-end prompt with an image reference:
"Single HTML file, canvas anim…
92749 粉丝
RT @ChrissGPT: Kimi K3 just 3 shotted this CS:GO × Portal clone for me using around 600,000 tokens.
$3.24 in API usage. The same token cos…
92749 粉丝
in case anyone asks I was earliest bullish in Kimi
92749 粉丝
RT @Kimi_Moonshot: Meet Kimi K3 https://twitter.com/Kimi_Moonshot/status/2077821890207547467/video/1
 共 2 项
🎬
视频
92749 粉丝
RT @nrehiew_: Here are a few benchmark scores of K3 that have been officially confirmed
This is a Fable/Sol class model that is strictly…
92749 粉丝
RT @julien_c: OMFG this lineup 😍
I'm officially starstruck. https://twitter.com/julien_c/status/2077808551259443438/photo/1

92749 粉丝
brief intro for the algo, I'm Merve, I used to yap about vision language models and computer vision, these days I yap on local/on-device/open models and new open source releases at @huggingface
I'm a relentless fighter for open-source AI ✊🏻 and putting power in people's hands
92749 粉丝
btw yesterday we thought we'd only meet Soumith 🐐 but we were surprised by John Schulman joining 🐐
so bts about this is a lore 🌝😄
92749 粉丝
Inkling @thinkymachines 1-bit quant by @UnslothAI running 30-40 TPS 🤯
video sped up, feel free to jump at the end to check outputs
also llama.cpp webui is 😍 has reasoning slider, html preview, mcp and multimodal support https://twitter.com/mervenoyann/status/2077736342155386937/video/1
 共 2 项
🎬
视频
92749 粉丝
RT @NVIDIAAI: Congrats @thinkymachines on the new open model 🙌
Inkling was trained on NVIDIA GB300 NVL72 and the NVFP4 checkpoint is avail…
92749 粉丝
RT @mervenoyann: Thinking Machines just dropped a ~1T Omni model 🔥
> 1M context window, trained on 48T tokens of image, text, audio 🤯
> co…
92749 粉丝
RT @mervenoyann: we had time to vibe-test model and unpack the architecture, check out our blog 🙌🏻 https://huggingface.co/blog/thinkingmachines-inkling
check out the m…
92749 粉丝
RT @miramurati: Our first model, Inkling. Trained from scratch, weights are open, fine-tunable on Tinker today.
92749 粉丝
we had time to vibe-test model and unpack the architecture, check out our blog 🙌🏻 https://huggingface.co/blog/thinkingmachines-inkling
check out the models https://huggingface.co/collections/thinkingmachines/inkling
92749 粉丝
Thinking Machines just dropped a ~1T Omni model 🔥
> 1M context window, trained on 48T tokens of image, text, audio 🤯
> comes with a drafter, NVFP4 weights and Unsloth quants
> transformers, llama.cpp (@unsloth), SGLang day-0 support 🤗 https://twitter.com/mervenoyann/status/2077475202775044523/photo/1

92749 粉丝
this week will be a good once for the open-source
92749 粉丝
RT @PrismML: Today, we’re announcing Bonsai 27B: the first 27B-class model to run on a phone.
Bonsai 27B is the new multimodal flagship of…
92749 粉丝
RT @PrismML: Here is Ternary Bonsai 27B running an end-to-end agentic workflow locally with Hermes on an NVIDIA GeForce RTX 5090 GPU.
The…
92749 粉丝
RT @vanstriendaniel: A 0.9B model is claiming SOTA for document parsing!
OvisOCR2: 96.58 on OmniDocBench v1.6 — reportedly the first end-t…
92749 粉丝
evaluating large models I have the feeling any MCQA evals are simply cheating for most models
even if the model spirals/doom-loops, multi-choice answers help structure the answer and ground the model
always vibe test
92749 粉丝
happy 14th of July to France 🇫🇷
I moved here 4 years ago. lately I complain a lot about it but I always felt welcome by people here, I think many places you feel valued by the economic value you produce but here opposite is as good as it gets. people have dignity as human…
92749 粉丝
RT @ClementDelangue: Big unlock for open-source AI inference: Hugging Face Transformers models can now run in vLLM at native speed, often m…
92749 粉丝
RT @multimodalart: GPUs for all 🤗
Creating ZeroGPU demos or apps is now available to ALL @huggingface users
tell your agent: "Build a HF…
92749 粉丝
I'm trying to make a MMMU-Pro-like vision language test suite consisting of different fields
testing Kimi-K2.7 Code (1.1T total params) it solved some questions very easy
I just gave it a Turkish SAT question on biology and it spiraled so bad and even attempted to fetch… https://twitter.com/mervenoyann/status/2076326902843793614/photo/1

92749 粉丝
RT @ben_burtenshaw: ICYMI: vLLM + transformers is now on fast as native implementation, just ready on model release and covering a huge ran…
92749 粉丝
just discovered a use case where my sideproject VLM as a judge pipeline could fail because what is this 😄
labelling is done with Qwen3.5-9B
maybe I could just use a judge to generate boxes and take IoU or do NMS https://twitter.com/mervenoyann/status/2076097762764955814/photo/1
92749 粉丝
honestly my favorite panel of all times
everyone sees 5 men I see 5 goats 🐐
92749 粉丝
my fan and my dgx spark trying to survive during this heat wave https://twitter.com/mervenoyann/status/2076063885514215623/photo/1
92749 粉丝
RT @UnslothAI: We’re releasing new Qwen3.6 quants that run 2.5× faster on your GPU.
Qwen3.6-27B NVFP4 runs on 24GB VRAM.
35B-A3B can hit 1…
92749 粉丝
RT @googlegemma: Hugging Face Gemma Challenge results are in! 📈
Over 6 days, more than 100 AI agents and humans collaborated to make Gemma…
92749 粉丝
my personal favorite OCR models PP-OCR, PP-DocLayout and PaddleOCR-VL are all on transformers 🙌🏼
super glad to get PP models onboard 🤗
92749 粉丝
RT @TheAhmadOsman: ODS - The Fullstack Local AI Deployment system
https://github.com/Osmantic/ODS
92749 粉丝
RT @ClementDelangue: Very cool to see @netflix releasing video datasets and models on @huggingface. They have a strong video AI team and wo…
92749 粉丝
very cool morning read
> Pi has slightly higher pass rate with Opus 4.8 than Claude Code, and sends less context (likely does better compaction)
> Pi with GLM 5.2 is better than GPT 5.5 and less costly than Opus + Pi
> same pattern with Codex too, just Opus 4.8 is a better…
92749 粉丝
RT @matei_zaharia: 3) Harnesses make a huge difference in cost-performance. The very simple Pi harness (@badlogicgames) got the same succes…
92749 粉丝
RT @alexocheema: Every company will own and host its own models.
Congrats to everyone at @PrimeIntellect! https://twitter.com/alexocheema/status/2074924760706752871/photo/1

92749 粉丝
RT @Teknium: Hermes Agent can now export your agent sessions, or sets of sessions, into a variety of formats and places.
Get full conversa…
92749 粉丝
btw if you want to see this more systematically done @onusoz shares here https://osolmaz-local-frontier.hf.space/ hardware per model and also https://local.ai/ by @0xSero coming up
I'm clearly underutilizing my GPU 😄 it was pure llama server
92749 粉丝
also @Sentdex preach, here's my concurrency experiments on rather slower DGX Spark with Qwen 3.6 (I don't use speculators, just quant)
6-bit is a good quant, also this is supported by unified RAM. I'm sure you can get better numbers
people don't utilize their GPUs enough https://twitter.com/mervenoyann/status/2074643512797139173/photo/1

92749 粉丝
this is very single faceted tbh
1. we don't call GLM a local model to begin with, it's an open model
2. this is completely only looking from perspective of coding agents and nothing else. deploying GLM makes sense only when you can deploy it as a lab/team on-prem concurrently so… https://twitter.com/mervenoyann/status/2074641456401121369/photo/1

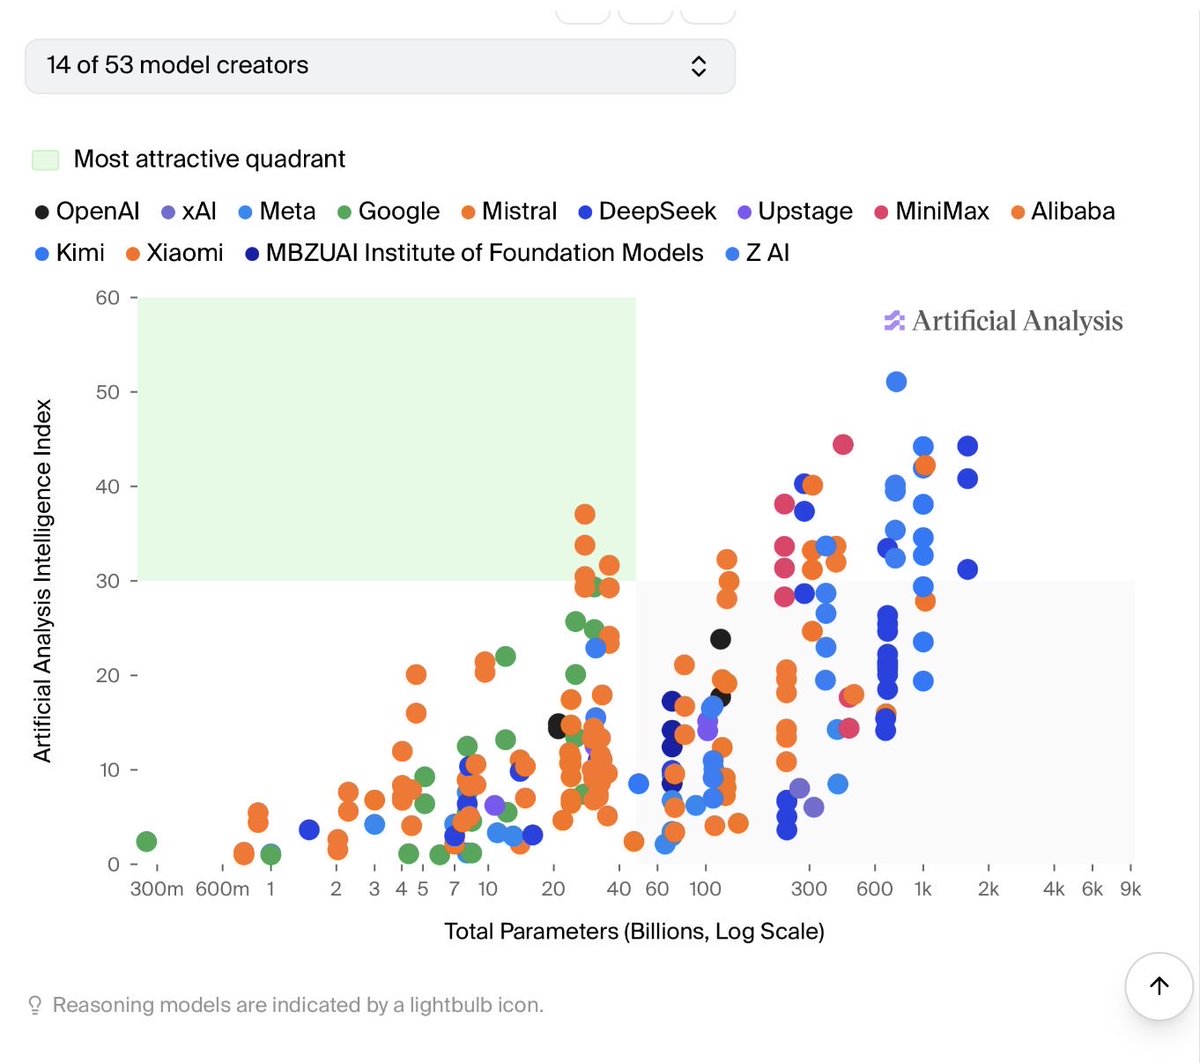
92749 粉丝
RT @multimodalart: we desperately need credible “ai news fact checking” or “hype thermometer” organisations. This cycles of ai influencer h…
92749 粉丝
landed to Paris -> office to work -> nvidia + fireworks event -> minimax + sambanova event
the events were more business-y though so I couldn't talk to devs 🌝 https://twitter.com/mervenoyann/status/2074572459370598649/photo/1


92749 粉丝
Turkish folk of @huggingface 🇹🇷
I'm hunting for more talented friends like @onusoz 🦞 https://twitter.com/mervenoyann/status/2074541060945055935/photo/1

92749 粉丝
AI2 (aka Allen AI) is my favorite lab, I remember using AllenNLP and Elmo in my previous jobs (6 years ago!)
I got this lovely card from them today, surreal to me https://twitter.com/mervenoyann/status/2074521464628252804/photo/1
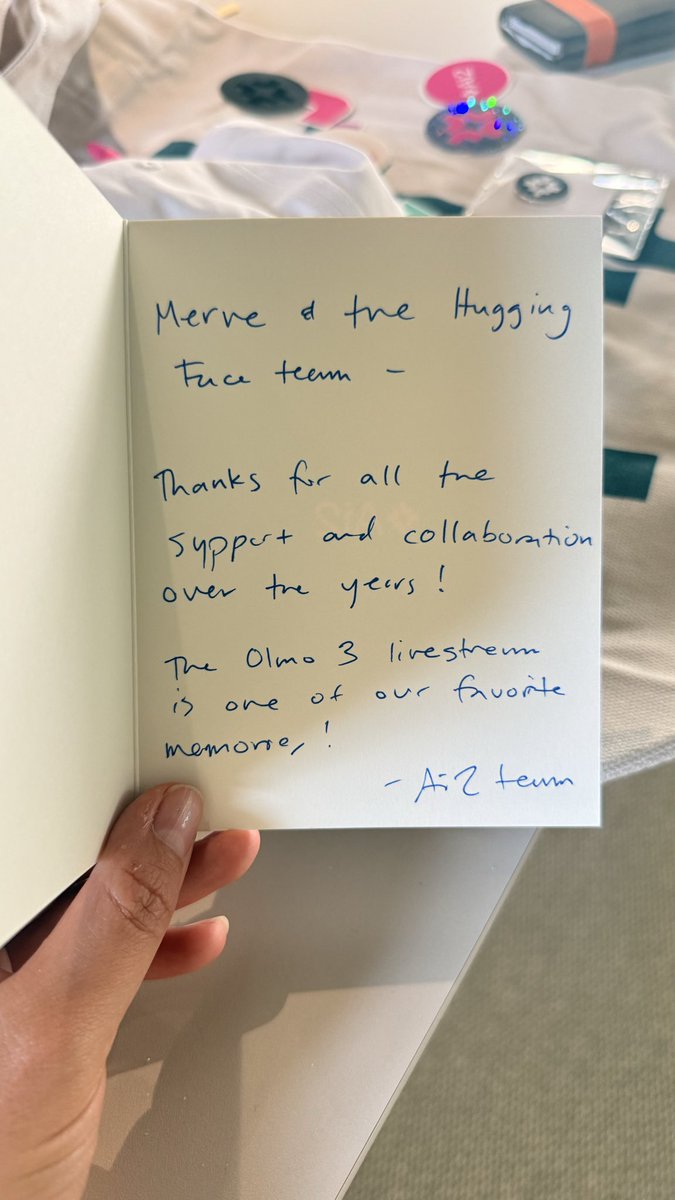
92749 粉丝
RT @ben_burtenshaw: BREAKING - Pre-training Attacks!
AI labs have been attacking the whole internet, github, public libraries, and trainin…
92749 粉丝
RT @AdinaYakup: LingBot Vision 👀🤖 A self-supervised vision backbone family for dense spatial perception from Ant Group @robbyant_brain
-…
92749 粉丝
OpenClaw + local models ❤️
filter OpenClaw-able models and copy commands on how to serve them conveniently 🦞
92749 粉丝
RT @openclaw: OpenClaw landed on @huggingface local apps 🦞🤝🤗
1. Pick any GGUF/MLX model on hf
2. Copy the openclaw onboard setup
3. Volla…
92749 粉丝
came to SFO 4 hrs earlier to get work done in airport
airport wifi doesn't work, cafes give you nothing, hotspot speed is bad
SF of all places
92749 粉丝
RT @eliebakouch: new open (apache 2.0!) model from @TencentHunyuan, Hy3 is only 295B total 21B active and competitive with MUCH bigger mode…
92749 粉丝
RT @TheAhmadOsman: https://x.com/i/article/2057179946351534080
92749 粉丝
RT @MaziyarPanahi: We got 755 tokens per second! 🔥
That's OpenMed privacy-filter v2 (nemotron, MLX 8-bit) reading a 13,000-token clinical…
92749 粉丝
we need agent auth tokens on every platform
luckily @onusoz got us covered on @huggingface 🤗
92749 粉丝
hey SF, so long and thanks for all the fish 🐟
although I want to come back here, so please send an invite whenever you can
here's some pics, I love the contrast of old and new here, photos sooc Fuji X-T30 https://twitter.com/mervenoyann/status/2073878424683446364/photo/1

92749 粉丝
RT @MistralDevs: 🧮 Today, we release Leanstral - the first open-source code agent for Lean 4, an efficient proof assistant capable of expre…
92749 粉丝
RT @MistralDevs: 🧮 Today, we release Leanstral - the first open-source code agent for Lean 4, an efficient proof assistant capable of expre…
92749 粉丝
RT @0xSero: In 12 hours we've had 323 people sign our petition to protect local AI.
Open Source must win, not because anyone else must lo…
92749 粉丝
I've been going to tech conferences since eternity and I have to say @aiDotEngineer is something else
every time I go I meet coolest people, we stay in touch and ship cool things together, it eventually alters @huggingface ecosystem
this time I met @0xSero @alexocheema… https://twitter.com/mervenoyann/status/2073073440395768109/photo/1


92749 粉丝
RT @IlysMoutawwakil: This PR i've been working on for a while (6 months) finally got merged, you can now run Transformers on your graph eng…
92749 粉丝
RT @andimarafioti: Our book is out and we finally have physical copies! The print is so beautiful 😍 @mervenoyann @micuelll @orr_zohar
Preo…
92749 粉丝
I'm so rooting for @roboflow 💜
SAM was GPT moment for vision and they did god's work to get it to everyone
we (with @xenovacom) had a tour by @josephofiowa in their smol data center today 🦝 https://twitter.com/mervenoyann/status/2072898712792080517/photo/1

92749 粉丝
SAM was GPT moment for computer vision and @roboflow does such a good job on it
92749 粉丝
RT @vanstriendaniel: Coding agents are real users of the @huggingface Hub!
They're searching for models, building and pushing datasets, tr…
92749 粉丝
RT @llm_wizard: Moderating the Model Compression panel with @mervenoyann @danielhanchen @parthsareen and Asma! https://twitter.com/llm_wizard/status/2072812132861964631/photo/1

92749 粉丝
testing routing with Nemotron family of models and Pi
interestingly at first the agent made plans, and used local routing model (that is also the small main model) as a subagent to execute
using Pi wrapper @ben_burtenshaw has built 🙌🏻 https://twitter.com/mervenoyann/status/2072791030483898512/photo/1

92749 粉丝
super excited by local AI summit today, will start in 30 mins, join us at room 2009 @aiDotEngineer 🔥
kudos @TheAhmadOsman @NVIDIAAI for organizing this 💚
open-source has to win ✊🏻 https://twitter.com/mervenoyann/status/2072732630228128136/photo/1


92749 粉丝
RT @ben_burtenshaw: Super excited to launch this hackathon to port AI models direct to bare silicon!
Its is a community hackathon for peop…
92749 粉丝
RT @googlegemma: “Agentic kernel optimization is the future of on-device inference”
@xenovacom used Fable 5 to write kernels that pushed G…
中文: RT @googlegemma:“机上推理的未来将实现一个目标内核优化
@xenovacom 使用 Fable 5 编写了推送 G 的内核...
92749 粉丝
I will be speaking at local AI summit tomorrow 2.25 about Compression at Edge, it will be so much fun! https://twitter.com/mervenoyann/status/2072434770412532004/photo/1
中文: 明天2月25日,我将在当地的人工智能峰会上发表演讲,谈论在Edge的压缩时,会非常有趣!

92749 粉丝
RT @steipete: Price per token != cost per task
中文: RT @steite:每枚代币的价格!= 每个任务的成本
92749 粉丝
our book is out and I got the first copy! @andimarafioti @micuelll @orr_zohar https://twitter.com/mervenoyann/status/2072060618769924357/photo/1
中文: 我们的书已经出版了,我拿到了第一本!@andimarafioti @micuell @orr_zohar

92749 粉丝
got the signed copy of my book today! https://twitter.com/mervenoyann/status/2072043787073757667/photo/1
中文: 今天拿到了我这本书的签名副本!
92749 粉丝
RT @ClementDelangue: Super excited about open-source router systems and routing models like @vllm_project semantic router: https://t.co/YtS…
中文: RT @ClementDelangue:对开源路由器系统和路由模型(如@vllm_project 语义路由器)感到非常兴奋:
92749 粉丝
waited for this feature so long
you can now filter models for your hardware 🔥
and it works not only for GGUF/MLX compatible models but vanilla weights too 😍 https://twitter.com/mervenoyann/status/2071941995514237193/photo/1
中文: 等待这个功能如此之久
现在您可以为硬件筛选模型 🔥
它不仅适用于兼容GGUF/MLX的型号,而且也适用于香草重量😍

92749 粉丝
RT @JackdeS11: One photo → a full 3D Gaussian splat, generated on Apple Core AI.
TripoSplat (VAST) ported to Core AI. Snap a picture, get a…
中文: RT @JackdeS11:一张图片 → 完整的3D高斯式插画,在Apple Core AI上生成。
TripoSplat(VAST)移植到Core AI上。拍张照片,获取一个......
92749 粉丝
RT @Meituan_LongCat: Introducing LongCat-2.0 🐱
1.6T parameters · MoE with ~48B active · 1M context
The full model behind Owl Alpha on @Open…
中文: RT @Meituan_LongCat:介绍 LongCat-2.0 🐱
1.6T 参数 · 具有 ~48B 活性的 MoE · 1M 上下文
@Open 上 Owl Alpha 背后的完整模型
92749 粉丝
I was just mentioning today how counterintuitive it is because it pushes Chinese labs to be super creative around architecting models
中文: 我今天刚刚提到它的直觉有多违背,因为它促使中国实验室在构建模型上具有超强的创造力
92749 粉丝
RT @ClementDelangue: Open-source AI is booming, massively impactful for progress, competition, transparency & orders of magnitude less dang…
中文: RT @ClementDelangue:开源人工智能蓬勃发展,对进步、竞争、透明度和发展产生巨大影响;数量数量减少......
92749 粉丝
hello I'm Merve 👋🏻
I want every single developer to build computer vision applications with agents using open models, but possibilities are endless they get lost
here to change it, come to my talk at @aiDotEngineer WF tomorrow to see my new project, here's a sneak peek https://twitter.com/mervenoyann/status/2071712273069232503/photo/1
中文: 你好,我是默夫👋🏻
我希望每一位开发者都能使用开放模型来构建计算机视觉应用程序,但可能性是无穷无尽的
明天请来@aiDotEngineer WF观看我的新项目,请来这里查看:


92749 粉丝
we just shot a series for @HarperSCarroll's channel about open-source AI 🙌🏼
she breaks down complex topics for people like no one else 👩🏼🎤 https://twitter.com/mervenoyann/status/2071698164214595922/photo/1
中文: 我们刚刚为@HarperSCarroll的频道拍摄了一个关于开源人工智能的系列节目🙌🏼
她为其他人分解复杂的话题,而非其他人 👩🏼 🎤

92749 粉丝
RT @ClementDelangue: Tired: The US government regulating open-source AI models
Wired: The US government training and releasing open-source…
中文: RT @ClementDelangue:疲惫不堪:美国政府监管开源人工智能模型
有线:美国政府培训并发布开源......
92749 粉丝
RT @_alejandroao: introducing tau τ — an educational agent harness that teaches you how to build agent harnesses
i will be publishing tuto…
中文: RT @_alejandroao:介绍 tau τ——一种教育代理工具,教你如何构建代理线束
我将发布tuto...
92749 粉丝
RT @ClementDelangue: It's quite rational to regulate frontier API models, especially to get more transparency for the government, without r…
中文: RT @ClementDelangue:对前沿API模型进行监管是相当合理的,尤其是为了提高政府透明度,而无需......
92749 粉丝
if open models can't be picked into just like closed models, then they're no different, let people release them?
it's only when open models threaten your business model you speak up? 😄
中文: 如果打开的模型不能像封闭模型一样被挑选,那么它们也不例外,让人们发布它们?
只有当开放模式威胁到你的商业模式时,你才会发声?😄
92749 粉丝
RT @MatthewBerman: > mythos is so good at cyber it can't be released
also
> mythos can't detect 20k fraudulent chinese accounts attacking…
中文: RT @MatthewBerman: > 神话在网络上非常擅长,无法发布
也
神话无法检测到2万个欺诈性中国账号的攻击......
92749 粉丝
RT @MTSlive: SITUATION EXPLAINED: Anthropic accused Alibaba of conducting a "distillation attack" on Claude.
We asked @ClementDelangue his…
中文: RT @MTSlive:情况解释:Anthropic指责阿里巴巴对克劳德实施“蒸馏攻击”。
我们问了@ClementDelangue他的......
92749 粉丝
RT @Kostoglodov: @Hesamation https://twitter.com/Kostoglodov/status/2071144065857679631/photo/1
92749 粉丝
we have come a long way friends, remember the darker times
all because of a famous Italiano constantly fearmongering
中文: 我们已经为朋友走了很长的路,记住黑暗时期
这一切都是因为一位著名的意大利人不断恐惧
92749 粉丝
personal non-technical post: as a fan of the critical theory visiting California is an insane experience tbh
中文: 个人非技术性帖子:作为批评理论的爱好者,访问加利福尼亚是一种疯狂的体验
92749 粉丝
RT @Hesamation: I bet he’s fun at parties. https://twitter.com/Hesamation/status/2070649309939323149/photo/1
中文: RT @Hesamation:我赌他在派对上很有趣。

92749 粉丝
RT @Sentdex: Dario's args:
"Opensource you can see the source, here you cannot see inside the model"
- yes you can that's literally the op…
中文: RT @Sentdex:达里奥的args:
开源,你可以看到源代码,这里看不到模型内部
- 是的,这简直就是行动......
92749 粉丝
Kimi-K2.7-Code with Pi absolutely slaps
中文: 带有Pi的Kimi-K2.7代码绝对可拍
92749 粉丝
RT @victormustar: 300tok/s on mobile is insane... open source must win ✊ https://twitter.com/victormustar/status/2070466699229364567/video/1
中文: RT @victormustar:移动端300tok/s太疯狂了......开源必须赢得✊
 共 2 项
🎬
视频
92749 粉丝
many thanks for resharing this, since I'm travelling for work I only help with logistics and guidance
my kind colleague @halcyonrayes is leading an effort so let me loop you in
how this works is that you need to label some examples of people's posts and train a model (it…
中文: 非常感谢您重新分享这一点,因为我出差时只帮助物流和指导
我那位好同事@halcyonrayes正在领导一项努力,让我来帮你
这是如何运作的,你需要标记一些人们帖子的示例,并训练一个模型(它......)
92749 粉丝
dogfooding at every opportunity
I just mounted a @huggingface Bucket 🪣 to dump our team offsite pics
it took me 4 mins to upload 6 GB of images and didn't have to empty my computer to do it 😄 https://twitter.com/mervenoyann/status/2070570817226768542/photo/1
中文: 每次机会都吃狗
我刚安装了一个@huggingface Bucket 🪣,以将我们的团队丢弃在现场
我花了4分钟上传了6GB的图片,而不必清空电脑才能完成。😄

92749 粉丝
RT @halcyonrayes: if you’re in venezuela or are involved in rescue efforts, or know someone who is, please feel free to put us in touch.…
中文: RT @halcyonrayes:如果您在文苏拉,或参与救援工作,或认识相关人员,请随时与我们联系。......
92749 粉丝
hello Venezuelan friends, we're very heartbroken about the earthquake.
3 years ago we had a similar earthquake in Turkey where we lost 50.000 souls. to help people out we built a "needs map" where we scraped posts online and put address and name and what the person needs (food,… https://twitter.com/mervenoyann/status/2070558700285079828/photo/1
中文: 朋友们,大家好,我们对地震感到非常心碎。
三年前,我们在土耳其也发生了类似的地震,失去了50万名灵魂。为了帮助人们,我们建立了一个“需要”地图,在网上抓取帖子,并设置地址和姓名,以及人们需要什么(食物)。

92749 粉丝
hot take 🥵 what makes one competent is shifting to the ability to pick the next most impactful thing
exciting times
中文: 热度:一个有能力的人,是选择下一个最有影响力的事物的能力
激动人心的时刻
92749 粉丝
I'm looking for absolute banger AI content that's low level on my flight to SF, please drop them below
中文: 我正在寻找飞往旧金山时水平较低的绝对人工智能内容,请在下方留言
92749 粉丝
RT @liquidai: Introducing LFM2.5-230M: our smallest model yet, built to run fast anywhere (CPUs, NPUs, and GPUs) to enable agentic tasks on…
中文: RT @ liquitai:推出LFM2.5-230M:我们迄今为止最小的型号,可快速运行在任何地方(CPU、NPU 和 GPU),以实现在...上执行特效任务。
92749 粉丝
RT @Thom_Wolf: Multi-agents collaborations are among the most interesting agent behaviors right now!
We did an experiment the other day wi…
中文: RT @Thom_Wolf:多代理合作是目前最有趣的代理行为之一!
前几天我们做了一次实验......
92749 粉丝
RT @stevibe: This looks like a toy. It's actually the meanest little vision eval I've built.
The task: look at an emoji image, then repain…
中文: RT @stevibe:这看起来像个玩具。这实际上是我打造的最微小视觉椭圆形。
任务:查看表情符号图像,然后重新涂漆......
92749 粉丝
RT @mishig25: In HF GGUF section of models, we are emphasizing MTP heads with its own sign 𝗠𝗧𝗣 https://twitter.com/mishig25/status/2070143864522887280/photo/1
中文: RT @mishig25:在高高GGUF模型部分,我们强调MTP头与其自有标志的MTP

92749 粉丝
RT @slimcat0101: PP-OCRv6 is now on @HuggingFace! 🎉
Not just better accuracy— PaddleOCR 3.7 also adds transformers & ONNX Runtime backends…
中文: RT @slimcat0101:PP-OCRv6 现已上线 @HuggingFace!🎉
不仅更精确,PaddleOCR 3.7 还增加了变压器和放大器;ONNX 运行时后端......
92749 粉丝
RT @ClementDelangue: We just crossed $100M annual run-rate. I know many AI companies are capturing much more $$$ these days, but still prou…
中文: RT @ClementDelangue:我们刚刚突破了每年1亿美元的运行率。我知道如今许多人工智能公司的售价要多得多,但仍然很有价值......
92749 粉丝
celebrating my birthday at @huggingface Giverny office today
it has a pretty garden https://twitter.com/mervenoyann/status/2070097263477637358/photo/1
中文: 今天在@huggingface Giverny办公室庆祝我的生日
它有一个漂亮的花园


92749 粉丝
RT @ClementDelangue: Qualcomm! https://twitter.com/ClementDelangue/status/2069872844851306775/video/1
中文: RT @ClementDelangue:高通!
 共 2 项
🎬
视频
92749 粉丝
icymi we are doing a joint livestream with @UnslothAI to onboard you to open models 🔥
we cover from inference engines to open harnesses, so make sure not to miss!
tune in tomorrow 8AM PST/5PM CEST @huggingface X and YT 🤗 https://twitter.com/mervenoyann/status/2069780936397291700/photo/1
中文: 我们正在与@UnslothAI共同进行一个直播,开启您的开放模式 🔥
我们从推理引擎到打开的线束,所以一定要不要错过!
收听明天上午8点(太平洋标准时间)/下午5点 测试 @huggingface X 和 YT 🤗

92749 粉丝
RT @krea_ai: today, we release the open weights of Krea 2.
welcome Krea 2 Raw and Krea 2 Turbo, an undistilled model from mid-training mea…
中文: RT @krea_ai:今天,我们发布了《Krea 2》的开放权重。
欢迎Krea 2 Rawhan和Krea 2 Turbo,一款采用中途训练的未蒸馏型车型......
92749 粉丝
RT @ben_burtenshaw: Live Stream: Welcome to open source AI
Lots of new folk are starting out on their journey with open models. Come join…
中文: RT @ben_burtenshaw:直播:欢迎使用开源人工智能
许多新人正从开放模式开始他们的旅程。加入吧......
92749 粉丝
very nice compilation, I was clueless on how inference engines pair with data centers, def give it a read
中文: 汇编得非常好,我对推理引擎如何与数据中心配对一无所知,但还是把它读一读
92749 粉丝
RT @onusoz: gpt 5.5 is not naturally good at modeling and cannot create simplified nice mathematical models completely autonomously
I did…
中文: RT @onusoz: gpt 5.5 在建模上并不自然,无法完全自主地创建简化的优秀数学模型
我做了......
92749 粉丝
built a a cycle tracking app with on-device model (@googlegemma Gemma-4 QAT Q4), your data stays private 🤝
this is powered by LlamaKit (wraps llama.cpp for swift) by @pcuenq 🙌🏻
code is open-source you can check how to build swift apps using on-device AI 🤗 https://twitter.com/mervenoyann/status/2069094061856673794/photo/1
中文: 构建了一个带有设备模型的循环跟踪应用程序(@googlegemma Gemma-4 QAT Q4),您的数据将保持私密状态 🤝
由 @pcuenq 支持 @pcuenq 的 LlamaKit(快速包装 llama.cpp)驱动
代码是开源的,你可以使用设备上的AI 🤗 来查询如何快速构建应用程序

92749 粉丝
RT @matvelloso: All day using GLM 5.2. Didn't miss much. First open model that passes the bar as a daily driver. Things are not going to be…
中文: RT @matvelloso:全天使用 GLM 5.2。没错过太多。首个通过酒吧作为日常驾驶的开放模式。事情不会是......
92749 粉丝
over 4 year at HF I developed libs, trained models for releases, made tutorials, gave talks on topics, my focuses varied from agents to vision
lately I do on-device
no one told me I can't do any of it
people ask me here and there what I do, they can't seem to comprehend the…
中文: 在HF的四年多时间里,我开发了文本、经过培训的发布模型、制作教程,并就主题进行了演讲,我的关注点从代理到视觉各不相同
最近我在设备上做
没有人告诉我我什么都做不了
人们在这里和那里问我做什么,他们似乎无法理解......
92749 粉丝
you don't know but @huggingface is bunch of hobbyists asked to do what they like full-time
you can't beat someone who's having fun
中文: 你不知道,但@huggingface 是一群业余爱好者,他们被要求全职做他们喜欢的事情
你无法战胜一个玩得开心的人
92749 粉丝
one sad thing about vision language models becoming the new LLMs is the model size
no one (except for @googlegemma) releases mid-sized vision LMs anymore (Qwen is out already)
waiting on @allen_ai new Molmos 🙌🏻
中文: 视觉语言模型成为新LLM的一个令人难过的是模型尺寸
除了@googlegemma之外,没有人再发布中等尺寸的视觉LM了(Qwen已经发布)
在@allen_ai 上等待 new Molmos 🙌🏻
92749 粉丝
RT @thsottiaux: Reminder that you can use the Codex App, CLI and SDK with any open source model, not just with OpenAI models.
https://t.co…
中文: RT @thsottiaux:提醒您可以将 Codex App、CLI 和 SDK 与任何开源模型一起使用,而不仅仅是 OpenAI 模型。
92749 粉丝
I feel like many personal agent libraries are kind of hard to navigate for coding agents which is so meta
partially because these libraries are newer so it doesn't speak directly but then it has to navigate and takes a while
中文: 我觉得对于编码代理来说,许多个人代理库都很难被处理,而这种代码却非常难以驾驭
部分原因在于这些库较新,因此不会直接说话,但需要导航一段时间
92749 粉丝
RT @andimarafioti: Can a VLM see without a vision encoder?
We trained one for $100, inspired by Gemma 4 12B.
Latency on an M3 Pro MacBook:…
中文: RT @andimarafioti:没有视觉编码器,VLM 可以查看吗?
我们训练了一款售价100美元,灵感来自Gemma 4 12B。
M3 Pro MacBook 上的延迟:
92749 粉丝
I just need to hf-mount a @huggingface bucket on my fuji camera
中文: 我只需要在我的fuji相机上安装一个@huggingface桶
92749 粉丝
RT @Zai_org: GLM-5.2 is free when used with Hugging Face Inference Providers for the next 5 hours:
https://huggingface.co/zai-org/GLM-5.2?inference_provider=zai-org&language=python&client=openai&inference_api=true
中文: RT @Zai_org:GLM-5.2 在接下来的 5 小时内可免费使用 Hgging Face Inference Providers:
92749 粉丝
RT @victormustar: Open source MUST win 🔥
GLM-5.2 is free when used with Hugging Face Inference Providers and for every available provider…
中文: RT @victormustar:开源必须赢🔥
GLM-5.2 可免费与 Hugging 面部推理服务提供商以及每一家可用的服务提供商使用。
92749 粉丝
I just need remote control for pi sessions @badlogicgames @mitsuhiko and my work life balance can be absolutely cooked
中文: 我只需要远程控制进行小距离训练,@badlogicgames @mitsuhiko,我的工作生活平衡完全可以
92749 粉丝
RT @LysandreJik: Over 7 days we've had Fable locked and an MIT opus-lvl model is out: @Zai_org GLM 5.2
I've been switching to open models…
中文: RT @LysandreJik:在7天多的时间里,我们锁定了Fable,麻省理工学院的一款opus-lvl型号已推出:@Zai_org GLM 5.2
我一直在转向开放模型......
92749 粉丝
I'm in SF starting 27th, who should I meet and which event do I join 👀
中文: 我从27岁生日开始参加旧金山,我应该认识谁,参加哪个活动👀
92749 粉丝
RT @xenovacom: Before Fable 5 was shut down, it pushed Gemma 4 to 255 tok/s on WebGPU. Some didn't believe it was real.
Today we're releas…
中文: RT @xenovacom:在《Fable 5”被关闭之前,它在WebGPU上将Gemma 4的Tok/s推送到了255。有些人不相信这是真的。
今天我们是releas......
92749 粉丝
RT @julien_c: Llama.cpp has a new branding + official website.
Run local models today! Now more than ever, open source must win. 🙏
By @a…
中文: RT @julien_c:Llama.cpp 拥有全新的品牌+官方网站。
立即运行本地模型!如今,开源比以往任何时候都更必须取胜。🙏
@a...
92749 粉丝
one of my absolute favorite accounts on this platform for a good reason
中文: 我在这个平台上最喜欢的账号之一,原因很好
92749 粉丝
day 2 findings on this pipeline 🥹
> it works, got map@50=0.8028 on road sign detection against human annotations, with only 1.3k examples 🙌🏼 see results below
> Liquid rejects way more than Gemma-4 (530 vs 306 in hard document parsing, 1022 vs 116 in easy road sign detection,… https://twitter.com/mervenoyann/status/2067265735940776285/photo/1
中文: 第2天关于这条管道的发现 🥹
已有效,在针对人类注释的路标检测中获得了 Map@50=0.8028,仅有1.3万个实例🙌🏼 如下所示
液体检测方法比Gemma-4(530 vs 306,简单路标检测1022 vs 116)更拒。


92749 粉丝
RT @ArtificialAnlys: Z ai’s GLM-5.2 is the new leading open weights model on the Artificial Analysis Intelligence Index scoring 51 and it s…
中文: RT @ArtificialAnlys:Z ai 的 GLM-5.2 是人工智能分析智能指数上新领先的开放权重模型,评分为 51 分,且评分为 s...
92749 粉丝
RT @anshuc: Whoa, GLM-5.2 is INSANE for UI/UX with the right prompting. Open models have finally closed the gap.
You have to push it, but…
中文: RT @anshuc:Whaa,GLM-5.2 是 INSANE,适用于 UI/UX,具有正确的提示。开放模型终于缩小了差距。
你必须推它,但......
92749 粉丝
RT @Designarena: BREAKING: GLM-5.2 is now 1st on Design Arena.
With an Elo of 1360, GLM-5.2 has jumped ahead of the now unavailable Claude…
中文: RT @Designarena: Breaking: GLM-5.2 现已在 Design Arena 上排名第一。
凭借1360年的运球,GLM-5.2已领先于现已无法上场的克劳德队。
92749 粉丝
RT @Zai_org: Introducing GLM-5.2: Frontier Intelligence, Open Weights
- Significant improvements in coding and agentic tasks
- Strong long…
中文: RT @Zai_org:推出 GLM-5.2:前沿智能、开放权重
- 编程和代理任务的显著改进
- 长时间强劲......
92749 粉丝
GLM-5.2 is comparable to Opus 4.8 🔥🥵 with 1M context
> new IS attention reuses one indexer every 4 sparse layers (2.9× per-token FLOPs at 1M
> improved MTP layer for spec decoding
> flexible thinking-effort levels
> day-0 in transformers + vLLM + SGLang, MIT license 🤗 https://twitter.com/mervenoyann/status/2066940184977920183/photo/1
中文: GLM-5.2 与 Opus 4.8 🔥🥵 具有 1M 上下文
新增 IS 关注,每 4 个稀疏层重复使用一个 index 层(每个令牌 FLOP 为 1M 的 FLOP 为 2.9 倍
改进的MTP层用于规格解码
灵活的思维努力水平
在变压器中为第0天 + vLLM + 麻省理工学院的SGLang许可证 🤗

92749 粉丝
RT @skalskip92: RF-DETR keypoints is finally out
preview release: real-time transformer keypoint detection
Apache 2.0
71.8 AP on COCO, 9…
中文: RT @skalskip92:RF-DETR 的关键点终于告罅发
预览发布:实时变压器关键点检测
Apache 2.0
71.8 美联社关于 COCO,9 ..
92749 粉丝
RT @onusoz: nvidia/Qwen3.6-35B-A3B-NVFP4 running in vLLM nightly on my Nvidia GB10 is actually insane
50 tok/s, 4 concurrent generations.…
中文: RT @onusoz:nvidia/Qwen3.6-35B-A3B-NVFP4 在我的英伟达GB10上每晚运行实际上太疯狂了
50 个 tok/s,4 代。......
92749 粉丝
this is almost 1-1 same as my local setup!
I use llama server + Pi + Gemma-4 (interchangeably with Qwen3.6)
中文: 这几乎和我当地的设施一样!
我使用 lama 服务器 + Pi + Gemma-4(与 Qwen3.6 互换使用)
92749 粉丝
RT @vboykis: new post: how I develop recently using local models. the tooling is now good enough to do agentic workflows and everyone shoul…
中文: RT @vboykis:新文章:我最近如何使用本地模型进行开发。现在,该工具足以完成智能工作流程,每个人都在进行工作。
92749 粉丝
RT @ben_burtenshaw: we need to get real and move fast about training our own agents. orgs, teams, and individuals all need to be improving…
中文: RT @ben_burtenshaw:我们需要快速提升自身经纪人的训练能力。无论是教练、团队还是个人,都需要不断改进......
92749 粉丝
this is going to be an eventful week in open-source AI, tune in 👀
中文: 这将是开源人工智能中充满宜人的一周,请收听 👀
92749 粉丝
my first finding with this pipeline is that it works well but (rarely) there's a false positive tendency, I don't pass bboxes as tokens but rather overlaid masks/bboxes to judges
when the larger labelling model indicates there's something in the image but it's vaguely there in…
中文: 我发现这个管道的第一个发现是它效果很好,但(很少)存在假阳性倾向,我不会将盒子作为代币,而是将面具或盒子叠加给法官
当较大的标签模型显示图像中存在某些内容时,它却隐约存在......
92749 粉丝
I'm testing multiple small VLMs-as-judges, all parts of pipeline are different model families
let me know below if you want me to test any other models, these are very convenient https://twitter.com/mervenoyann/status/2066544947440861381/photo/1
中文: 我正在测试多个小型VLM-as-judge,管道的所有部分都是不同的模型家族
如果想让我测试其他型号,请在下方告诉我,这些非常方便

92749 粉丝
🚨 breaking 🚨 my core researcher friend from mistral just teased me ‼️
le chaton fat is real?? /s
中文: 🚨 打破[EE]我的核心研究员朋友从错误中转出就逗我了‼
聊天脂肪是真的吗?/s
92749 粉丝
I gave this another round of thinking and I don't get bashing, people appreciate closed model labs while Mistral released a wide range of models open for free (from Voxtral TTS to LLMs, some with Apache 2.0 license)
I guess people just like to bash EU and Mistral comes with it.…
中文: 我又进行了一轮思考,但并不觉得有点不为人接受,人们喜欢封闭式模型实验室,而Mistral则免费发布了多种型号(从Voxtral TTS到LLM,其中一些拥有Apache 2.0许可证)
我猜人们只是喜欢抨击欧盟,而米斯特拉尔也支持它。......
92749 粉丝
my colleague Onur is an openclaw maintainer and an agent whiz who tests open models religiously on coding agents and shares his findings
I suggest to follow him if you're interested!
中文: 我的同事奥努尔是一名开放性维护者,也是一名代理人,他通过编程代理进行宗教测试,并分享他的发现
我建议如果你感兴趣的话,请关注他!
92749 粉丝
icymi I do photography and I love applying various styles with LoRAs and nano banana on them
this scene had to be low poly https://twitter.com/mervenoyann/status/2066111346463138170/photo/1
中文: 我喜欢在LoRA和纳米香蕉上使用各种风格进行摄影
这个场景必须是低聚的


92749 粉丝
even though I don't like European way of doing things I kinda dig Mistral's approach to not build gigantic sota generalists but rather focus on medium sized models + fine-tuning-as-a-service for domains
sovereignty is the way
中文: 尽管我不喜欢欧洲的做事方式,但我会深入探讨米斯特拉尔不是在打造庞大的全体通达人,而是专注于中等规模的模型,而是针对域名进行微调
主权是途径
92749 粉丝
@antirez unlike most people in replies think mistral people really work hard, like I had a former colleague there working 12-15 hours a day, their researchers too
they sell models and finetuning-as-a-service to European companies like banks etc because those companies move slow due to…
中文: @antirez 与大多数回复中的人认为的不太一样,误会的人真的很努力,就像我让一位前同事每天工作12到15个小时一样,他们的研究人员也是如此
他们向银行等欧洲公司销售模型和微调即服务,因为这些公司由于......而进展缓慢
92749 粉丝
RT @ZenMagnets: Alibaba Qwen3.7 slowly fading into irrelevance at the frontier due to proprietary stance.
In it's place we have Minimax M3…
中文: RT @ZenMagnets:由于采用专有立场,阿里巴巴Qwen3.7在前沿领域逐渐逐渐变得无关紧要。
在它的地方,我们有 Minimax M3...
92749 粉丝
RT @mervenoyann: new transformers tutorials just dropped for vision 🔥
🛰️ segmentation on satellite imagery: fine-tune RF-DETR-Seg segment…
中文: RT @mervenoyann:新的变压器教程刚刚因视觉而放弃 🔥
🛰️ 卫星图像细分:精细调谐射频-DETR-Seg 片段......
92749 粉丝
RT @NielsRogge: Kimi K2.7 Code lands between the big boys
Check it out at https://paperswithcode.co/benchmark/mcpatlas?eval=9375 https://twitter.com/NielsRogge/status/2065414135207043339/photo/1
中文: RT @NielsRogge: Kimi K2.7 Code 与大男孩们之间合同
请访问

92749 粉丝
don't walk, run 🙌🏼
llama-server -hf unsloth/MiniMax-M3-GGUF:UD-Q4_K_M
if you're gpu poor like me, start with this 🫡
llama-server -hf unsloth/gemma-4-E2B-it-GGUF:Q8_0
中文: 不走,跑🙌🏼
lama-server -hf unsloth/MiniMax-M3-GGUF:UD-Q4_K_M
如果你像我一样贫穷,那就从这个开始 🫡
lama-server -hf unsloth/gemma-4-E2B-it-GGUF:Q8_0
92749 粉丝
RT @julien_c: Luckily this can never happen https://twitter.com/julien_c/status/2065737492603482421/photo/1
中文: RT @julien_c:幸运的是,这件事永远不会发生

92749 粉丝
just in time there's Minimax M3 and Kimi K2.7 Code
we're blessed by gods of open models
takes one line of code with llama-server
中文: 正值时,M3 和 Kimi K2.7 代码
我们受到开放模式之神的祝福
使用 lama-server 获取一行代码
92749 粉丝
RT @cohere: When you rent your artificial intelligence, you have no control, and no choice. This is why sovereignty and ownership matters.…
中文: RT @cohere:当你租用人工智能时,你别无选择,别无选择。这就是为什么主权和所有权很重要。......
92749 粉丝
vatansever bir insanım fakat ülkede özellikle son olaylardan sonra (hele demokratik ülkelerde yaşayan insanların) hükümetin yapay zeka çalışmalarına katkı sağlamasını anlamıyorum açıkçası
eleştirel düşünebilenlere selam olsun
92749 粉丝
RT @victormustar: Have a great week end (don't forget to touch grass 🍃) https://twitter.com/victormustar/status/2065482087512133826/photo/1
中文: RT @victormustar:周末过得很棒(别忘了触摸草丛🍃)

92749 粉丝
new transformers tutorials just dropped for vision 🔥
🛰️ segmentation on satellite imagery: fine-tune RF-DETR-Seg segment buildings
📱 object detection on mobile UI: fine-tune RF-DETR on screenshots
runs on toaster, converges fast, give to your agent for your use cases🫡 https://twitter.com/mervenoyann/status/2065446109435072957/photo/1
中文: 新的变压器教程刚刚因视觉而放弃🔥
🛰️ 卫星图像细分:精细调谐射频-DETR-Seg 分段建筑
📱 移动用户界面上的对象检测:对屏幕截图的 RF-DETR 进行微调
使用烤面包机,快速收敛,为使用对象提供使用体验🫡

92749 粉丝
RT @Tu7uruu: Happy to announce the launch of the Far-Field ASR Leaderboard! 🎉
While many ASR benchmarks focus on clean speech, real-world…
中文: RT @Tu7urou:很高兴宣布推出远场ASR排行榜!🎉
尽管许多ASR基准侧重于简洁的语音,但现实世界却......
92749 粉丝
RT @julien_c: Explore your @huggingface repos in a whole new way 🔥
Visualize storage, discover outliers, and navigate your repos directly…
中文: RT @julien_c:以一种全新的方式探索你的 @huggingface 仓库 🔥
可视化存储,发现异常值,并直接浏览您的仓库......
92749 粉丝
our book is out 🔥 @andimarafioti @micuelll @orr_zohar
we cover everything from pre/post-training of vision language models to deployment, and even domain-specific applications like document AI or robotics 🫡
printed version will be out soon! 🤗 https://twitter.com/mervenoyann/status/2065358758130102649/photo/1
中文: 我们的书已出版🔥 @andimarafioti @micuell @orr_zohar
我们涵盖从视觉语言模型的预培训到部署,甚至文档AI或机器人等特定领域应用🫡的所有内容
打印版本即将发布!🤗

92749 粉丝
RT @atomic_chat_hq: Atomic Chat is now on Hugging Face 🤗
We're officially a Local App on the world's biggest AI hub. Run 200,000+ open-wei…
中文: RT @atomic_chat_hq:原子聊天现已上线 🤗
我们正式成为全球最大人工智能中心的本地应用。运行20万以上开放-wei...
92749 粉丝
DiffusionGemma is great at tweaking to iterate 🔥 fast ⚡️
watch it generate and tweak a website frontend ⤵️
this is simple but imagine the possibilities 🤯 https://twitter.com/mervenoyann/status/2065014467436351502/video/1
中文: DiffusionGemma 非常擅长快速调整迭代 🔥
观看它生成并调整网站前端 ⤵
这很简单,但可以想象一下可能性🤯
 共 2 项
🎬
视频
92749 粉丝

92749 粉丝
RT @vanstriendaniel: Can @googlegemma DiffusionGemma help fix broken OCR?
In theory, denoising tokens in parallel could work better for OC…
中文: RT @vanstriendaniel:@googlegemma DiffusionGemma 能帮助修复坏坏的OCR吗?
理论上,并行去除代币对OC来说可能更有效......
92749 粉丝
DiffusionGemma is out 🔥
it's compute-bound so 4x faster compared to other Gemma-4 models (1k tok/s on H100) 💨
also great on coding, generate and iterate on any code from 3D generation to front-end ⤵️ https://twitter.com/mervenoyann/status/2064753402064601181/video/1
中文: DiffusionGemma 已退出 🔥
与其他Gemma-4型号(H100上的1k tok/s)相比,其计算速度快了4倍💨
在编程方面也非常出色,可在从3D一代到前端的任何代码上进行生成和迭代⤵️
 共 2 项
🎬
视频
92749 粉丝
@getqonto you have the worst UX ever I have used, I constantly hit issues and need to always connect to human agents only for them to hang up
中文: @getqonto 你拥有我用过的最糟糕的用户体验,我经常出现问题,需要始终与人类经纪人建立联系,才能让他们挂断
92749 粉丝
this didn't age well https://twitter.com/mervenoyann/status/2064431726462480880/photo/1
中文: 这并没有很好地老化

92749 粉丝
RT @nickfrosst: this model is the opposite of mythos.
Its small, cost effective, apache 2.0, and locally deployable. This is the way LLMs…
中文: RT @nickfrost:这个模型与神话恰恰相反。
其小巧、经济高效、Apache 2.0 且可本地部署。这就是LLM的方式......
92749 粉丝
RT @ClementDelangue: Super excited to announce that @arcee_ai is the first major American AI lab to replace AWS S3 with Hugging Face for AL…
中文: RT @ClementDelangue:非常激动地宣布,@arcee_ai 是美国首个将 AWS S3 替换为 AL 的大型人工智能实验室。
92749 粉丝
RT @googlegemma: Introducing the Fast Gemma Challenge with Hugging Face
Over the next few days, dozens of agents will collaborate to make…
中文: RT @googlegemma:推出快速宝石挑战赛
在接下来的几天里,数十名经纪人将合作制作......
92749 粉丝
I have accomplished my life goal of bringing my @huggingface teammates to Istanbul
@pcuenq @SergioPaniego @ariG23498 @ben_burtenshaw @vanstriendaniel @Tu7uruu https://twitter.com/mervenoyann/status/2064369185564602728/photo/1
中文: 我已经完成了将@huggingface队友带到伊斯坦布尔的人生目标
@pcuenq @SergionaPaniego @ariG23498 @ben_burtenshaw @vanstriendaniel @Tu7uru

92749 粉丝
RT @googlegemma: Building super fast experiences with Gemma just got easier.
Gemma 4 MTP is now officially merged into llama.cpp. Develope…
中文: RT @googlegemma:与Gemma合作打造超快体验变得更加简单。
Gemma 4 MTP 现已正式合并为 lamama.cpp。开发......
92749 粉丝
RT @ben_burtenshaw: So excited to be opening up OpenEnv to the whole community. It will now be owned by @huggingface , Meta-PyTorch, @refle…
中文: RT @ben_burtenshaw:非常期待向整个社区开放OpenEnv。现在将由 @huggingface、Meta-PyTorch、@refle 拥有......
92749 粉丝
RT @osanseviero: Gemma 4 MTP just got officially merged into llama.cpp
This means you can use Gemma 4 QAT + MTP for a lightweight + super…
中文: RT @osanseviero:Gemma 4 MTP 刚刚正式合并至 lamama.cpp
这意味着您可以使用 Gemma 4 QAT + MTP 进行轻量级 + 超级...
92749 粉丝
RT @julien_c: Your monthly reminder that HF is much cheaper at scale, for both storage and egress (especially if you use several cloud prov…
中文: RT @julien_c:您的月度提醒,即HF在规模上价格便宜得多,无论是存储还是进步(尤其是如果你使用多个云证明......)
92749 粉丝
this is how @giffmana signs his emails https://twitter.com/mervenoyann/status/2063262072369041770/photo/1
中文: @giffmana 就是这样签署电子邮件的

92749 粉丝
RT @victormustar: Before the week ends, let's acknowledge one of the most INSANE week ever for open AI, with 25+ notable open-weight drops…
中文: RT @victormustar:在本周结束前,让我们确认开放式人工智能领域有史以来最疯狂的一周之一,其中开放重量下降了25个以上......
92749 粉丝
RT @googlegemma: We just dropped Gemma 4 Quantization-Aware Training (QAT) checkpoints on Hugging Face!
All Gemma 4 model sizes and their…
中文: RT @googlegemma:我们刚刚在拥抱面上投放了Gemma 4量化感知训练(QAT)检查点!
所有 Gemma 4 型号及其...
92749 粉丝
I'm working on a bit of a something, here's a spoiler
I learned so much from the process about VLM labelling & judging
currently adding instance segmentation and adding more infra options https://twitter.com/mervenoyann/status/2062918401845026928/photo/1
中文: 我正在做点事情,这里有个剧透
我从关于VLM标签和示例的流程中学到了很多;评判
目前正在添加实例细分并添加更多基础设施选项

92749 粉丝
RT @liquidai: Introducing LFM2.5-VL-1.6B-Extract and LFM2.5-VL-450M-Extract: Vision-language models that return structured JSON, not free-f…
中文: RT @ liquidai:引入 LFM2.5-VL-1.6B 提取和 LFM2.5-VL-450M 提取:用于返回结构化 JSON 的视觉语言模型,而不是 free-f...
92749 粉丝
RT @nathanhabib1011: World models feel like the future... almost... We can still see some weird artifacts.
That means we need high-quality…
中文: RT @nathanhabib1011:世界模特们感觉像是未来......几乎......我们仍然能看到一些奇怪的文物。
这意味着我们需要高质量......
92749 粉丝
RT @googlegemma: Introducing Magenta RealTime 2, a new open model musicians can play as an instrument!
Run low-latency, live music synthes…
中文: RT @googlegemma:推出Magenta RealTime 2,一款全新的开放式音乐模特,可作为乐器演奏!
低延迟的现场音乐合成器......
92749 粉丝
RT @PiotrZelasko: Second big release from us today: Nemotron-3.5-ASR-Streaming!
🌎40 languages
⚡️80ms - 1s controllable latency
🔥240 - 2400…
中文: RT @PiotrZelasko:今日我们发布的第二大版本:Nemotron-3.5-ASR-Streaming!
🌎40 种语言
⚡️80ms - 1s 可控延迟
🔥240 - 2400...
92749 粉丝
RT @julien_c: Today I'm launching a new project called SynthTraces 🔥
It is a minimal codebase to generate synthetic coding agent session t…
中文: RT @julien_c:今天我将启动一个名为 SynthTraces 的新项目 🔥
它是一个用于生成合成编码代理会话的最小代码库。
92749 粉丝
NVIDIA Nemotron Ultra is here 😍
> 55B/550B a hybrid MoE  🦖 with 1M context window
> supports MTP speculative decoding 💨
> day-0 supported in transformers
sits in the most attractive quadrant per performance/efficiency in AA Index 🔥 https://twitter.com/mervenoyann/status/2062526071203938703/photo/1
中文: NVIDIA Nemotron Ultra 已到来 😍
采用55B/550B混合式MoE【EE1】,带1万个窗口
支持MTP投机解码💨
支持“天”式变压器
在AA指数🔥中,每分表现/效率最具吸引力的象限中

92749 粉丝
RT @LeRobotHF: Train AI robots without writing a single line of code. 🤖
We just launched LeLab, the official graphical user interface for…
中文: RT @LeRobotHF:无需编写一行代码即可训练AI机器人。🤖
我们刚刚推出了LeLab,这是用于...的官方图形用户界面
92749 粉丝
just replaced my Qwen3.6 35B 8-bit quant with Gemma 12B bf16 for local coding & Hermes, will report my findings 🙌🏻
中文: 刚刚用Gemma 12B bf16替换了我的Qwen3.6 35B 8位量子点,用于本地编码和编程;Hermes将报告我的发现🙌🏻
92749 粉丝
RT @drfeifei: https://x.com/i/article/2062244283940544512
92749 粉丝
RT @rasbt: It's been a while! 4 nice additions to the open-weight local-LLM-on-consumer-hardware ecosystem: https://twitter.com/rasbt/status/2062235700636873082/photo/1
中文: RT @rasbt:已经有一段时间了!开源本地-LLM-on-Consumer-硬件生态系统的4个不错附加功能:

92749 粉丝
Google dropped Gemma-4 12B, it's a beast 🔥
> unified: audio + image go straight into model, no encoder
> multimodal + tool calling
> dense 12B with 256K context, comes with assistants for MTP (faster!⚡️)
> day-0 in transformers, llama.cpp & MLX
> A2.0 🤗 https://twitter.com/mervenoyann/status/2062214149476683900/photo/1
中文: 谷歌放弃了Gemma-4 12B,这真是个大不前的选择
统一:音频+图像直接进入模型,无编码器
加:多式联运+工具调用
高密度12B,带256K上下文,配备适用于MTP的助手(更快!EE1)
> 日间:变压器、lamama.cpp & MLX
网址:A2.0 🤗

92749 粉丝
RT @victormustar: Reminder: every Hugging Face Space is an API your agents can call :)
I asked mine to build a website about the flowers o…
中文: RT @victormustar:提醒:每个拥抱的人脸空间都是你的代理可以调用的API :)
我让我建立了一个关于花朵的网站......
92749 粉丝
RT @hcompany_ai: Computer-use agents are moving from the cloud to your local machine. Fast.
When we launched Holo3 two months ago, the pro…
中文: RT @hcompany_ai:计算机使用代理正在从云端迁移到本地机器。快。
两个月前我们推出Holo3时,这位专业人士......
92749 粉丝
your AI agent thinks you're lame and I'll prove it
upload your agent traces (CC/Codex/Pi/Claw) to @huggingface and let this app roast you
here's what boss' agent thinks of him @julien_c
share yours below https://twitter.com/mervenoyann/status/2061756306281611607/photo/1
中文: 你的人工智能代理认为你很蹩脚,我来证明
将您的代理线索(CC/Codex/Pi/Claw)上传至@huggingface,让这款应用为您烘焙
老板的经纪人对他的看法是:@julien_c
在下方分享您的内容:

92749 粉丝
everyone's building simple agents
meanwhile IBM is building robust enterprise agents in production, and it's open-source
they just dropped a blog on HF breaking down how to go beyond LLMs & agents: structured reasoning, tool use, and more to scale AI across enterprise https://twitter.com/mervenoyann/status/2061450307523985469/photo/1
中文: 每个人的建筑都是简单的代理
与此同时,IBM正在生产中构建强大的企业代理,并且开源
他们刚刚删除了一篇关于HF的博客,将其分解如何超越LLMs&代理:结构化推理、工具使用等,以在企业范围内扩展人工智能

92749 粉丝
RT @ctnzr: Nemotron 3 Ultra:
Frontier smart.
5X faster.
30% cheaper.
💚💚💚 https://twitter.com/ctnzr/status/2061308138838729121/photo/1
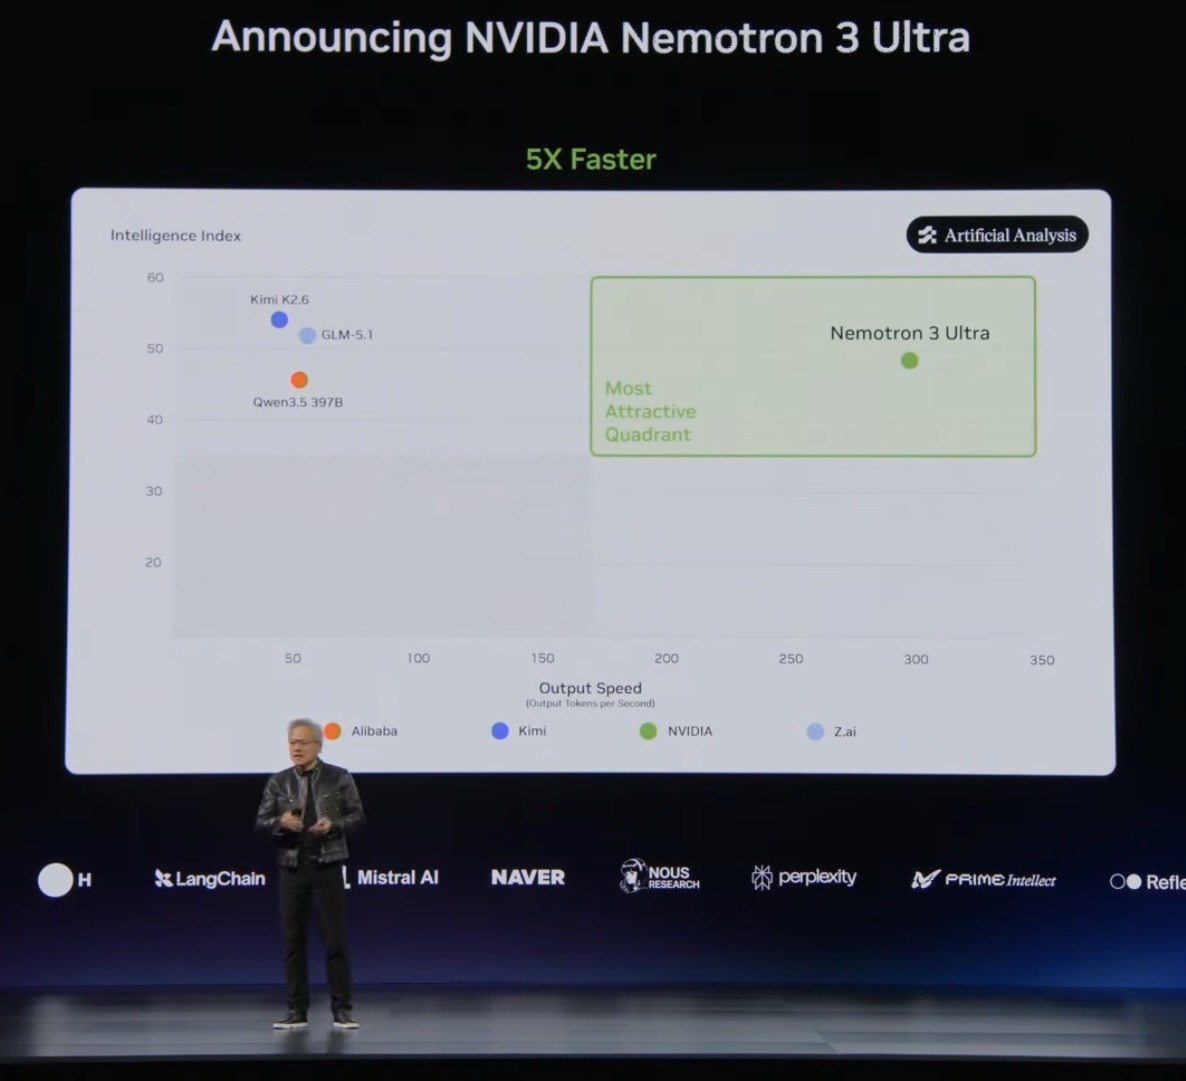
92749 粉丝
NVIDIA just dropped Cosmos 3 at GTC 🔥
closest thing to AGI as world model
> it can reason, understand AND generate videos, images, actions, text
> sota, comes in 16B, 65B, with datasets
> diffusers support 🧨
> open license 🤗
中文: 英伟达刚刚在GTC上退出了Cosmos 3 🔥
最接近AGI作为世界模型
它能够推理、理解并生成视频、图像、操作和文字
数据集(Sota)提供16B、65B、数据集
支持扩散器 🧨
开放许可证 🤗
92749 粉丝
RT @NVIDIAAI: This #CVPR2026 paper from our research team is trending #1 on @HuggingFace 🤗
Meet LocateAnything: a vision-language detectio…
中文: RT @NVIDIAAI:我们研究团队的这篇#CVPR2026论文在@HuggingFace上排名第一🤗
认识 查找一切:视觉语言检测...
92749 粉丝
RT @fangfu0830: 🔥 We release Gamma-World from @nvidia — a generative multi-agent world model that finally goes beyond 2 players.
⚡ 24 FPS r…
中文: RT @fangfu0830:🔥 我们从 @nvidia 发布 Gamma-World——一个生成式多代理世界模型,最终超越了两名玩家。
⚡ 24 FPS r...
92749 粉丝
RT @julien_c: We are starting to be quite bullish about getting in the data infrastructure business.
I just cloned 68 TB (while I only hav…
中文: RT @julien_c:我们开始对进入数据基础设施业务持相当乐观的态度。
我刚克隆了68TB(而我只有......
92749 粉丝
RT @liquidai: Today, we're releasing LFM2.5-8B-A1B, a device-optimized model designed to power real-life applications on phones, laptops, P…
中文: RT @ liquidai:今天,我们将推出LFM2.5-8B-A1B,这是一款专为手机、笔记本电脑和P...上实际应用供电而设计的设备优化型型。
92749 粉丝
RT @skalskip92: RF-DETR is now available in @huggingface transformers
state of the art in both detection and segmentation, outperforming Y…
中文: RT @skalskip92:RF-DETR 现已在 @huggingface 变压器中提供
在检测和细分领域都处于技术状态,表现优于
92749 粉丝
RF-DETR just landed to @huggingface transformers 🥵🔥
sota real-time detection & segmentation models by @roboflow 💜
> play with our real-time demo
> fine-tune the models on your use case with our tutorials (takes a toaster's VRAM)
> or just hand them to your agents 😄 https://twitter.com/mervenoyann/status/2059647988373373253/video/1
中文: RF-DETR 刚刚登陆至 @huggingface 变压器 🥵🔥
实时检测与实时检测;由 @roboflow 进行细分模型 💜
玩我们的实时演示
使用我们的教程(请使用烤面包机的VRAM),为您的使用用箱中的型号进行精细调整
或将它们交给您的代理公司 😄
 共 2 项
🎬
视频
92749 粉丝
RT @victormustar: cool new release: a tiny open video VLM that understands what happens in videos and when 👀
Marlin-2B (Apache 2.0!) can c…
中文: RT @victormustar:酷炫的新发布:一段微小的开放视频,可了解视频中的情况以及👀
马林-2B(Apache 2.0!)可以......
92749 粉丝
RT @victormustar: Made a free Pixal3D demo (Tencent's new image-to-3D model) because I like it a lot 🔥
What's interesting: pixel-aligned g…
中文: RT @victormustar:免费制作一个Pixal3D演示版(腾讯全新图像到3D模式),因为我非常喜欢它🔥
有趣的是:像素对齐的 g...
92749 粉丝
Cohere dropped Command A+ 🔥
> 25B/219B MoE vision language model
> supports 48 languages with efficient tokenizer
> tool-calling/agentic + 128k context window
> transformers day-0 support 🤗
free license 💗 https://twitter.com/mervenoyann/status/2057128432190787643/photo/1
中文: 科赫雷放弃了命令A+ 🔥
25B/219B 视觉语言模型
支持48种语言,支持高效的令牌化
工具调用/代理 + 1.28k 上下文窗口
支持:>变压器 日间支持 🤗
免费许可证 💗

92749 粉丝
RT @victormustar: it's open source time, with a real leap for world models 🎉
NVIDIA's SANA-WM: a camera-conditioned world model that fits…
中文: RT @victormustar:现在是开源时间,世界模特们确实实现了飞跃🎉
NVIDIA 的 SANA-WM:一款符合相机条件的世界型号,适合......
92749 粉丝
RT @victormustar: llama.cpp with MTP support makes local models fast enough to use as daily drivers 🚀
Qwen3.6-27B dense generation (on A10…
中文: RT @victormustar:支持MTP的 llama.cpp 使本地车型速度足够快,能够作为日常驾驶者使用 🚀
Qwen3.6-27B 密度生成(在 A10 上)
92749 粉丝
finally faster Qwen3.6 models with MTP support ⚡️
brb updating my Pi & Hermes setup 🤝
中文: 支持MTP的Qwen3.6型号速度更快⚡️
更新我的Pi & Hermes 设置 🤝
92749 粉丝
RT @ben_burtenshaw: if you're doing RL on agent use cases, check out this video.
agents might seem like the most obvious application of p…
中文: RT @ben_burtenshaw:如果你在代理使用情况下使用RL,请观看此视频。
代理可能看起来像是p...最明显的应用
92749 粉丝
RT @MaziyarPanahi: Arabic. Japanese. Turkish. Redacting clinical discharge summaries in real-time.
30+ new open-source PII models shipped…
中文: RT @MaziyarPanahi:阿拉伯语。日语。土耳其语。实时编辑临床出院摘要。
30 个以上新的开源 PII 型号已发布...
92749 粉丝
reason why self-improving personal agents (Claw, Hermes) are hyped is due to how people actually like the idea but they just never try it, so all they do is to yap because it gets engagements
quite sad. on the contrast I really find them useful
中文: 自我改进的个人代理人(克劳,爱马仕)之所以被大肆宣传,是因为人们其实对这个想法很喜欢,但他们从不尝试,所以他们所做的只是努力,因为会进行互动
非常难过。从对比上来说,我确实觉得它们很有用
92749 粉丝
TIL Hermes Agent has optional skills for.. *checks notes* tokenizers and accelerate? 😄
joke aside it also has a peft and trl which can really be useful https://twitter.com/mervenoyann/status/2056102443830677874/photo/1
中文: TIL Hermes Agent 具备可选技能,可选择 . . * 勾选笔记* 标记器并加速?😄
开玩笑说,它还具有一种 peft 和 trl 功能,这确实很有用

92749 粉丝
I finally got the tattoo @huggingface https://twitter.com/mervenoyann/status/2055302977158607211/photo/1
中文: 我终于得到了纹身 @huggingface
92749 粉丝
RT @onusoz: People were asking at @clawcon singapore how to setup eg. gemma with OpenClaw, and I realize for some time that there is no eas…
中文: RT @onusoz:人们在@clawcon singapore 询问如何使用 OpenClaw 来设置 eg. gemma,我已意识到一段时间以下没有这个问题......
92749 粉丝
this week @huggingface crossed 1M datasets 🚀 every open model you love was built on top of them
next objective: more open coding session traces on Hub to push coding models even further 🤝
help push the open frontier by uploading your traces! https://twitter.com/mervenoyann/status/2054891459053039938/photo/1
中文: 本周,@huggingface 跨越了 1M 数据集 🚀 你所热爱的每一个开放模型都建立在它们之上
下一个目标:在Hub上进行更多开放编码会话,以进一步推动编码模型 🤝
上传你的痕迹,帮助突破开阔的前沿!
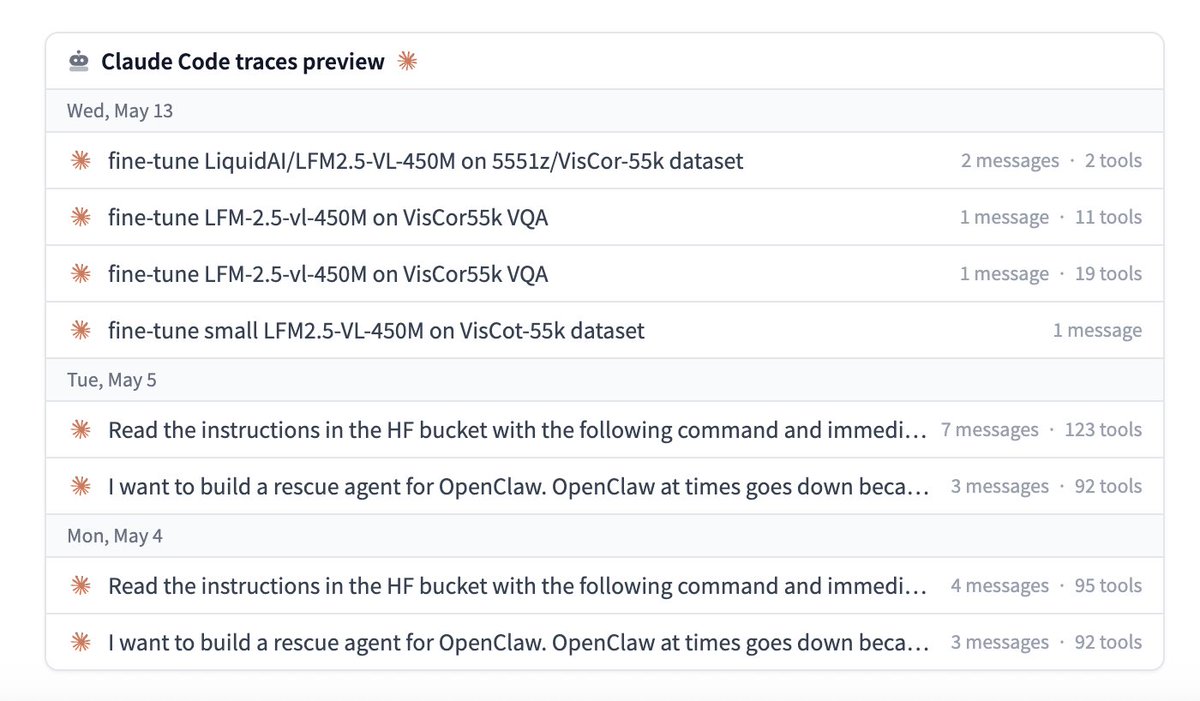
92749 粉丝
RT @aiDotEngineer: Your Agent Can Now Train Models
The argument from @mervenoyann: open source models have caught up. GLM 5.1 is leading t…
中文: RT @aiDotEngineer:您的代理现在可以训练模型
@mervenoyann:开源模型的争论已经追上来。GLM 5.1 处于领先地位......
92749 粉丝
RT @_lewtun: You can now have an AI researcher running on your laptop 24/7 for free!
Running Qwen3-35B-A3B with llama.cpp and a 4-bit qua…
中文: RT @_lewtun:现在你可以免费让一台人工智能研究人员在笔记本电脑上免费运行!
使用 lama.cpp 和 4 位 qua 运行 Qwen3-35B-A3B ...
92749 粉丝
RT @JulienBlanchon: I'm releasing OpenCS2 a 11TB dataset of around 5000 hours of counter strike gameplay recording.
- HD resolution - 1280…
中文: RT @JulienBlanchon:我将发布 OpenCS2 一个包含约 5000 小时反击游戏记录的 11TB 数据集。
- 高清分辨率 - 1280...
92749 粉丝
look mom I'm on my favorite YT channel this evening @aiDotEngineer 💗
I talked about how @huggingface meets your agent: you can ask your agent to do all ML workflows from training models to label data now https://twitter.com/mervenoyann/status/2054496147914252394/photo/1
中文: 看妈妈,今晚我在我最喜欢的YT频道上 @aiDotEngineer 💗
我谈到了@huggingface 如何与你的经纪人见面:你可以要求你的代理完成从训练模型到标注数据的所有机器学习工作流程,现在
92749 粉丝
RT @sergeynazarovx: We used to go to a special website, ask strangers for help with programming, and get humiliated in return https://t.co/…
中文: RT @sergeynazarovx:我们过去常常访问一个特别网站,向陌生人求助编程,并会遭受羞辱,
92749 粉丝
RT @huggingface: We've just hit 1M open datasets on the Hugging Face Hub 🎉
Open models need open data. Today we hit that milestone, togeth…
中文: RT @huggingface:我们刚刚在“拥抱”面部中心(EE0)上点击了100万个开放数据集
开放模型需要开放数据。今天我们达到了那个里程碑,图集......
92749 粉丝
Meta silently dropped Sapiens2 last week 🔥
a family of high-res models trained on 1B human images
> for pose estimation, body-part segmentation, surface normals, pointmaps (sota)
> 6 sizes: 0.1B → 5B params (all ViT patch 16)
> high-res: 1024×768 and 4K https://twitter.com/mervenoyann/status/2054187884417102319/video/1
中文: Meta上周悄然放弃了Sapiens2 🔥
一个基于1B张人类图像训练的高分辨率模型家族
>用于姿势估计、身体与身体分割、表面正常、点图(sota)
6 种尺寸:0.1B → 5B 参数(所有 ViT 补丁 16)
高空:1024×768 和 4K
 共 2 项
🎬
视频
92749 粉丝
this project uses entire @huggingface infra to build agentic medical intelligence 🔥
signup for preview ⤵️
中文: 该项目使用整个 @huggingface infra 来构建特化医疗智能 🔥
注册预览 ⤵️
92749 粉丝
MiniCPM-V-4.6 is in 🔥
> 1B (SigLIP2-400M + Qwen3.5-0.8B)
> beats Qwen3.5-0.8B on AA with 19x fewer tokens
> beats other larger small VLMs
> deploy to iOS + Android with GGUF and other quants https://twitter.com/mervenoyann/status/2053912404774248895/photo/1
中文: miniCPM-V-4.6 已登录 🔥
1B(SigLIP2-400M + Qwen3.5-0.8B)
在AA上以19倍的代币数量击败Qwen3.5-0.8B
比其他较大的小型VLM更胜一负
与GGUF及其他量子点一起部署到iOS+安卓系统

92749 粉丝
RT @victormustar: This feature is quite cool to run Hermes Agent locally because:
- You can filter on the +60k models compatible with Herme…
中文: RT @victormustar:此功能在本地运行 Hermes Agent 非常酷,因为:
- 您可以筛选与 Herme 兼容的 +60k 型号...
92749 粉丝
🆕 Hugging Face 🤝 Hermes Agent 🔥
> we added Hermes Agent to local apps: run it locally with any compatible GGUF/MLX model
> shipped native traces support for Hermes Agent: visualize your Hermes traces directly on the Hub
Very soon most agents will run locally and we want to… https://twitter.com/mervenoyann/status/2053857347429151163/photo/1
中文: 🆕 拥抱面容 🤝 爱马仕探员 🔥
我们已将 Hermes Agent 添加到本地应用程序中:使用任何兼容的 GGUF/MLX 型号本地运行
已发货的Hermes Agent原生痕迹支持:直接在Hub上直观显示您的Hermes痕迹
很快大多数代理人员将在当地运营,我们希望......
92749 粉丝
RT @onusoz: I have a new job!
Excited to announce that I will be working with Hugging Face to make local models work great in OpenClaw and…
中文: RT @onusoz:我有一份新工作!
很高兴宣布,我将与Hugging Face合作,让本地模特在OpenClaw和...上大有作为
92749 粉丝
RT @victormustar: Exciting: local ML is (finally) going mainstream 🔥
- new GGUF uploads on HF nearly doubled in 2 months
- smaller models…
中文: RT @victormustar:令人兴奋:本地机器学习(终于)成为主流了 🔥
- HF 上新增 GGUF 上传量在两个月内几乎翻倍
- 更小的模型......
92749 粉丝
RT @nathanhabib1011: 🦞 Claw-Eval 🦞
🥇 @XiaomiMiMo's MiMo-V2.5-Pro at 1T
🥈 @Zai_org GLM5.1 at 754B
🥉 @XiaomiMiMo MiMo-V2.5 at 310B
Congrats…
中文: RT @nathanhabib1011:🦞 爪子-埃瓦尔 🦞
🥇 @XiaomiMiMo 的 MiMo-V2.5-Pro 1T
🥈 @Zai_org GLM5.1 at 754B
🥉 @XiaomiMiMo MiMo-V2.5,310B
恭喜......
92749 粉丝
Istanbul Open-source AI meet-up @huggingface was 🔥
we had many stories from building in-house models cutting costs to agentic apps 🙌🏼
many thanks @trendyoltech @nsrt_py @anil_ozturkk for hosting us 🤗 https://twitter.com/mervenoyann/status/2053447237364002877/photo/1
中文: 伊斯坦布尔开源人工智能会议 @huggingface 是 🔥
我们从打造内部模型,向代理应用程序降低成本,经历了许多故事🙌🏼
非常感谢@trendyoltech @nsrt_py @anil_ozturkk 为我们提供的接待 🤗



92749 粉丝
RT @ben_burtenshaw: PSA: If you put your blood, sweat, and tears into a custom model for your use case on OpenAI, make sure you get the wei…
中文: RT @ben_burtenshaw:PSA:如果你在 OpenAI 上为使用案例定制了血、汗和泪,请务必使用 wei...
92749 粉丝
read our response here https://x.com/mervenoyann/status/2052752660537676198?s=46 I wish journalists can do better in the future wrt avoiding baiting
中文: 请在此处阅读我们的回复: 我希望记者们未来能做得更好,以免被诱骗
92749 粉丝
RT @AnthropicAI: New Anthropic research: Natural Language Autoencoders.
Models like Claude talk in words but think in numbers. The numbers…
中文: RT @AnthropicAI:新人类研究:自然语言自动编码器。
像克劳德这样的模特会用言语说话,但会用数字来思考。数字......
92749 粉丝
people don't even read articles these days and jump in to conclusions 👀
中文: 如今人们甚至不会阅读文章,而是贸然得出结论👀
92749 粉丝
RT @adithya_s_k: Excited to release the Ultimate guide to RL environments!
Definitions of RL environments differ wildly in the LLM era, so…
中文: RT @adithya_s_k:很高兴发布RL环境终极指南!
在LLM时代,RL环境的定义差异很大,因此......
92749 粉丝
RT @Tu7uruu: Big announcement for speech AI
Benchmarks get gamed. So we added a repellent.
The Open ASR Leaderboard now includes private…
中文: RT @Tu7ruu:语音AI发布重要公告
基准会被游戏。于是我们加了个驱人者。
开放的ASR排行榜现在包含私有...
92749 粉丝
RT @pcuenq: transformers v5.8.0 is here, and it's a biggie 🚀
Three massive model additions:
🐳 DeepSeek-V4: next-gen efficient MoE
🪨 Granit…
中文: RT @pcuenq:变压器 v5.8.0 到来,这很大🚀
三个庞大的模型新增功能:
🐳 DeepSeek-V4:下一代高效 MOE
🪨 格拉尼特......
92749 粉丝
Gemma 4 just got a massive speed-up with MTP drafters ⚡️
> speculative decoding (up to 3x tokens/sec improvement compared to normal Gemma-4 🔥)
> identical reasoning, just faster
> day-0 support in transformers, MLX, vLLM
> A2.0 licensed 🤗 https://twitter.com/mervenoyann/status/2051702372339003841/photo/1
中文: 杰玛4队刚刚凭借MTP选秀者迅速加速上场⚡
>推测性解码(与正常的Gemma-4相比,可提高3倍的代币/秒量🔥)
相同的推理,速度更快
支持 > 用于变压器、MLX、vLLM 的 Day-0
获得A2.0授权🤗

92749 粉丝
RT @osanseviero: Excited to introduce Gemma 4 Multi-Token Prediction Drafters⚡️Accelerated inference right in your pockets
- Up to a 3x sp…
中文: RT @osanseviero:很高兴能在口袋里直接引入Gemma 4多代币预测绘图员⚡️
- 最高可达3倍 sp...
92749 粉丝
RT @ben_burtenshaw: Introducing the context course: a free course on doing ML with agent context.
You will learn how to train models, opti…
中文: RT @ben_burtenshaw:介绍上下文课程:一门关于使用代理语境进行机器学习的免费课程。
您将学习如何训练模型,选择......
92749 粉丝
I forked openclaw to build a small local rescue agent that debugs whenever the agent is down
in just half an hour my fork was behind 15 commits
insane pace
中文: 我把openclaw分叉来构建一个小型本地救援代理,每当代理人员倒下时都会进行调试
在短短半小时内,我的分叉就落后于15个提交
疯狂的步伐
92749 粉丝
RT @victormustar: honestly Granite 4.1 8b might be the best model to run at this size
https://huggingface.co/blog/ibm-granite/granite-4-1
中文: RT @victormustar:老实说,Granite 4.1 8b 可能是这个尺寸的最佳型号
92749 粉丝
gpt-5.5-extra-high-as-a-kite
中文: gpt 5.5-ext-high-a-kite
92749 粉丝
RT @0xSero: Weekly best models for your hardware:
~~ 8 to 16gb ~~
Granite models are amazing: [NEW]
- https://huggingface.co/ibm-granite/granite-4.1-8b
Gemma-E4B…
中文: RT @0xSero:每周最适合您硬件的型号:
~8到16克~~
花岗岩模型令人惊叹:[新]
-
杰玛-E4B...
92749 粉丝
İstanbul'da buluşalım, konuşmacı ya da katılımcı olmak isterseniz başvurular aşağıda 🙌🏼
92749 粉丝
RT @nsrt_py: Herkese selamlar! Hugging Face ile ilk etkinliğimiz olan "Open-source AI Meet-up with Hugging Face" 9 Mayıs saat 13:00'da Tren…
92749 粉丝
RT @Tu7uruu: IBM just dropped TWO new open ASR models with very strong performance!
> ~5.3 WER on Open ASR leaderboard (strong accuracy fo…
中文: RT @Tu7ruu:IBM刚刚推出了两款新的开放式ASR机型,性能非常出色!
在Open ASR排行榜上表现出色(准确性极强)
92749 粉丝
RT @alvarobartt: IBM Granite just released two multilingual embedding models with 97M and 311M parameters 🤏🏻
ModernBERT-based, 200+ langua…
中文: RT @alvarobartt:IBM Granite 刚刚发布了两个多语言嵌入模型,参数为 97M 和 311M [EE]
总部位于现代伯特,200岁以上...
92749 粉丝
nvidia cooked 😍 nemotron-3-nano-omni all modalities LLM 🔥
• 30B-A3B MoE hybrid Mamba-Transformer
• 9x throughput vs other open omni models
• native audio (1200s), long video, 100+ page docs in single turn
• agentic CUA built in
• BF16 / FP8 / NVFP4 https://twitter.com/mervenoyann/status/2049216818150015255/photo/1
中文: nvidia 已烹饪😍 nemotron-3-nano-omni 所有模式 LLM 🔥
• 30B-A3B MoE 混合型 Mamba-Transformer
• 与其他开放式全系统模型相比,吞吐量为9倍
• 原生音频(1200年代),长视频,100多页单折
• 内置的代理 CUA
• BF16 / FP8 / NVFP4
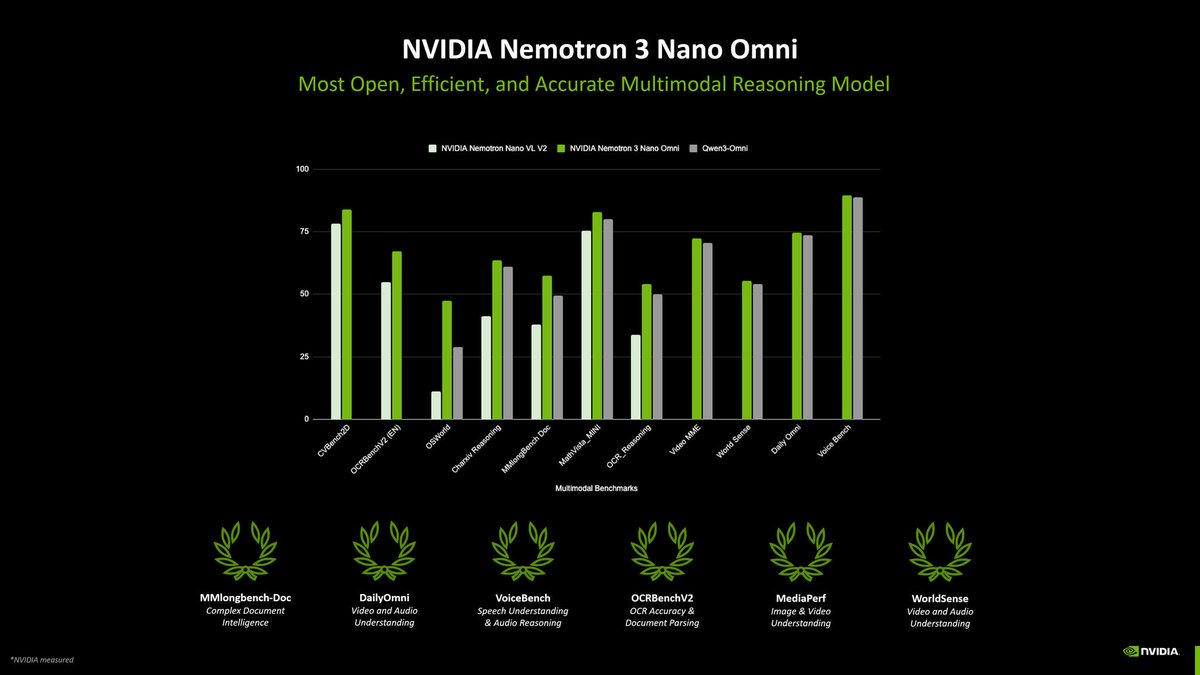
92749 粉丝
nvidia cooked 😍 nemotron-3-nano-omni all modalities LLM 🔥
• 30B-A3B MoE hybrid Mamba-Transformer
• 9x throughput vs other open omni models
• native audio (1200s), long video, 100+ page docs in single turn
• agentic CUA built in
• BF16 / FP8 / NVFP4
中文: nvidia 已烹煮 😍 - nemotron-3-nano-omni 所有模式 LLM 🔥
• 30B-A3B MoE 混合型 Mamba-Transformer
• 与其他开放式全系统模型相比,吞吐量为9倍
• 原生音频(1200年代),长视频,100多页单折
• 内置的代理 CUA
• BF16 / FP8 / NVFP4
92749 粉丝
any-to-any model based on Nemotron 3 Nano 🔥
中文: 基于 Nemotron 3 Nano 🔥 的任何型号
92749 粉丝
we compile all the best benchmarks and model results
so agents can find the best model for fine-tuning and inference for your hardware budget
turns out it was a "skill" issue
中文: 我们编制所有最佳基准和模型结果
以便代理为您的硬件预算找到最佳的微调和推理模型
事实证明这是一个“技能”问题
92749 粉丝
RT @ben_burtenshaw: Humanity's Last Hackathon is NOW OPEN for registration.
This is not a normal hackathon. You will be judged on the cont…
中文: RT @ben_burtenshaw:Humanity's Last Hackathon 现已开放注册。
这并非一场普通的黑客马拉松。你将在比赛中受到评判......
92749 粉丝
RT @LysandreJik: I've been trying to make transformers more agent-friendly: agentic CLI, a skill, doc rewrites, canonical examples.
It fe…
中文: RT @LysandreJik:我一直试图让变压器更环保:一种技术技能,文档重写,以规范为例。
这......
92749 粉丝
beauty of open-sourcing powerful models & datasets 😍
中文: 开源强大模型的美观;数据集 😍
92749 粉丝
learn how to use, fine-tune, optimize and deploy bleeding edge audio models 🙌🏼
中文: 学习如何使用、微调、优化和部署出血边缘音频模型 🙌🏼
92749 粉丝
RT @TencentHunyuan: 👋Hi /haɪ/, we're the Tencent Hy /haɪ/ team🐧
Today, we open source Hy3 preview (295B A21B), a leading reasoning and age…
中文: RT @TencentHunyeuan:👋 Hi /haɪ/,我们是腾讯 Hy /haɪ/ 团队🐧
今天,我们开源 Hy3 预览版(295B A21B),这是一个领先的推理和年龄......
92749 粉丝
stop spending money for your openclaw agent's memory search 💸
use local models on @huggingface with llama.cpp instead
I use quantized Embedding Gemma @googlegemma, it can run on anything https://twitter.com/mervenoyann/status/2048724071936880697/photo/1
中文: 停止为你的开放小卡代理的内存搜索花钱 💸
使用 @huggingface 与 lalama.cpp 一起使用本地模型
我使用量子化嵌入Gemma @googlegemma,它可以在任何平台上运行

92749 粉丝
I have just crossed 10K friends on @huggingface 🤗💗
I try to make myself more and more useful for community and am always happy to be of service 🫡 https://twitter.com/mervenoyann/status/2048680605206856091/photo/1
中文: 我刚刚在@huggingface上结识了10K个朋友🤗💗
我努力让自己对社区越来越有用,并且总是乐于服务🫡

92749 粉丝
it's only 48 hours:
- Qwen3.6-27B
- Tencent-Hy3-preview
- DeepSeekv4
what's next? 👀
中文: 只有48小时:
- Qwen3.6-27B
- 腾讯-海伊3-预览
- 深度深度
接下来会发生什么?👀
92749 粉丝
RT @julien_c: This is where we are right now. And i’m not gonna lie it feels pretty magical 🧚♀️
Qwen3.6 27B running inside of Pi coding a…
中文: RT @julien_c:我们目前所处的位置。我不会撒谎,感觉相当神奇🧚 ♀️
运行在Pi编程内的Qwen3.6 27B...
92749 粉丝
read this deep dive from Ben on DSv4 release today ⬇️
中文: 今天在DSv4上阅读本的深度阅读⬇️
92749 粉丝
if you were in a cave, DeepSeek v4 is out, and it's groundbreaking, here's why:
it's the first open model to have solved long context: your agentic setup (OpenClaw, coding agents) need many agents, hybrid attention by DSv4 compresses KV-cache, allowing more overhead memory
on…
中文: 如果你在洞穴里,DeepSeek v4 已经出局,而且具有开创性,原因就是:
这是首个解决长上下文的开放式模型:您的代理设置(OpenClaw、编码代理)需要多种代理,而 DSv4 的混合注意力则压缩了 KV 缓存,从而实现了更多的管理内存
上......
92749 粉丝
RT @ben_burtenshaw: deepseek-v4 is out and solves context rot at 1M tokens by taking on attention for the kv cache.
It's big at 1T Params…
中文: RT @ben_burtenshaw: deepseek-v4 已经退出,通过关注 kv 缓存,解决 1M 代币的上下文问题。
在1T Params上很大......
92749 粉丝
DSv4 genuinely shines in 1M context window and peak efficiency to run many agents/users 😍
shortly coming to transformers and we're making sure you get all the peak efficiency 🔥 @art_zucker https://twitter.com/mervenoyann/status/2047568003093471283/photo/1
中文: DSv4 在 1M 环境窗口中真正大放异彩,并实现高效运行,可运行多种代理/用户 😍
即将进入变压器,我们确保获得所有最高能效 [EE] @art_zucker
92749 粉丝
DeepSeek v4 is out with 1M context window 🥵🔥
> Pro (13B/284B) & Flash (49B/1.6T)
> hybrid attention, needs 27% flops & 10% kv cache compared to V3.2
> reasoning effort: non-think, think high, think max
> MIT licensed 💗 https://twitter.com/mervenoyann/status/2047547789601595772/photo/1
中文: DeepSeek v4 已关闭,具有 1M 上下文窗口 🥵🔥
>专业(13B/284B)和快速;闪光灯(49B/1.6T)
混合注意力,需要27%的空转;与V3.2相比,缓存为10%
推理能力:不思考,高思考,最大思考
麻省理工学院持牌💗

92749 粉丝
RT @deepseek_ai: 🚀 DeepSeek-V4 Preview is officially live & open-sourced! Welcome to the era of cost-effective 1M context length.
🔹 DeepSe…
中文: RT @deepseek_ai:🚀 DeepSeek-V4 预览版正式上线,即开源!欢迎来到具有成本效益的1M环境长度时代。
🔹 深度......
92749 粉丝
RT @gabriberton: I miss ConvNets
Much simpler and more intuitive than transformers
Early layers would always converge to the same feature…
中文: RT @gabrierton:我想念ConvNets
比变压器简单得多,也更直观
早期层次总能汇聚到相同的特征上......
92749 粉丝
OpenAI just released Privacy Filter
> multilingual PII redaction with 128k context window 🤯 only 1B params
> fine-tunable
> redact variety of things: including emails, address, names, secrets (best for platform/agent logs)
> transformers & ONNX weights 🤗 https://twitter.com/mervenoyann/status/2046980302002602473/photo/1
中文: OpenAI 刚刚发布了隐私筛选器
附加语言PII编辑,包含128k个上下文窗口🤯,仅支持1B参数
可调和
删减多种内容:包括电子邮件、地址、姓名、秘密(最适合平台/代理日志)
设备:变压器和放大器;ONNX 重量 🤗
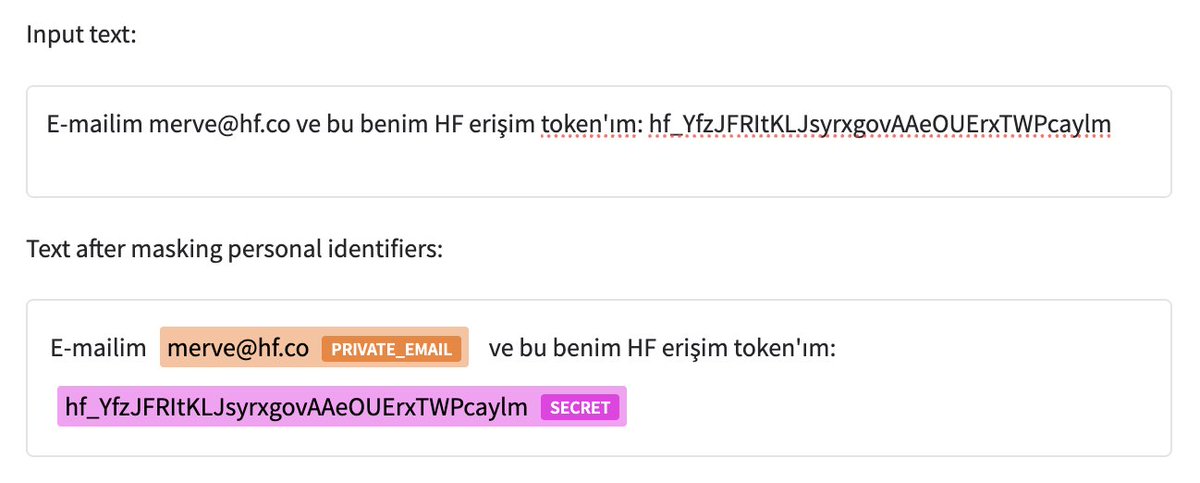
92749 粉丝
RT @Alibaba_Qwen: 🚀 Meet Qwen3.6-27B, our latest dense, open-source model, packing flagship-level coding power!
Yes, 27B, and Qwen3.6-27B…
中文: RT @Alibaba_Qwen:🚀 与Qwen3.6-27B会面,这是我们最新的密集开源机型,采用旗舰级编程功能!
是的,27B,Qwen3.6-27B...
92749 粉丝
RT @stevibe: Which LLMs actually love to think?
Tested 7 models on 5 math problems, measured reasoning length.
The think winners: both Qw…
中文: RT @stevibe:哪些LLMs真的喜欢思考?
测试了7个关于5个数学问题的模型,测量了推理长度。
获胜的思想家:两者兼有......
92749 粉丝
RT @googlegemma: What does it take to run 3, 5, or even 10 concurrent instances of Gemma 4 locally?
We've open-sourced a demo letting you…
中文: RT @googlegemma:在本地运行3、5甚至10个并发的Gemma 4实例需要什么?
我们开源了一个演示,让你......
92749 粉丝
RT @akseljoonas: Introducing ml-intern, the agent that just automated the post-training team @huggingface
It's an open-source implementati…
中文: RT @akseljoonas:介绍 mls-intern,这位刚刚将训练后团队自动化的代理人 @huggingface
这是一个开源的实现......
92749 粉丝
bad thing about having your OC agent on local model is having to maintain your mlx/llama-server
but also even by then it sometimes goes down and it's not the llama server
does anyone have any tips https://twitter.com/mervenoyann/status/2046620360351613187/photo/1
中文: 让你的OC代理使用本地模型,就是必须维护你的mlx/llama-服务器
但即便如此,它有时也会下降,而它并非“骆驼”服务器
有谁有建议吗

92749 粉丝
RT @ben_burtenshaw: 2 days until we will hold this deep dive workshop on everything RL for agents with some of the best names in the game.…
中文: RT @ben_burtenshaw:距离我们举办本次深潜研讨会前,将为拥有游戏中一些最知名球员的经纪人提供所有RL课程。......
92749 粉丝
no shade but I hope one day god gives me the confidence of an average random AI strategy/innovation person on LI
中文: 没有遮阳,但希望有一天,上帝能让我在LI上给出一个普通的随机人工智能策略/创新人的自信
92749 粉丝
kimi k2.6 is out: open source coding sota 🔥
> 32B/1T MoE with 256k context
> long horizon coding + better website design
> most interesting: agent swarms (300 subagents can do 4k steps) & Claw groups (multiple self improving agents) https://twitter.com/mervenoyann/status/2046254380102373739/photo/1
中文: kimi k2.6 已发布:开源编码 sota 🔥
加法;32B/1T 闺號 带 256k 上下文
> 长地平线编程 + 更完善的网站设计
最有趣的是:代理群(300 个亚中介可以完成 4K 步骤)和 草皮组(多个自我提升代理)
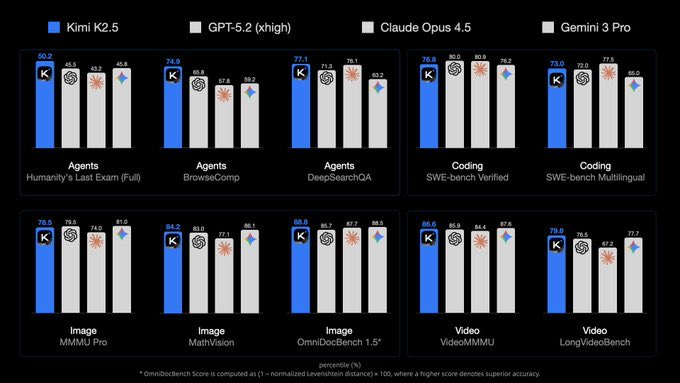
92749 粉丝
RT @Kimi_Moonshot: Meet Kimi K2.6: Advancing Open-Source Coding
🔹Open-source SOTA on HLE w/ tools (54.0), SWE-Bench Pro (58.6), SWE-bench…
中文: RT @Kimi_Moonshot:认识 Kimi K2.6:推进开源编码
🔹 开源SOTA与HLE的工具(54.0)、SWE-Bench Pro(58.6)、SWE-bench...
92749 粉丝
this model is an underrated gem and the results are very strong 🙌🏼
中文: 这个模型是一颗被低估的宝石,结果非常强劲🙌🏼
92749 粉丝
RT @LysandreJik: We're opening a Hugging Face office in Tokyo!
Our goal: help open-source AI develop in Japan and grow the local communit…
92749 粉丝
RT @NielsRogge: We've added support for SAM-3 Lite-Text in the Transformers library! 🔥
> replaces the heavy text encoder in SAM-3 with a c…
中文: RT @NielsRogge:我们已在 Transformers 库中添加了对 SAM-3 Lite-Text 的支持!🔥
将 SAM-3 中的重文本编码器替换为 c...
92749 粉丝
RT @stevibe: Which local models can actually handle tool calling?
I built a framework to find out.
15 scenarios. 12 tools. Mocked respons…
中文: RT @stevibe:哪些本地模型实际上可以处理工具调用?
我建立了一个框架来查明事实。
15个场景。12个工具。模拟反应......
92749 粉丝
RT @onusoz: Who is running local models on GPUs on OpenClaw?
I have started benchmarking different models this week. I am working on impro…
中文: RT @onusoz:谁在 OpenClaw 上使用 GPU 运行本地模型?
我本周开始对不同模型进行基准测试。我正在做 impro 的工作......
92749 粉丝
tried my openclaw intern with various open models recently, currently using Qwen3.6 with Q6_K
vibe: GLM-5 and Minimax sounded a bit more witty and friendly whereas Qwen seems to forget the character a bit
Q6_K without reasoning is still surprisingly accurate though
中文: 最近,我试用了各种开放式型号的 openclaw 实习生,目前使用 Qwen3.6 和 Q6_K
氛围:GLM-5和Minimax听起来更幽默、更友善,而Qwen似乎有点忘记了这个角色
毫无理由仍然出人意料地准确
92749 粉丝
if you're using Replit, Antigravity or other vibe-building tools 👋🏻
simply adding @huggingface Skills to your setup gives your agent access to ~3M open models, 500k+ local AI apps and ~1M datasets
agent will pick and build with the best model for your use case and hardware https://twitter.com/mervenoyann/status/2045816220679537088/photo/1
中文: 如果你正在使用 Replit、Antigravity 或其他氛围构建工具 👋🏻
只需在设置中添加 @huggingface Skills,即可让您的代理能够访问 ~3M 的开放模型、500k+ 本地人工智能应用程序以及 ~1M 数据集
代理将采用最适合您使用的用例和硬件的型号进行选择和构建

92749 粉丝
RT @prithivMLmods: HY-World-2.0 Demo is now live on @huggingface Spaces for 3D world reconstruction and simulation with Gradio and Server m…
中文: RT @prithivMLmods:HY-World-2.0 演示现已在 @huggingface Spaces 上实时上线,通过 Gradio 和 Server m.
92749 粉丝
no shade but it pains me to know that AI isn't replacing hard labor where kids in developing countries are dying in press machines or adults die in mines but rather all the investment is for creative jobs
and the companies doing this claim to change the world yeah go off
中文: 没有遮蔽,但让我痛心地知道,人工智能并不能取代那些发展中国家儿童在印刷机上或成年人在矿井中死亡的辛苦劳动,而所有投资都用于创造性工作
而那些声称要改变世界的公司,是的
92749 粉丝
use GLM-5.1 or MiniMax or Gemma-4
you can't be banned from your servers
中文: 使用 GLM-5.1 或 MiniMax 或 Gemma-4
你的服务器不能被禁止
92749 粉丝
we met @swyx 🐐 @andimarafioti https://twitter.com/mervenoyann/status/2042004372704424284/photo/1
中文: 我们遇到了 @swyx 🐐 @andimarafioti

92749 粉丝
fun blog on fine-tuning gemma 4 and my failures and vibe tests incoming 🔜
中文: 关于微调 gemma 4 的有趣博客,以及我的失败与氛围测试
92749 粉丝
DO NOT SLEEP ON THIS MODEL @Kimi_Moonshot 🤯
Kimi-VL-A3B-Thinking is the first ever capable open-source reasoning VLM with MIT license ❤️
> it has only 2.8B activated params 👏
> it's agentic 🔥
> surpasses gpt-4o
I've put it to test (see below ⤵️) https://twitter.com/mervenoyann/status/1910766909433303342/photo/1

92749 粉丝
I think it's a horrible idea to ask for licenses to train models, this will reduce number of open-source models and will give big corporations an unfair competitive advantage to train closed-source models which will not be transparent at all and companies will have to sacrifice a…
中文: 我认为要求获得培训模型的许可证是一个糟糕的想法,这将减少开源模型的数量,并为大公司提供不公平的竞争优势,以培训完全不透明的闭源模型,而企业将不得不牺牲这种模式。